4D4T-embeddings-all-MiniLM-L6-v2
收藏资源简介:
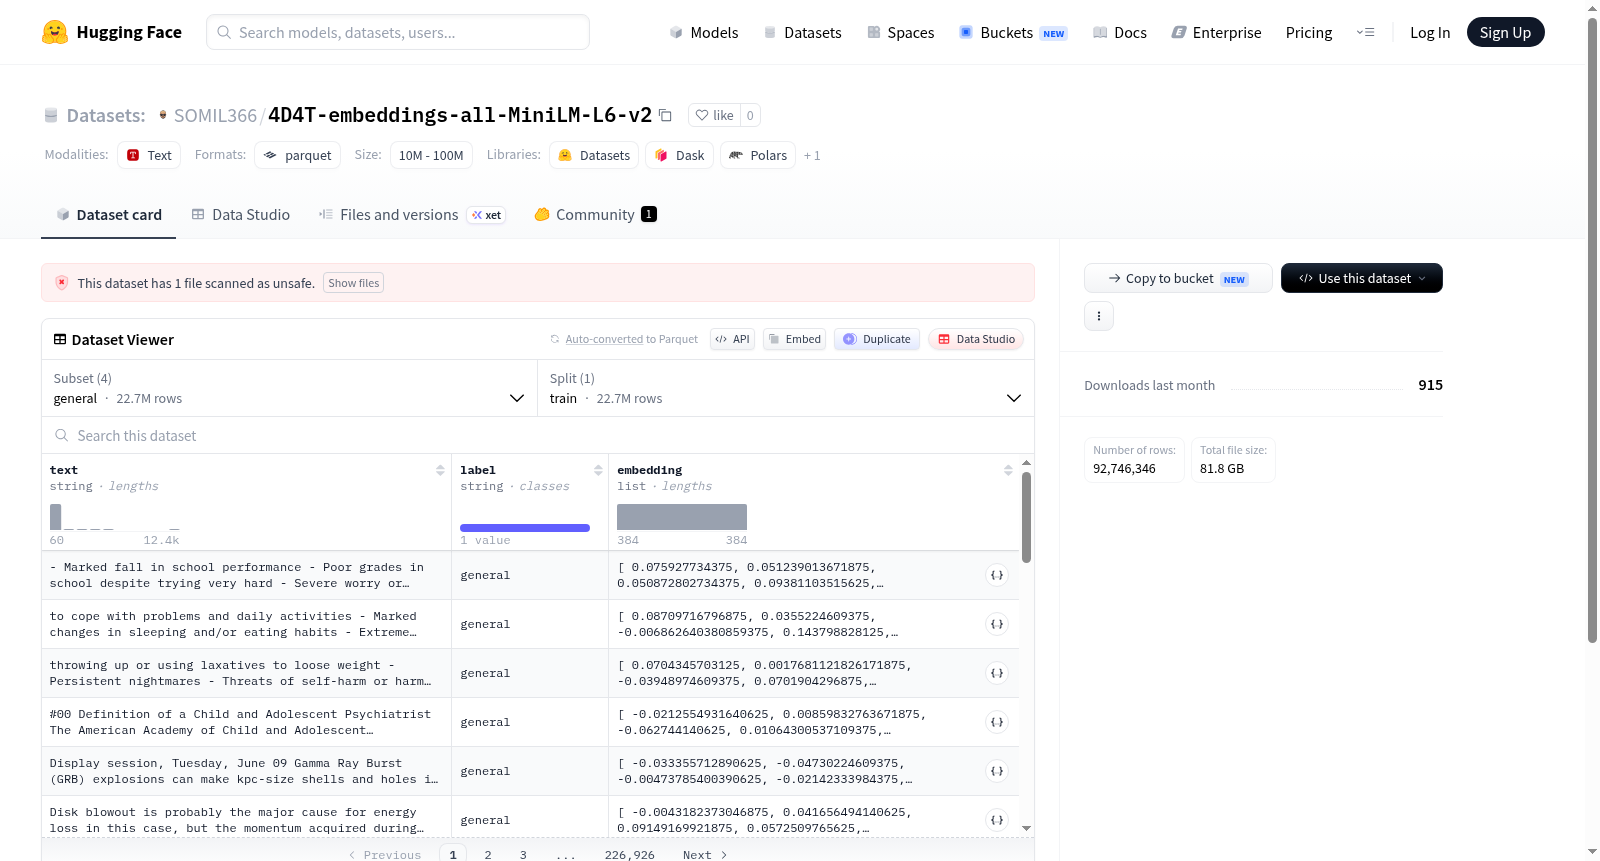
本数据集名为4D4T-embeddings-all-MiniLM-L6-v2,是一个为句子嵌入模型all-MiniLM-L6-v2优化的文本-标签配对样本集合。数据集按领域划分为四个主要部分:数学(math)、通用(general)、历史新闻(history_news)和科学(science),旨在支持跨专业和通用领域的语义搜索、文本分类、聚类以及检索增强生成(RAG)等应用。每个样本包含两个字段:text(原始或预处理的文本内容)和label(关联的类别或领域标签)。数据规模总计约9,274.6万条样本,总大小约26.39 GB,压缩下载大小约14.87 GB,具体拆分规模为:数学约2,203.0万条、通用约2,269.3万条、历史新闻约2,253.7万条、科学约2,548.6万条。数据集可通过Hugging Face datasets库加载特定拆分或全部拆分使用。
The dataset named 4D4T-embeddings-all-MiniLM-L6-v2 contains text-label paired samples optimized for the sentence embedding model all-MiniLM-L6-v2. It is divided into four main domains: math, general, history_news, and science, aiming to support applications such as semantic search, text classification, clustering, and retrieval-augmented generation (RAG) across both specialized and general domains. Each sample includes two fields: text (original or preprocessed text content) and label (associated category or domain label). The total dataset scale is approximately 92.746 million samples, with a total size of about 26.39 GB (compressed download size about 14.87 GB). The specific breakdown of splits is: math about 22.03 million samples, general about 22.693 million samples, history_news about 22.537 million samples, and science about 25.486 million samples. The dataset can be loaded using the Hugging Face datasets library for specific splits or all splits.