video_annotation_pipeline
收藏资源简介:
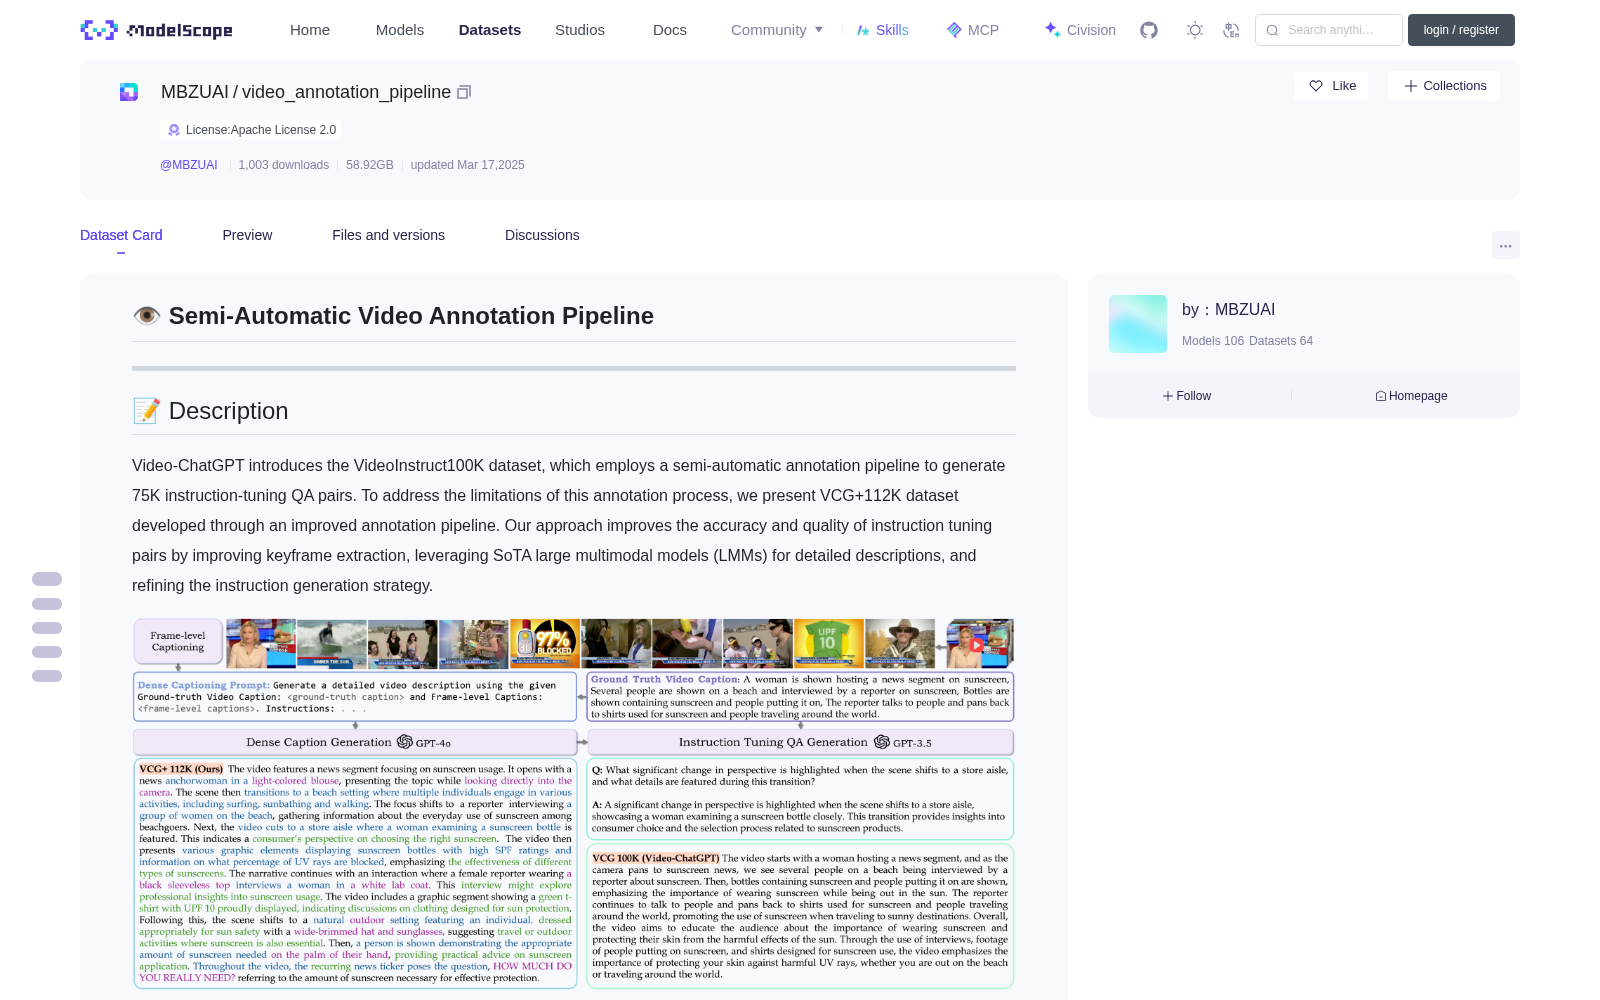
# 👁️ Semi-Automatic Video Annotation Pipeline --- ## 📝 Description Video-ChatGPT introduces the VideoInstruct100K dataset, which employs a semi-automatic annotation pipeline to generate 75K instruction-tuning QA pairs. To address the limitations of this annotation process, we present VCG+112K dataset developed through an improved annotation pipeline. Our approach improves the accuracy and quality of instruction tuning pairs by improving keyframe extraction, leveraging SoTA large multimodal models (LMMs) for detailed descriptions, and refining the instruction generation strategy. <p align="center"> <img src="video_annotation_pipeline.png" alt="Contributions"> </p> ## 💻 Download To get started, follow these steps: ``` git lfs install git clone https://huggingface.co/MBZUAI/video_annotation_pipeline ``` ## 📚 Additional Resources - **Paper:** [ArXiv](https://arxiv.org/abs/2406.09418). - **GitHub Repository:** For training and updates: [GitHub - GLaMM](https://github.com/mbzuai-oryx/VideoGPT-plus). - **HuggingFace Collection:** For downloading the pretrained checkpoints, VCGBench-Diverse Benchmarks and Training data, visit [HuggingFace Collection - VideoGPT+](https://huggingface.co/collections/MBZUAI/videogpt-665c8643221dda4987a67d8d). ## 📜 Citations and Acknowledgments ```bibtex @article{Maaz2024VideoGPT+, title={VideoGPT+: Integrating Image and Video Encoders for Enhanced Video Understanding}, author={Maaz, Muhammad and Rasheed, Hanoona and Khan, Salman and Khan, Fahad Shahbaz}, journal={arxiv}, year={2024}, url={https://arxiv.org/abs/2406.09418} }
# 👁️ 半自动视频标注流程(Semi-Automatic Video Annotation Pipeline) --- ## 📝 数据集描述 Video-ChatGPT 推出了 VideoInstruct100K 数据集,该数据集采用半自动标注流程生成 75K 条指令微调问答(Question Answering, QA)对。为解决该标注流程存在的局限性,我们提出了通过优化标注流程构建的 VCG+112K 数据集。本方法通过优化关键帧提取、借助当前最优(State-of-the-Art, SoTA)大型多模态模型(Large Multimodal Models, LMMs)生成详细描述,并优化指令生成策略,从而提升指令微调问答对的准确性与质量。 <p align="center"> <img src="video_annotation_pipeline.png" alt="研究贡献"> </p> ## 💻 下载方式 如需开展使用,请遵循以下步骤: git lfs install git clone https://huggingface.co/MBZUAI/video_annotation_pipeline ## 📚 补充资源 - **论文:** [ArXiv 预印本](https://arxiv.org/abs/2406.09418)。 - **GitHub 仓库:** 用于模型训练与版本更新:[GitHub - GLaMM](https://github.com/mbzuai-oryx/VideoGPT-plus)。 - **HuggingFace 资源集合:** 如需下载预训练模型权重、VCGBench-Diverse 基准测试集与训练数据,请访问 [HuggingFace 资源集合 - VideoGPT+](https://huggingface.co/collections/MBZUAI/videogpt-665c8643221dda4987a67d8d)。 ## 📜 引用与致谢 bibtex @article{Maaz2024VideoGPT+, title={VideoGPT+: Integrating Image and Video Encoders for Enhanced Video Understanding}, author={Maaz, Muhammad and Rasheed, Hanoona and Khan, Salman and Khan, Fahad Shahbaz}, journal={arxiv}, year={2024}, url={https://arxiv.org/abs/2406.09418} }