flax-community/conceptual-12m-multilingual-marian-128
收藏资源简介:
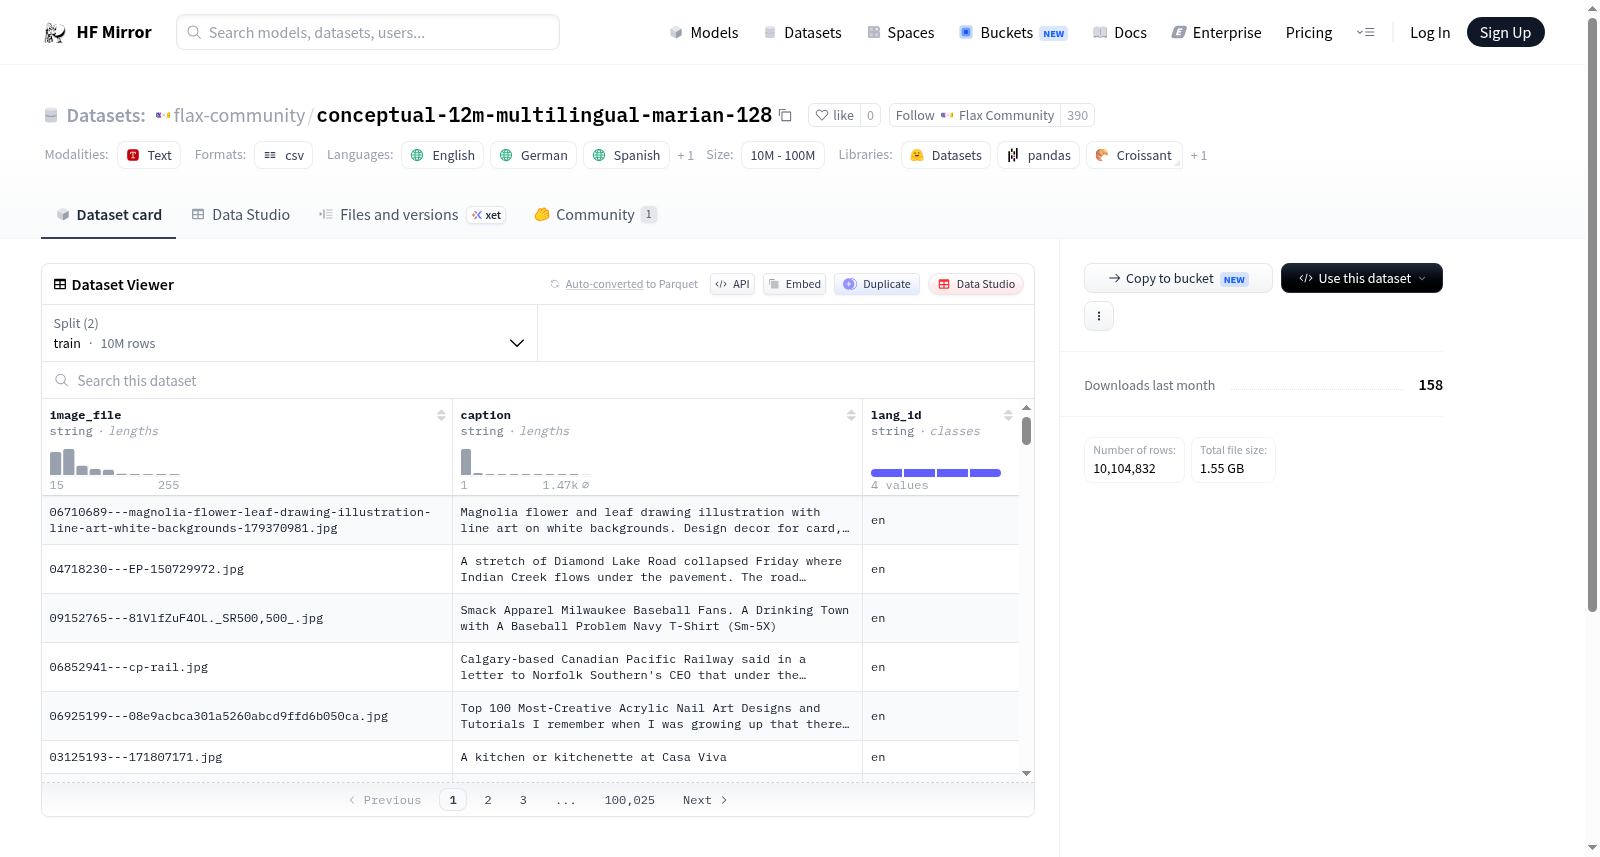
--- language: - en - de - es - fr --- This dataset is created from subset of [Conceptual Captions](https://ai.google.com/research/ConceptualCaptions/). The original dataset has 12M captions but this dataset has around 10M image, caption pairs in different languages with 2.5M unique images. This dataset has captions translated from English to Spanish, German, French using language specific English to [Marian](https://huggingface.co/Helsinki-NLP) models (with sequence length 128). Data distribution is following: `train_file_marian_final.tsv`: 10002432 captions (2500608 captions of English, German, Spanish, French each) <br /> `val_file_marian_final.tsv`: 102400 captions (25600 captions of English, German, Spanish, French each)
语言: - 英语 - 德语 - 西班牙语 - 法语 本数据集取材自[概念性标题数据集(Conceptual Captions)](https://ai.google.com/research/ConceptualCaptions/)的子集。原始数据集包含1200万条图像标题,本数据集则收录了约1000万条跨语言图像-标题配对样本,对应250万张独特图像。 本数据集的标题通过针对各目标语言的英语至[马里安机器翻译模型(Marian)](https://huggingface.co/Helsinki-NLP)模型(序列长度设置为128),从英语翻译为西班牙语、德语与法语。 数据分布详情如下: `train_file_marian_final.tsv`:共计10002432条标题(英语、德语、西班牙语、法语各2500608条) `val_file_marian_final.tsv`:共计102400条标题(英语、德语、西班牙语、法语各25600条)
数据集概述
数据来源
- 该数据集是从Conceptual Captions的子集中创建的。
数据规模
- 原始数据集包含1200万条描述,而该数据集包含约1000万对图像和描述,其中有250万张独特的图像。
语言支持
- 数据集包含英语、德语、西班牙语和法语的描述。
- 描述从英语翻译成西班牙语、德语和法语,使用特定语言的英语到Marian模型(序列长度为128)。
数据分布
train_file_marian_final.tsv: 包含10002432条描述(每种语言各2500608条)。val_file_marian_final.tsv: 包含102400条描述(每种语言各25600条)。