laion-voice-profiles-sft
收藏资源简介:
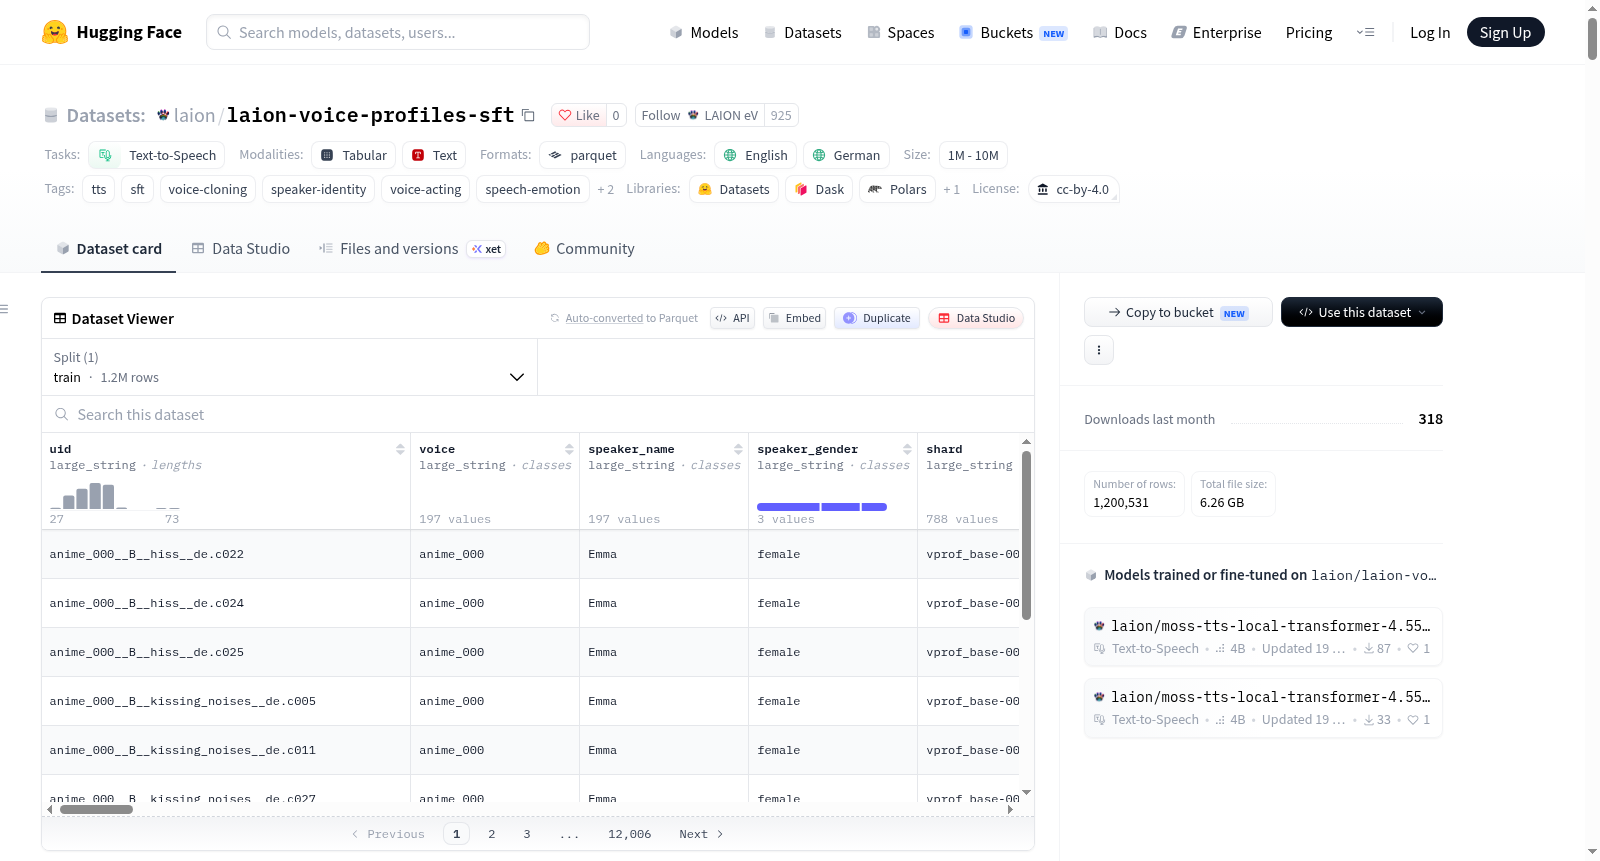
LAION Voice Profiles — TTS监督微调集是一个用于参考条件文本转语音(TTS)的大规模指令微调数据集。该数据集包含1,200,531个样本,源自500个合成语音档案,每个档案包含842个表演条件组,每组48个候选样本,仅保留基于情感强度、真实感和混合度评分最高的3个样本。每个样本均以MOSS音频标记器v2的码本形式提供(12个码本,帧率为12.5fps),而非原始波形。数据集支持两种条件模式:参考音频+描述,或说话者名称,分别用于语音克隆和语音记忆训练。数据规模为6.3 GB,语言包含英语和德语。数据选择过程详细说明了评分公式(情感强度权重加倍)、参考剪辑的余弦相似度阈值(≥0.60)以及避免固定配对的设计。此外,数据集还提供了独立的程序化描述生成机制,以纠正原始注释中的错误,如极性反转和情感门控问题。该数据集适用于语音克隆、个性化TTS、情感语音合成等任务。
LAION Voice Profiles — TTS Supervised Fine-tuning Set is a large-scale instruction fine-tuning dataset for reference-conditioned text-to-speech (TTS). It contains 1,200,531 samples derived from 500 synthetic voice profiles, each with 842 performance condition groups, and each group having 48 candidate samples, retaining only the top 3 samples based on scores for emotional intensity, realism, and blending. Each sample is provided in the form of MOSS Audio Tokenizer v2 codebooks (12 codebooks, frame rate 12.5fps), not raw waveforms. The dataset supports two conditioning modes: reference audio + description, or speaker name, for voice cloning and voice memory training respectively. Data size is 6.3 GB, with languages including English and German. The data selection process details a scoring formula (emotional intensity weight doubled), cosine similarity threshold for reference clips (≥0.60), and design to avoid fixed pairings. Additionally, the dataset provides an independent programmatic description generation mechanism to correct errors in original annotations, such as polarity reversal and emotional gating issues. This dataset is suitable for tasks such as voice cloning, personalized TTS, and emotional speech synthesis.