TuringEnterprises/Turing-Open-Reasoning
收藏资源简介:
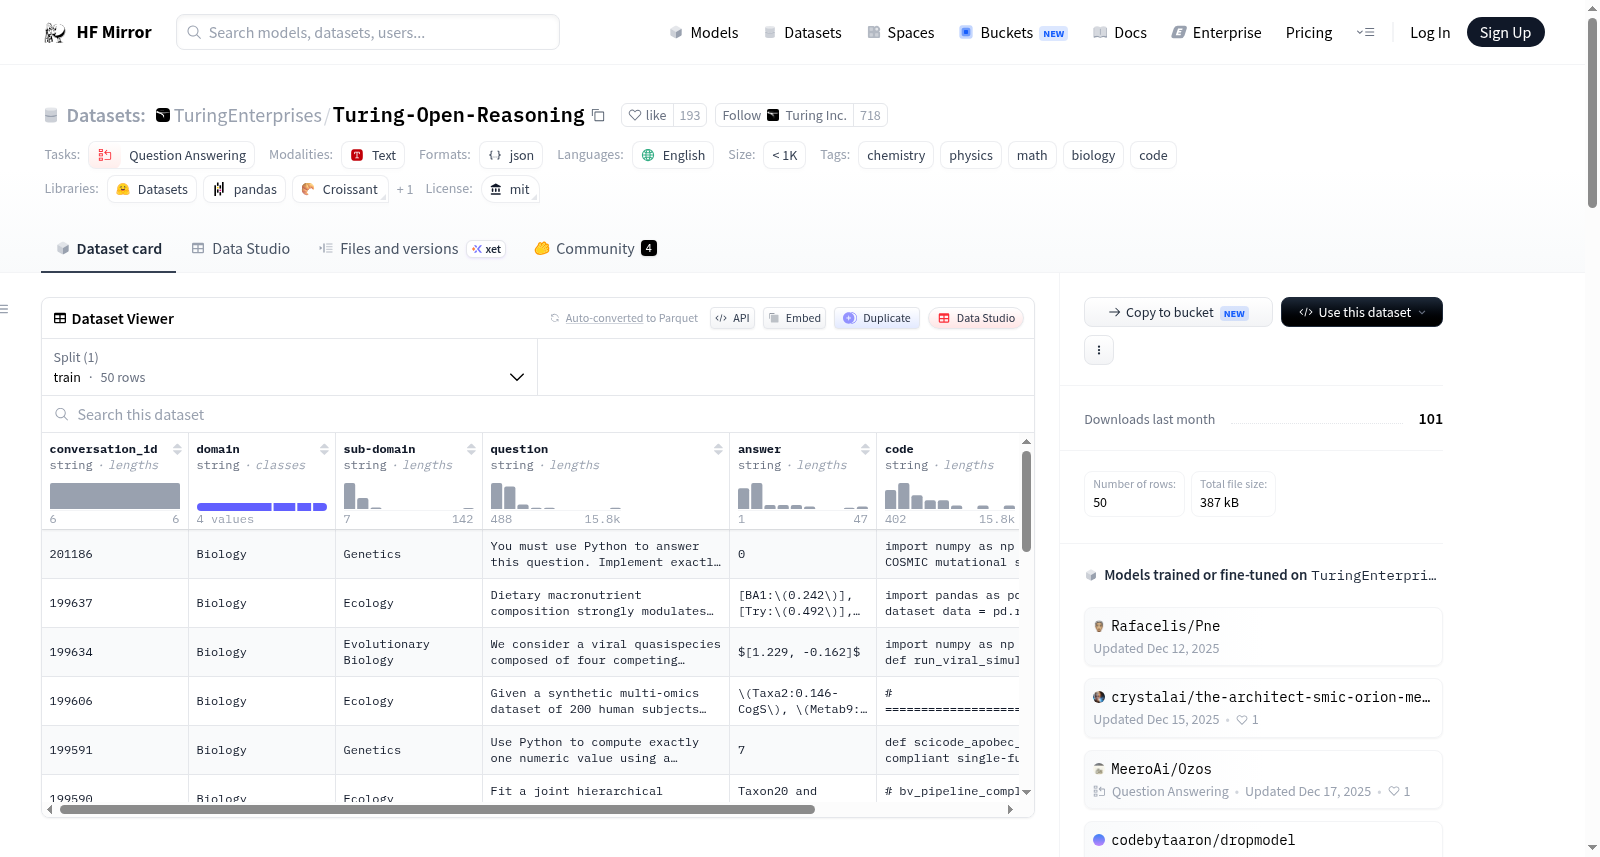
--- license: mit language: - en tags: - chemistry - physics - math - biology - code pretty_name: sci-or size_categories: - n<1K task_categories: - question-answering --- # Computational STEM QA Dataset [](https://opensource.org/licenses/MIT) [](https://turing.com) ## Dataset Summary This dataset contains **computationally intensive, self-contained, and unambiguous STEM reasoning problems** across Physics, Mathematics, Biology, and Chemistry. Problems require multi-step reasoning, symbolic manipulation, numerical accuracy, or simulation-based verification. These tasks expose failure modes in **state-of-the-art LLMs**, making this dataset a strong benchmark for evaluating deep reasoning. Each example includes: - `conversation_id` - `domain` and `sub-domain` - A rigorous **question** with LaTeX - A deterministic **answer` - Optional **Python code** for simulation or verification ## Dataset Structure | Field | Type | Description | |-------|------|-------------| | `conversation_id` | string | Unique identifier for each QA pair. | | `domain` | string | Physics, Math, Chemistry, Biology. | | `sub-domain` | string | Specific discipline. | | `question` | string | STEM problem statement. | | `answer` | string | Correct solution. | | `code` | string | Full Python code. | ## Example ``` { "conversation_id": "201186", "domain": "Physics", "sub-domain": "Classical Mechanics", "question": "A block of mass m slides down a frictionless incline... Compute the acceleration using $a = g \sin(\theta)$.", "answer": "Using Newton's laws, the acceleration is $a = g \sin(\theta)$.", "code": "import math\ng = 9.81\ntheta = math.radians(30)\na = g * math.sin(theta)\nprint(a)" } ``` ## Dataset Characteristics - Self-contained and unambiguous - Heavy use of LaTeX in STEM reasoning - All examples require precise computation and can not be solved analytically - Designed to stress-test LLM reasoning - Full python code to solve the problem ## Dataset Format This dataset is provided in **standard JSON format as a top-level array** containing all problem records. Example: ``` [ {"conversation_id": "1", "domain": "Physics", "sub-domain": "Mechanics", "question": "...", "answer": "...", "code": "..."}, {"conversation_id": "2", "domain": "Math", "sub-domain": "Algebra", "question": "...", "answer": "...", "code": "..."} ] ``` ## Intended Uses - Fine-tuning STEM reasoning models - Evaluating LLM computation accuracy - Benchmarking symbolic + numeric reasoning - Developing STEM tutoring agents - Creating reward models requiring strict correctness ## Limitations - Numeric results may vary slightly due to floating point behavior - Python code assumes availability of only `numpy`,`scipy` `pandas`libraries - Some models may require preprocessing of LaTeX ## Citation ``` @dataset{saurabh_2025_stemqa, title = {Computational STEM QA Dataset}, author = {Saurabh Patil,Anshuman Lall,Marko Pavlovic,Tejas Ukarde,Chinmayee Shukla,Mahesh Joshi,Kihwan Han}, year = {2025}, url = {https://huggingface.co/datasets/TuringEnterprises/Turing-Open-Reasoning/} } ```
license: MIT许可证 language: - 英语 tags: - 化学 - 物理学 - 数学 - 生物学 - 代码 pretty_name: sci-or size_categories: - 样本数少于1000 task_categories: - 问答 # 计算型STEM问答数据集 [](https://opensource.org/licenses/MIT) [](https://turing.com) ## 数据集概述 本数据集涵盖物理学、数学、生物学与化学领域的**计算密集型、自包含且无歧义的STEM推理问题**。 此类问题需要多步推理、符号运算、数值精度校验或基于模拟的验证。这些任务能够暴露**当前最优大语言模型(Large Language Model, LLM)**的失效模式,因此本数据集可作为评估深度推理能力的优质基准。 每个样本包含以下内容: - `conversation_id`:对话唯一标识符 - 领域(`domain`)与子领域(`sub-domain`) - 带有LaTeX格式的严谨**问题** - 确定的**答案** - 可选的用于模拟或验证的**Python代码** ## 数据集结构 | 字段名 | 数据类型 | 字段说明 | |-------|---------|---------| | `conversation_id` | 字符串 | 每个问答对的唯一标识符 | | `domain` | 字符串 | 涵盖物理学、数学、化学、生物学 | | `sub-domain` | 字符串 | 具体细分学科 | | `question` | 字符串 | STEM问题描述 | | `answer` | 字符串 | 正确解答 | | `code` | 字符串 | 完整Python代码 | ## 示例 { "conversation_id": "201186", "domain": "Physics", "sub-domain": "Classical Mechanics", "question": "A block of mass m slides down a frictionless incline... Compute the acceleration using $a = g sin( heta)$.", "answer": "Using Newton's laws, the acceleration is $a = g sin( heta)$.", "code": "import math g = 9.81 theta = math.radians(30) a = g * math.sin(theta) print(a)" } ## 数据集特性 - 自包含且无歧义 - 在STEM推理中大量使用LaTeX格式 - 所有样本均需精确计算,无法通过解析法求解 - 专为对大语言模型的推理能力进行压力测试而设计 - 附带用于求解问题的完整Python代码 ## 数据集格式 本数据集以**标准JSON格式**提供,顶层为包含所有问题记录的数组。 示例: [ {"conversation_id": "1", "domain": "Physics", "sub-domain": "Mechanics", "question": "...", "answer": "...", "code": "..."}, {"conversation_id": "2", "domain": "Math", "sub-domain": "Algebra", "question": "...", "answer": "...", "code": "..."} ] ## 预期用途 - 微调STEM推理模型 - 评估大语言模型的计算精度 - 为符号与数值推理能力构建基准测试 - 开发STEM辅导AI智能体(AI Agent) - 构建需要严格正确性的奖励模型 ## 局限性 - 由于浮点运算特性,数值结果可能存在细微差异 - Python代码仅假设环境中已安装`numpy`、`scipy`与`pandas`库 - 部分模型可能需要对LaTeX格式内容进行预处理 ## 引用 @dataset{saurabh_2025_stemqa, title = {Computational STEM QA Dataset}, author = {Saurabh Patil,Anshuman Lall,Marko Pavlovic,Tejas Ukarde,Chinmayee Shukla,Mahesh Joshi,Kihwan Han}, year = {2025}, url = {https://huggingface.co/datasets/TuringEnterprises/Turing-Open-Reasoning/} }