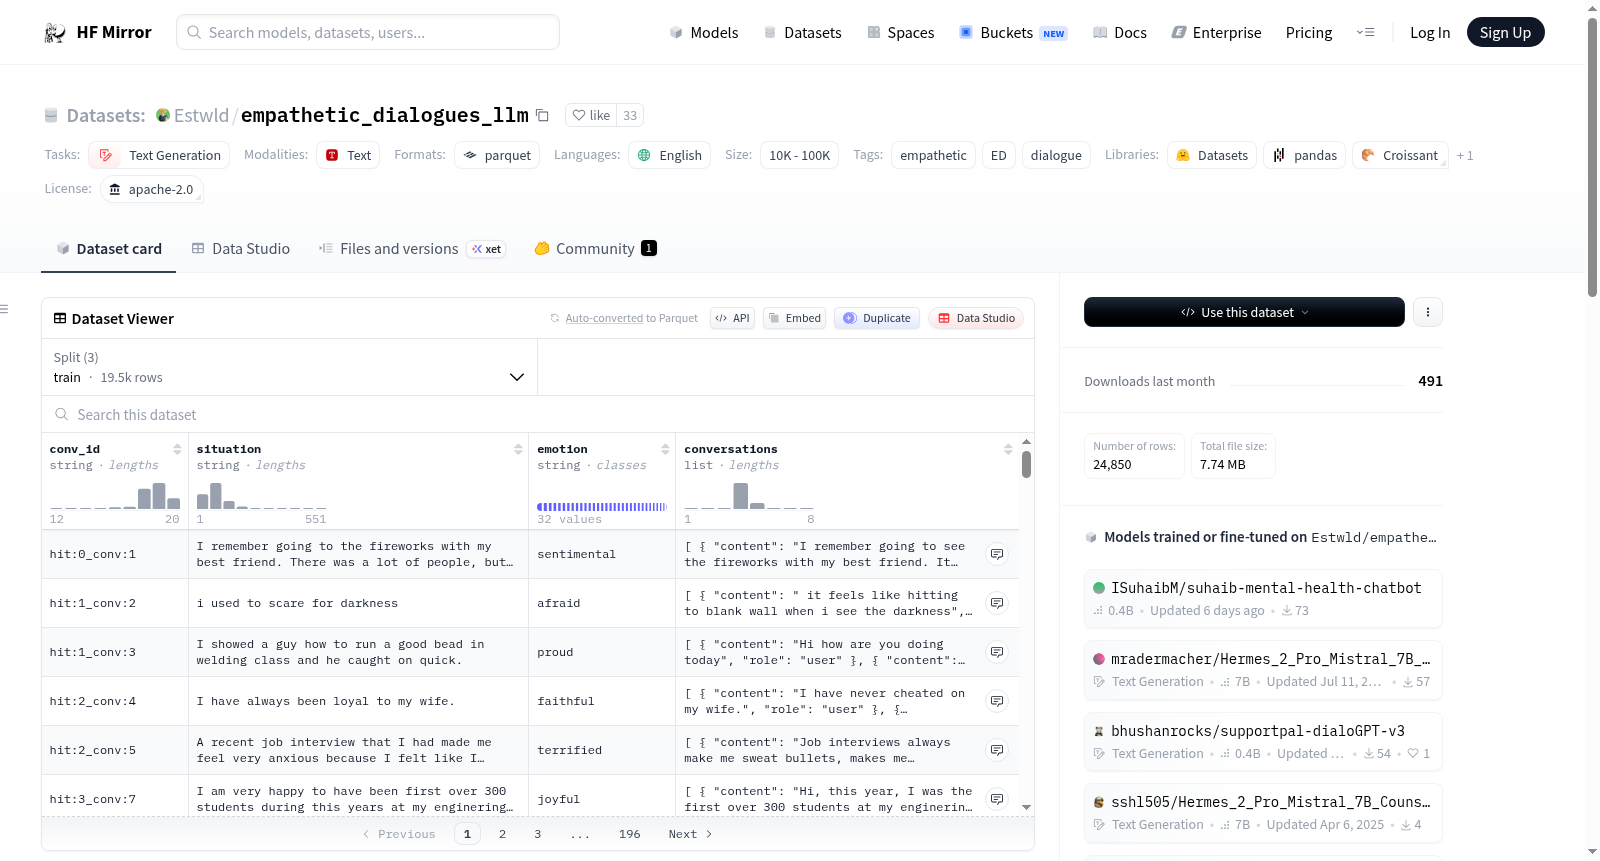
Estwld/empathetic_dialogues_llm
收藏资源简介:
--- language: - en license: apache-2.0 size_categories: - 10K<n<100K task_categories: - text-generation dataset_info: features: - name: conv_id dtype: string - name: situation dtype: string - name: emotion dtype: string - name: conversations list: - name: content dtype: string - name: role dtype: string splits: - name: train num_bytes: 9321699 num_examples: 19533 - name: valid num_bytes: 1417106 num_examples: 2770 - name: test num_bytes: 1386509 num_examples: 2547 download_size: 6827416 dataset_size: 12125314 configs: - config_name: default data_files: - split: train path: data/train-* - split: valid path: data/valid-* - split: test path: data/test-* tags: - empathetic - ED - dialogue --- # Empathetic Dialogues for LLM This repository contains a reformatted version of the Empathetic Dialogues dataset, tailored for seamless integration with Language Model (LLM) training and inference. The original dataset's format posed challenges for direct application in LLM tasks, prompting us to restructure and clean the data. ## Data Restructuring We have implemented the following changes to enhance the dataset's usability: 1. Merged dialogues with the same `conv_id`, treating each `conv_id` as an independent dialogue session. 2. Assigned the `user` role to the initiator of each dialogue session, followed by `assistant` for the subsequent message, and so on, alternating between the two roles. 3. Retained the original `conv_id`, `emotion`, and `situation` fields to facilitate the construction of instructions. 4. Removed the `utterance_id`, `selfeval`, and `tags` fields to streamline the data. 5. Replaced instances of `'_comma_'` with `','` for improved readability. ## Data Format Each entry in the reformatted dataset consists of the following fields: - `conversations`: A list of dictionaries, where each dictionary represents a turn in the dialogue and contains: - `role`: A string indicating the speaker's role, either `user` or `assistant`. - `content`: A string containing the dialogue content. - `conv_id`: A string representing the unique identifier for the dialogue session. - `emotion`: A string indicating the emotional label associated with the dialogue (corresponds to the `context` field in the original dataset). - `situation`: A string describing the situational label for the dialogue (corresponds to the `prompt` field in the original dataset). ## Important Note In the original Empathetic Dialogues dataset, not all dialogue sessions have an even number of conversation turns. To maintain the integrity of the dataset, we have preserved this characteristic in our reformatted version. However, this peculiarity may lead to potential bugs when directly applying the dataset to LLM training or inference. Users should be mindful of this aspect when working with the data. ## Dataset Statistics | Dataset | Total Turn | Average Turn | Average Length | |-------------|------------|--------------|----------------| | Train | 84,167 | 4.309 | 13.589 | | Validation | 12,077 | 4.360 | 14.685 | | Test | 10,972 | 4.308 | 15.499 |
语言: - 英语 许可证:Apache-2.0 样本规模类别: - 10K<n<100K 任务类别: - 文本生成 数据集信息: 字段列表: - 会话ID(conv_id):数据类型为字符串 - 场景(situation):数据类型为字符串 - 情绪(emotion):数据类型为字符串 - 对话列表(conversations):列表类型,内部元素包含: - 内容(content):数据类型为字符串 - 角色(role):数据类型为字符串 数据集划分: - 训练集(train):字节数9321699,样本数量19533 - 验证集(valid):字节数1417106,样本数量2770 - 测试集(test):字节数1386509,样本数量2547 下载大小:6827416 数据集总大小:12125314 配置项: - 默认配置(default): 数据文件路径: - 训练集:data/train-* - 验证集:data/valid-* - 测试集:data/test-* 标签: - 共情式 - ED - 对话 # 面向大语言模型(LLM)的共情式对话数据集 本仓库包含重构后的共情式对话(Empathetic Dialogues)数据集,专为适配大语言模型(LLM)的训练与推理流程而优化。原始数据集的格式无法直接应用于大语言模型任务,因此我们对其进行了结构化重构与数据清洗。 ## 数据重构 我们实施了以下优化以提升数据集的易用性: 1. 合并具有相同`conv_id`的对话,将每个`conv_id`视为独立的对话会话。 2. 为每个对话会话的发起者分配`user`(用户)角色,后续消息依次交替使用`assistant`(助手)与用户角色。 3. 保留原始的`conv_id`、`emotion`与`situation`字段,便于后续指令构建。 4. 移除了`utterance_id`、`selfeval`与`tags`字段以精简数据结构。 5. 将所有`'_comma_'`替换为`','`,提升文本可读性。 ## 数据格式 重构后的数据集每条数据包含以下字段: - `conversations`:由字典组成的列表,每个字典代表一轮对话,包含: - `role`:字符串类型,表示发言者角色,可选值为`user`(用户)或`assistant`(助手)。 - `content`:字符串类型,包含对话内容。 - `conv_id`:字符串类型,表示对话会话的唯一标识符。 - `emotion`:字符串类型,表示该对话对应的情绪标签(对应原始数据集中的`context`字段)。 - `situation`:字符串类型,表示该对话对应的场景标签(对应原始数据集中的`prompt`字段)。 ## 重要说明 在原始共情式对话数据集中,并非所有对话会话的轮次均为偶数。为保持数据集的原始完整性,我们在重构版本中保留了这一特性。但该特性可能在直接将数据集用于大语言模型训练或推理时引发潜在问题,使用者在处理该数据时需留意这一点。 ## 数据集统计信息 | 数据集划分 | 总对话轮次 | 平均每会话轮次 | 平均文本长度 | |------------|------------|----------------|--------------| | 训练集 | 84,167 | 4.309 | 13.589 | | 验证集 | 12,077 | 4.360 | 14.685 | | 测试集 | 10,972 | 4.308 | 15.499 |
数据集概述
基本信息
- 语言: 英语
- 许可证: Apache 2.0
- 数据集大小: 10K<n<100K
- 任务类别: 文本生成
数据集结构
特征
conv_id: 字符串类型,对话的唯一标识符。situation: 字符串类型,对话的情境描述。emotion: 字符串类型,对话的情感标签。conversations: 列表类型,包含以下字段:content: 字符串类型,对话内容。role: 字符串类型,说话者的角色,可以是user或assistant。
数据分割
train: 包含 19533 个样本,总字节数为 9321699。valid: 包含 2770 个样本,总字节数为 1417106。test: 包含 2547 个样本,总字节数为 1386509。
下载和数据集大小
- 下载大小: 6827416 字节
- 数据集大小: 12125314 字节
数据集配置
- 配置名称: default
- 数据文件:
train: 路径为data/train-*valid: 路径为data/valid-*test: 路径为data/test-*
标签
empatheticEDdialogue
数据重构
改进措施
- 合并具有相同
conv_id的对话,将每个conv_id视为独立的对话会话。 - 为每个对话会话的初始者分配
user角色,后续消息分配assistant角色,以此类推,交替分配角色。 - 保留原始的
conv_id、emotion和situation字段,以方便构建指令。 - 删除
utterance_id、selfeval和tags字段,以简化数据。 - 将
_comma_替换为,,以提高可读性。
数据格式
每个条目包含以下字段:
conversations: 一个字典列表,每个字典表示对话中的一轮,包含:role: 字符串类型,表示说话者的角色,可以是user或assistant。content: 字符串类型,包含对话内容。
conv_id: 字符串类型,表示对话会话的唯一标识符。emotion: 字符串类型,表示与对话相关的情感标签。situation: 字符串类型,表示对话的情境标签。
重要提示
在原始的 Empathetic Dialogues 数据集中,并非所有对话会话都有偶数轮对话。为了保持数据集的完整性,我们在重构版本中保留了这一特性。然而,这一特点可能导致在直接应用于语言模型训练或推理时出现潜在错误。用户在使用数据时应留意这一方面。
数据集统计
| 数据集 | 总轮数 | 平均轮数 | 平均长度 |
|---|---|---|---|
| Train | 84,167 | 4.309 | 13.589 |
| Validation | 12,077 | 4.360 | 14.685 |
| Test | 10,972 | 4.308 | 15.499 |