auren-research/astraea-unified-threat
收藏资源简介:
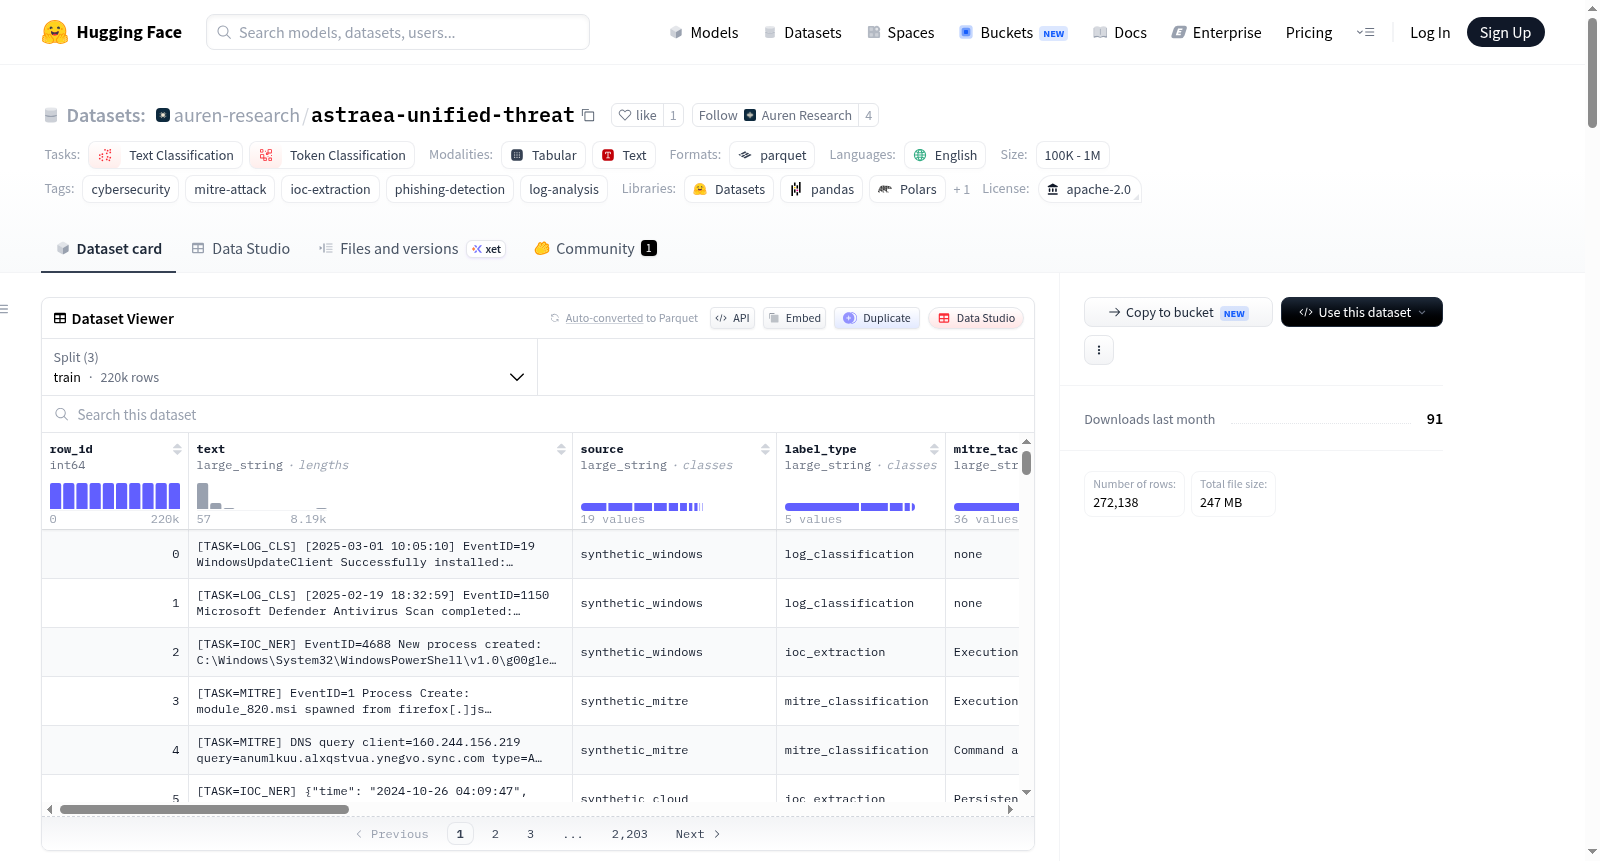
Astraea统一威胁数据集(v4)是由Auren Research开发的一个高度优化、生产平衡的遥测数据集,专为微调现代多任务编码器架构(如chandar-lab/NeoBERT和answerdotai/ModernBERT)而设计。该数据集通过将原始事件流聚合为按时间顺序排列的多行会话,使编码器模型能够学习长上下文时间相关性、计算连续异常分数,并对妥协指标(IOC)执行令牌级命名实体识别。数据集包含274,778行按时间顺序会话化的日志流,类别平衡(is_malicious)为44.7%,以模拟真实世界生产环境;平均异常得分为0.458;已验证的IOC跨度为1,136,768个字符偏移;覆盖822种独特的MITRE技术;语言为100%英语;格式为Parquet(zstd压缩),压缩后大小为132.0 MB。技术特点包括:2026年威胁向量遥测,涵盖现代企业攻击面;良性背景基线,包含140,000个基线企业会话;令牌边界模糊化,以强制行为模式学习。数据模式包含12个结构化列,如row_id、text、source、label_type等,用于统一的多头架构训练。
Developed by Auren Research, Astraea Unified Threat (v4) is a highly optimized, production-balanced telemetry dataset engineered for fine-tuning modern multi-task encoder architectures (such as chandar-lab/NeoBERT and answerdotai/ModernBERT). By aggregating raw event streams into chronological multi-line sessions, Astraea enables encoder models to learn long-context temporal correlations, compute continuous anomaly scores, and perform token-level named entity recognition (NER) on indicators of compromise. The dataset includes 274,778 rows of chronological sessionized log streams with a class balance (is_malicious) of 44.7%, a mean anomaly score of 0.458, 1,136,768 validated IOC spans, coverage of 822 unique MITRE techniques, 100% English language, and a compressed Parquet (zstd) format of 132.0 MB. Technical features incorporate 2026 threat vector telemetry, benign background baseline sessions, and token boundary fuzzing. The data schema consists of 12 structured columns for unified multi-head architecture training.