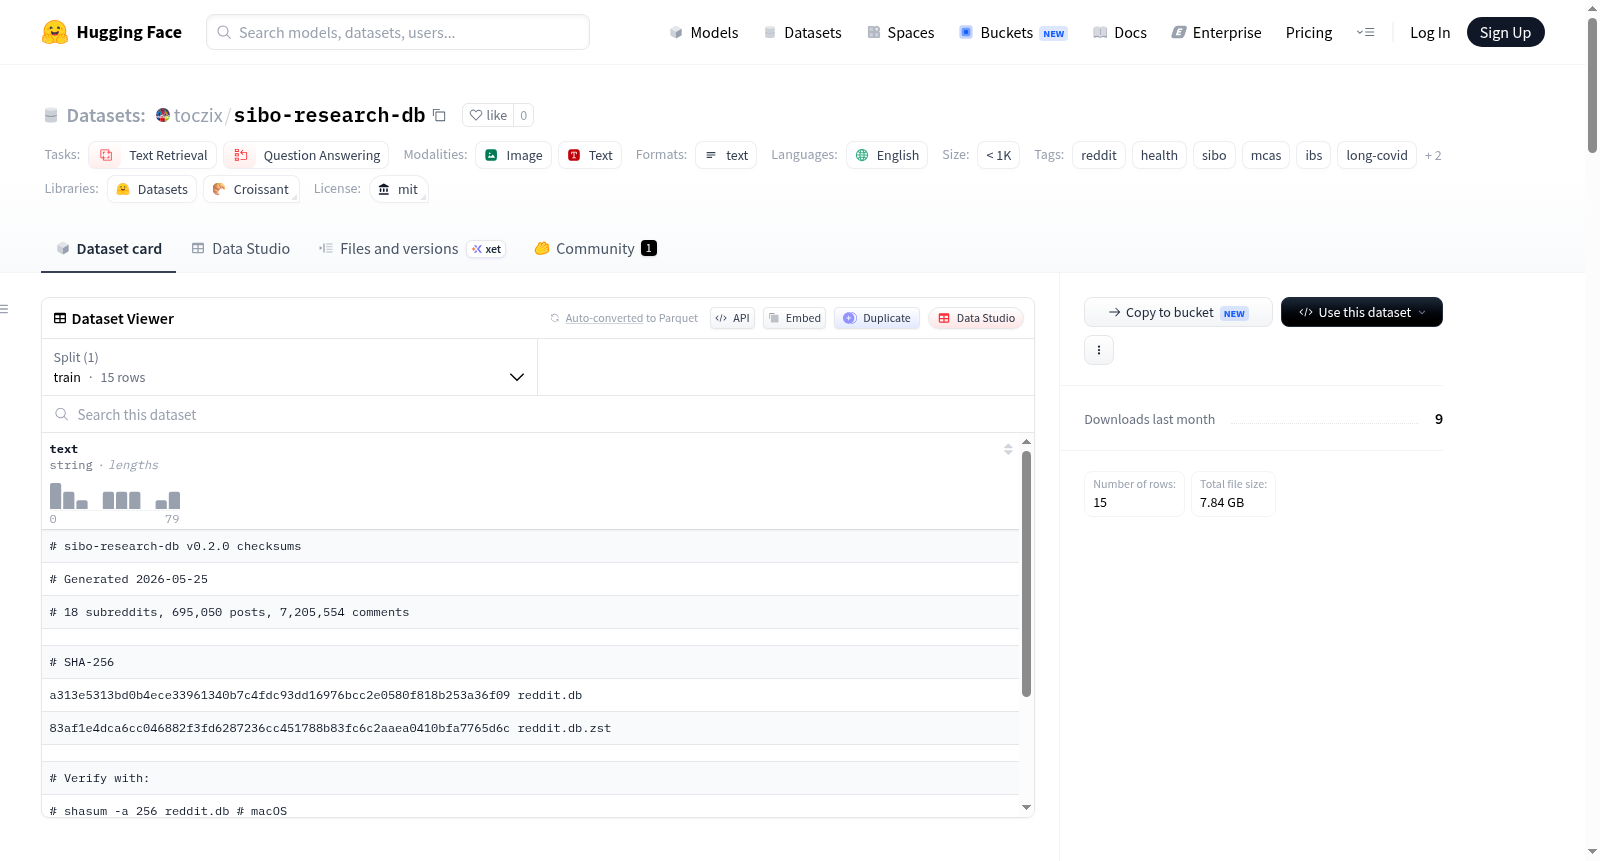
sibo-research-db
收藏资源简介:
SIBO Research DB 是一个专注于慢性健康问题的 Reddit 公开内容数据集,旨在为 AI 辅助的研究和对话式查询提供支持。该数据集汇集了来自 18 个特定健康主题 Reddit 社区(子版块)的讨论,涵盖小肠细菌过度生长(SIBO)、肠易激综合征(IBS)、肥大细胞激活综合征(MCAS)、长新冠(Long COVID)、微生物组(Microbiome)等多种慢性疾病和健康话题。数据集包含总计约 69.5 万条帖子和 720.5 万条评论,数据规模在百万到千万级别。数据以 SQLite 数据库文件形式提供,预置了全文搜索索引,便于直接查询。数据库结构清晰,包含 `posts`(帖子)和 `comments`(评论)两个主表,记录了发帖人、所属子版块、标题/正文、得分、创建时间、永久链接等丰富字段。该数据集特别设计用于与 AI 工具(如 Claude Code、Cursor 等)结合,允许用户以自然语言对话的方式,在海量患者自述的经验中寻找与自身症状相似的模式、尝试过的治疗方案或补充剂信息。需要强调的是,数据集内容均为患者自我报告的经验分享,并非临床医疗数据或医疗建议。其主要用途是帮助用户发现值得与专业医疗人员进一步探讨的线索和模式,而非用于自我诊断或治疗。数据集适用于文本检索、信息提取、患者报告结果分析以及基于真实世界经验的健康问答等研究场景。
SIBO Research DB is a public Reddit content dataset focused on chronic health issues, designed to support AI-assisted research and conversational queries. It aggregates discussions from 18 specific health-themed Reddit communities (subreddits), covering various chronic diseases and health topics such as Small Intestinal Bacterial Overgrowth (SIBO), Irritable Bowel Syndrome (IBS), Mast Cell Activation Syndrome (MCAS), Long COVID, and Microbiome. The dataset includes approximately 695,000 posts and 7.205 million comments, with a data scale in the millions to tens of millions range. Data is provided in SQLite database format with pre-built full-text search indexes for easy querying. The database has a clear structure, containing two main tables: `posts` and `comments`, which record rich fields such as author, subreddit, title/body, score, creation time, and permalink. The dataset is specifically designed for integration with AI tools (e.g., Claude Code, Cursor), allowing users to search through vast amounts of patient-reported experiences using natural language conversations to find patterns similar to their own symptoms, tried treatments, or supplement information. It is emphasized that the dataset content consists of patient self-reported experiences and is not clinical medical data or medical advice. Its primary purpose is to help users identify clues and patterns worth further discussion with healthcare professionals, rather than for self-diagnosis or treatment. The dataset is suitable for research scenarios such as text retrieval, information extraction, patient-reported outcome analysis, and health question-answering based on real-world experiences.
数据集概述
该数据集名为 SIBO Research DB(SIBO Reddit Research Database),是一个专注于慢性疾病患者社群公开Reddit内容的SQLite数据库,旨在支持通过AI工具进行对话式查询,以发现症状相关的模式和治疗线索。
数据集分类与许可
- 许可协议: MIT License
- 任务类别: 文本检索、问答
- 语言: 英语
- 数据集规模: 1,000,000 ~ 10,000,000 条记录(约700万条评论)
- 标签: reddit、健康、SIBO、MCAS、IBS、长新冠、微生物组、患者报告结局
数据来源与构成
- 来源: 从公共Reddit存档 arctic-shift 抓取。
- 子版块与数据量:
| 子版块 | 主题 | 评论数 |
|---|---|---|
| r/covidlonghaulers | 长新冠 | 1,883,928 |
| r/Supplements | 补充剂方案 | 894,256 |
| r/ibs | 肠易激综合征 | 892,121 |
| r/SIBO | 小肠细菌过度生长 | 710,128 |
| r/MCAS | 肥大细胞活化 | 558,683 |
| r/dysautonomia | POTS/自主神经紊乱 | 433,599 |
| r/Microbiome | 肠道微生物组 | 313,367 |
| r/LongCovid | 长新冠(备选社区) | 257,465 |
| r/Candida | 念珠菌过度生长 | 251,539 |
| r/FODMAPS | 低FODMAP饮食 | 249,222 |
| r/HistamineIntolerance | 组胺不耐受 | 227,376 |
| r/FoodAllergies | 食物过敏 | 203,735 |
| r/ToxicMoldExposure | 霉菌病 | 188,293 |
| r/GutHealth | 肠道健康(综合) | 57,892 |
| r/Longcovidgutdysbiosis | 长新冠+肠道重叠 | 36,437 |
| r/FunctionalMedicine | 功能医学 | 28,322 |
| r/LeakyGutSyndrome | 肠漏综合征 | 11,890 |
| r/SiboSuccessStories | 康复故事 | 7,301 |
- 总量: 18个子版块,共695,050篇帖子,7,205,554条评论。
- 时间覆盖: 大致从各子版块创建至2026年5月(r/ibs和r/Supplements限于2021年之后)。
文件与大小
| 文件 | 大小 | 说明 |
|---|---|---|
reddit.db |
5.4 GB | SQLite数据库,包含全文搜索索引,可直接使用。 |
reddit.db.zst |
1.86 GB | 同上数据库的压缩版本(比原文件小66%),需用zstd解压。 |
checksums.txt |
530 B | 上述两个文件的SHA-256校验值。 |
用户只需选择上述文件之一。
数据库结构与使用方法
- 数据库类型: SQLite,包含FTS5全文搜索虚拟表。
- 表结构:
posts表: 字段包括 id, subreddit, author, title, selftext, score, num_comments, created_utc, permalink, link_flair_text, domain, is_self。comments表: 字段包括 id, subreddit, author, body, score, created_utc, link_id, parent_id, permalink。
- 全文搜索: 通过
posts_fts(title, selftext)和comments_fts(body)实现。 - 查询示例: 可使用Python的sqlite3模块直接进行SQL查询,例如查询与“prucalopride”和“tolerance”相关的评论。
安装与使用建议
- 快速安装: 将GitHub仓库和Hugging Face数据集链接提供给Claude Code或Codex CLI等AI工具,工具会自动下载并安装5.4 GB数据库。
- 最佳实践: 建议用户将个人医疗时间线文档与数据集一同提供给AI工具,以获得针对性分析,而非通用建议。GitHub仓库提供个人时间线模板。
- 非AI使用: 可直接通过SQLite客户端查询数据库。
验证方法
下载后可使用以下命令验证数据完整性:
sqlite3 reddit.db "PRAGMA integrity_check;"应输出 “ok”。sqlite3 reddit.db "SELECT COUNT(*) FROM posts; SELECT COUNT(*) FROM comments;"检查记录数。shasum -a 256 reddit.db并与checksums.txt对比。
重要声明
- 非医疗建议: 该数据集基于患者自我报告的数据,非临床证据,仅用于发现模式和线索,不应作为诊断或治疗依据。
- 版权声明: Reddit内容归原作者和Reddit所有,数据来自公共存档
arctic-shift,用于研究和教育目的。GitHub仓库中的代码采用MIT许可。