Twitter-2015 and Twitter-2017
收藏资源简介:
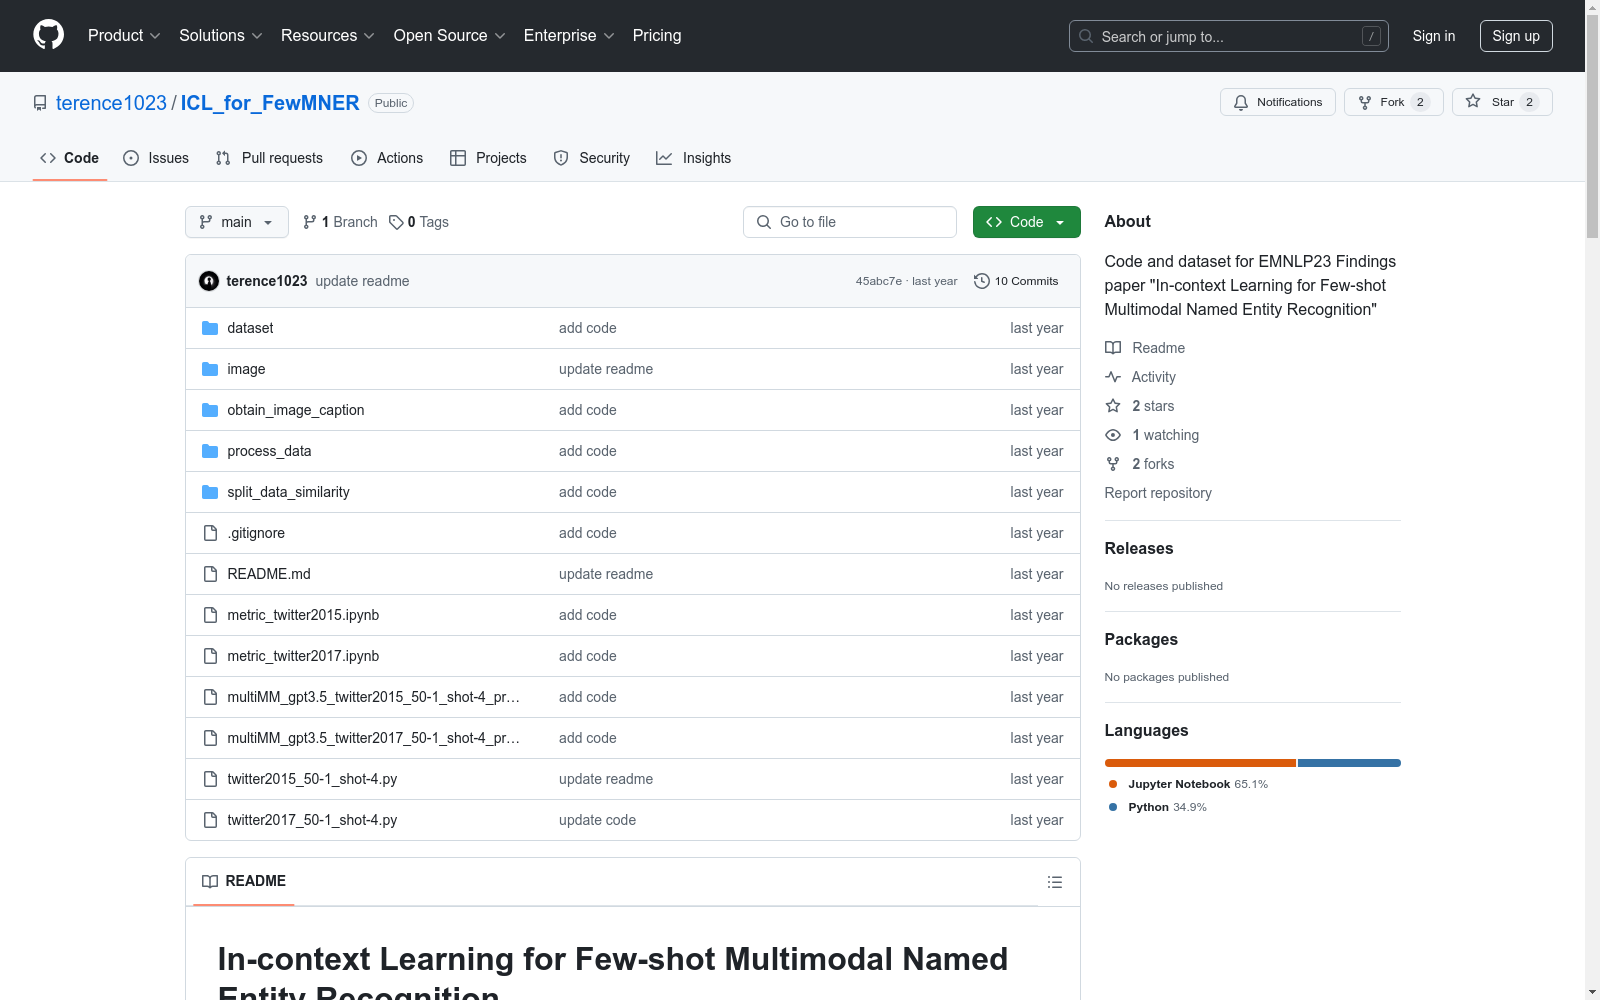
本数据集包含Twitter-2015和Twitter-2017的原始MNER数据,用于Few-shot Multimodal Named Entity Recognition任务。数据集需要从Google Drive下载并解压到指定文件夹。
本数据集汇聚了Twitter-2015及Twitter-2017的原始多模态命名实体识别(MNER)数据,旨在服务于少样本多模态命名实体识别任务。用户需从谷歌硬盘下载该数据集,并解压至指定目录。
数据集概述
数据集名称
- Twitter-2015
- Twitter-2017
数据集来源
- 原始数据集需从Google Drive下载,链接为Google Drive。
数据集处理
- 使用
./process_data/change_dataset_format_twitter2015/2017.ipynb转换原始MNER数据集格式。 - 使用
./obtain_image_caption/image_caption_OFA_twitter2015/2017.py获取图像标题。 - 使用
./split_data_similarity/split_dataset/split_twitter2015/2017.ipynb采样不同数据集($mathcal{D}_ {10}$, $mathcal{D}_ {50}$, 和 $mathcal{D}_ {100}$)。
数据集用途
- 用于Few-shot Multimodal Named Entity Recognition (FewMNER)任务,旨在通过少量标注示例有效定位和识别文本-图像对中的命名实体。
数据集操作示例
-
以$mathcal{D}_{50}$和4-shot为例,运行以下命令:
python twitter2015_50-1_shot-4.py python twitter2017_50-1_shot-4.py
数据集相关文献引用
-
若使用此项目进行研究,请引用以下论文:
@inproceedings{cai-etal-2023-context, title = "In-context Learning for Few-shot Multimodal Named Entity Recognition", author = "Cai, Chenran and Wang, Qianlong and Liang, Bin and Qin, Bing and Yang, Min and Wong, Kam-Fai and Xu, Ruifeng", booktitle = "Findings of the Association for Computational Linguistics: EMNLP 2023", publisher = "Association for Computational Linguistics", doi = "10.18653/v1/2023.findings-emnlp.196", pages = "2969--2979", }