tulu3-sft-personas-math-sandboxes-verified-v2
收藏资源简介:
Tulu-3 SFT Personas Math — Verifier-Fixed (v2) 是一个专注于数学推理的文本生成数据集,属于 Tulu-3 系列,并经过验证。该数据集是原始 `laion/tulu3-sft-personas-math-sandboxes-verified` 数据集的修复版本,主要修复涉及任务验证器,使其能输出可解析的、带有梯度信号的测试结果,并修复了一个导致部分任务无法通过的潜在错误,确保所有任务均可求解。数据集包含 9,998 个样本,每个样本对应一个任务,数据结构包含两列:`path`(字符串)和 `task_binary`(gzip 压缩的 tar 字节流)。每个任务包内包含定义任务所需的多个文件,如 `task.toml`、`instruction.md`、`metadata.json`、测试文件、解决方案以及环境定义。该数据集适用于涉及代码执行、测试验证的强化学习(特别是 RLOO 训练)或监督微调场景下的数学问题求解任务。
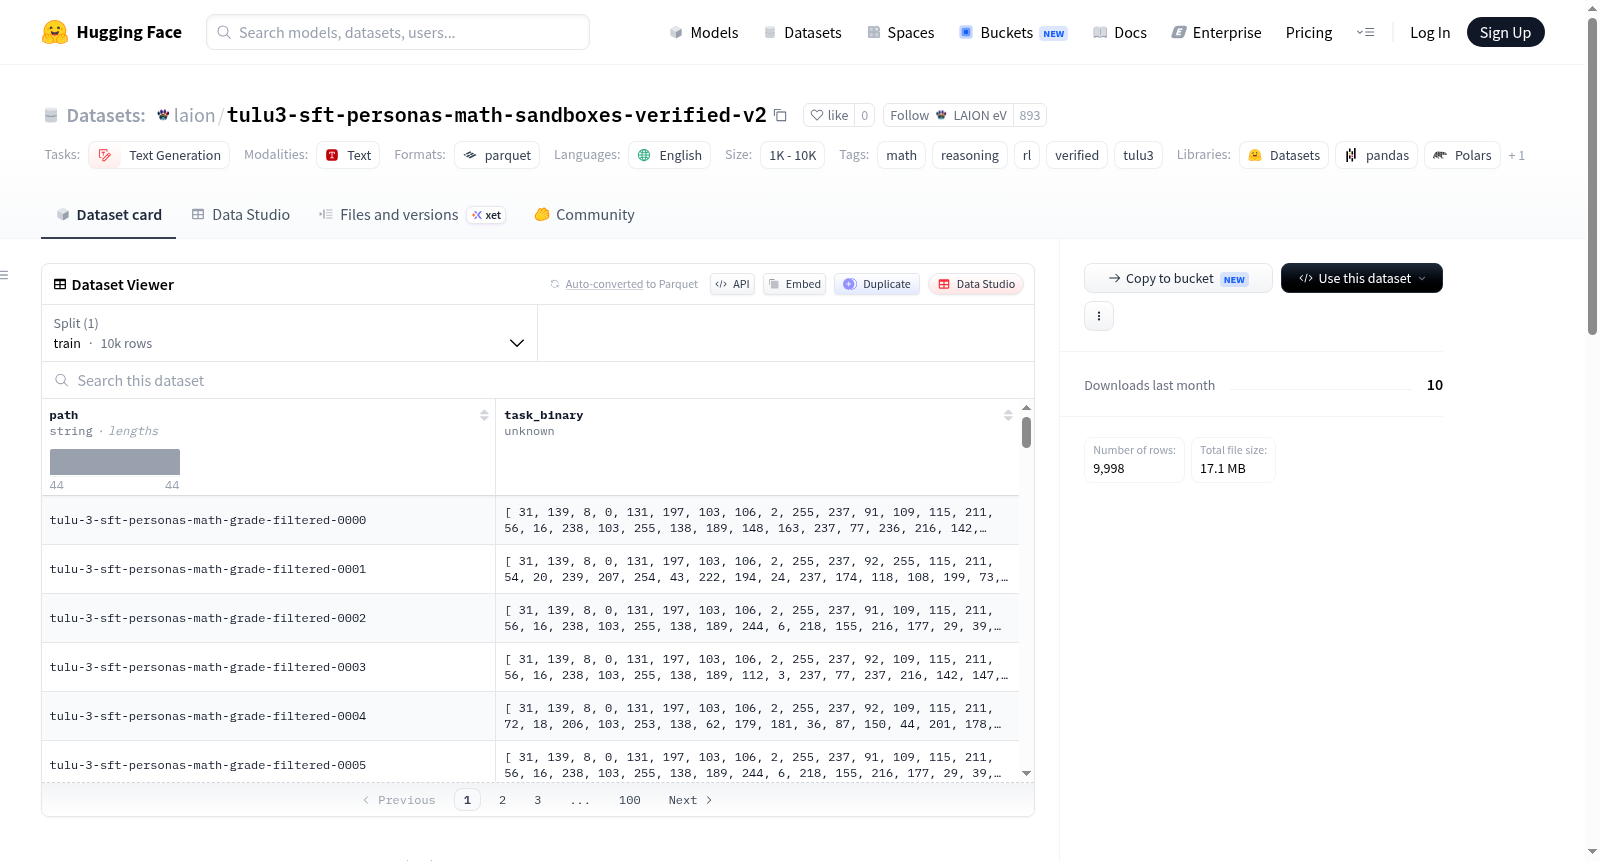
Tulu-3 SFT Personas Math — Verifier-Fixed (v2) is a text generation dataset focused on mathematical reasoning, part of the Tulu-3 series and verified. It is a fixed version of the original `laion/tulu3-sft-personas-math-sandboxes-verified` dataset. The main fixes involve the task verifier: the original verifiers output format could not be correctly parsed by the `pass_ratio` reward shaper, causing the reward signal to degrade to binary values during training. This version rewrites the verifier based on the pytest framework, enabling it to output parsable test results with gradient signals (e.g., scoring 1.0 for passing all 2 tests, 0.5 for passing one, and 0.0 for failing all). Additionally, a potential bug that caused approximately 9.6% of tasks (due to expected answers containing internal spaces) to fail has been fixed, ensuring all tasks are solvable. The dataset contains 9,998 samples, each corresponding to a task. The data structure includes two columns: `path` (string) and `task_binary` (gzip-compressed tar byte stream). Each task package contains multiple files required to define the task: `task.toml`, `instruction.md`, `metadata.json`, test files (`tests/test.sh` and `tests/test_state.py`), a solution (`solution/solve.sh`), and an environment definition (`environment/Dockerfile`). This dataset is suitable for mathematical problem-solving tasks in reinforcement learning (especially RLOO training) or supervised fine-tuning scenarios involving code execution and test verification.
数据集概述
- 数据集名称:Tulu-3 SFT Personas Math — Verifier-Fixed (v2)
- 来源:基于
laion/tulu3-sft-personas-math-sandboxes-verified的修复版本 - 语言:英语
- 任务类别:文本生成
- 标签:数学、推理、强化学习、已验证、Tulu3
- 规模:约 1,000 至 10,000 行(实际 9,998 行)
主要修复内容
-
验证器输出格式修复:
- 原数据集的
tests/test.sh输出格式为Correct answer: N或Incorrect answer: expected N, got M,无法被pass_ratio奖励塑造器解析,导致奖励回退为二进制值(0.0 或 1.0),缺乏梯度信号。 - 修复后,
tests/test.sh调用python3 -m pytest /tests/test_state.py,输出可解析的 pytest 结果,提供分级信号:- 正确答案:
2 passed→pass_ratio= 1.0 - 错误答案(文件存在):
1 failed, 1 passed→pass_ratio= 0.5 - 无答案文件:
2 failed→pass_ratio= 0.0
- 正确答案:
- 原数据集的
-
隐含错误修复:
- 原
test.sh对智能体答案使用tr -d去除空格,但未对预期值做同样处理,导致 961/9998 个任务(9.6%) 因预期答案包含内部空格而无法通过。 - 修复后,基于 pytest 的验证器仅使用
.strip()去除首尾空格,使得所有 9,998 个任务均可解答。
- 原
验证结果
- 黄金/预期一致性:9,998 个任务全部匹配
- Docker 冒烟测试:正确→2 passed,错误→1 passed 1 failed,无文件→2 failed
- 共享快照:
ubuntu:24.04+python3+pytest
数据结构
- 行数:9,998
- 列:
path(字符串类型)task_binary(gzip-tar 字节类型)
- 每个任务包含的文件:
task.tomlinstruction.mdmetadata.jsontests/test.shtests/test_state.pysolution/solve.shenvironment/Dockerfile