JPxxx/url-pretraining-dataset
收藏资源简介:
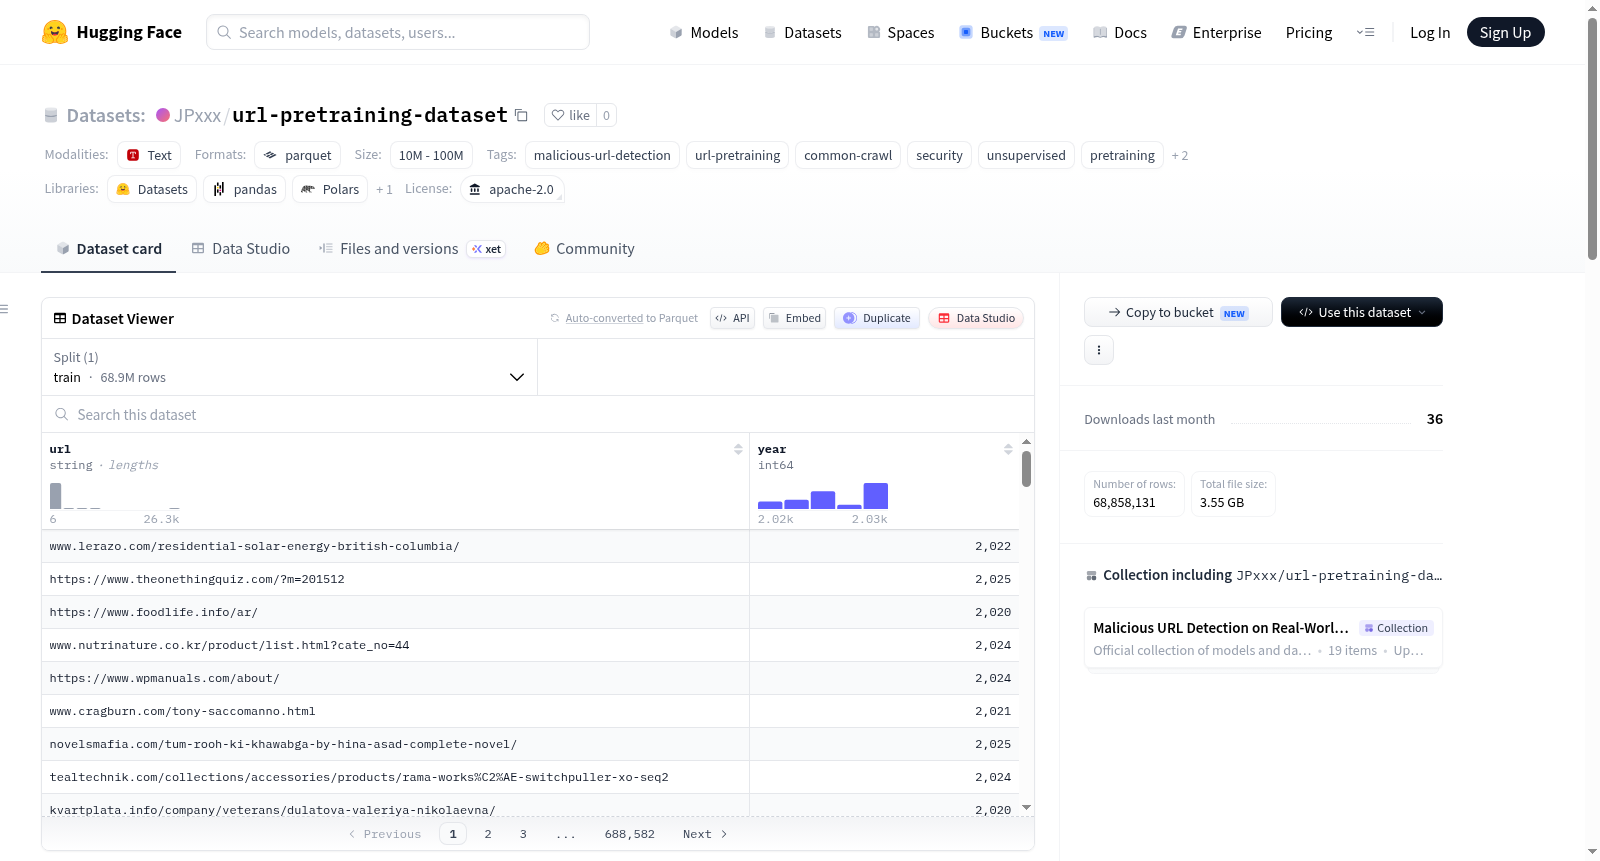
这是一个大规模无标签的URL预训练语料库,包含约6800万个从Common Crawl月度快照(2020-2025年)中采样的公共URL。数据集主要用于URL聚焦模型的掩码语言建模(MLM)或其他自监督预训练目标,适合初始化模型以进行下游URL分类任务(如恶意URL检测)。数据集包含URL字符串和采样年份两列,经过过滤仅包含HTTP 200响应的URL,去重并限制每个站点标识符的URL数量以减少流行站点的偏差。数据集来源于Common Crawl月度抓取的随机采样分片,具有时间和结构多样性。
This is a large-scale unlabeled corpus of ~68 million public URLs sampled from Common Crawl monthly snapshots (2020–2025). It was created for, and used in, the paper "From Lab to Production: Malicious URL Detection on Real-World Data" to pre-train transformer-based models on URL-specific structural and language patterns. The corpus provides temporal and structural diversity, covering a wide range of domains, path/query structures, and IP-based URLs. It is ideal for initializing models that will be fine-tuned on downstream URL classification tasks (e.g., malicious URL detection).