SaProtHub/Dataset-Thermostability-FLIP
收藏资源简介:
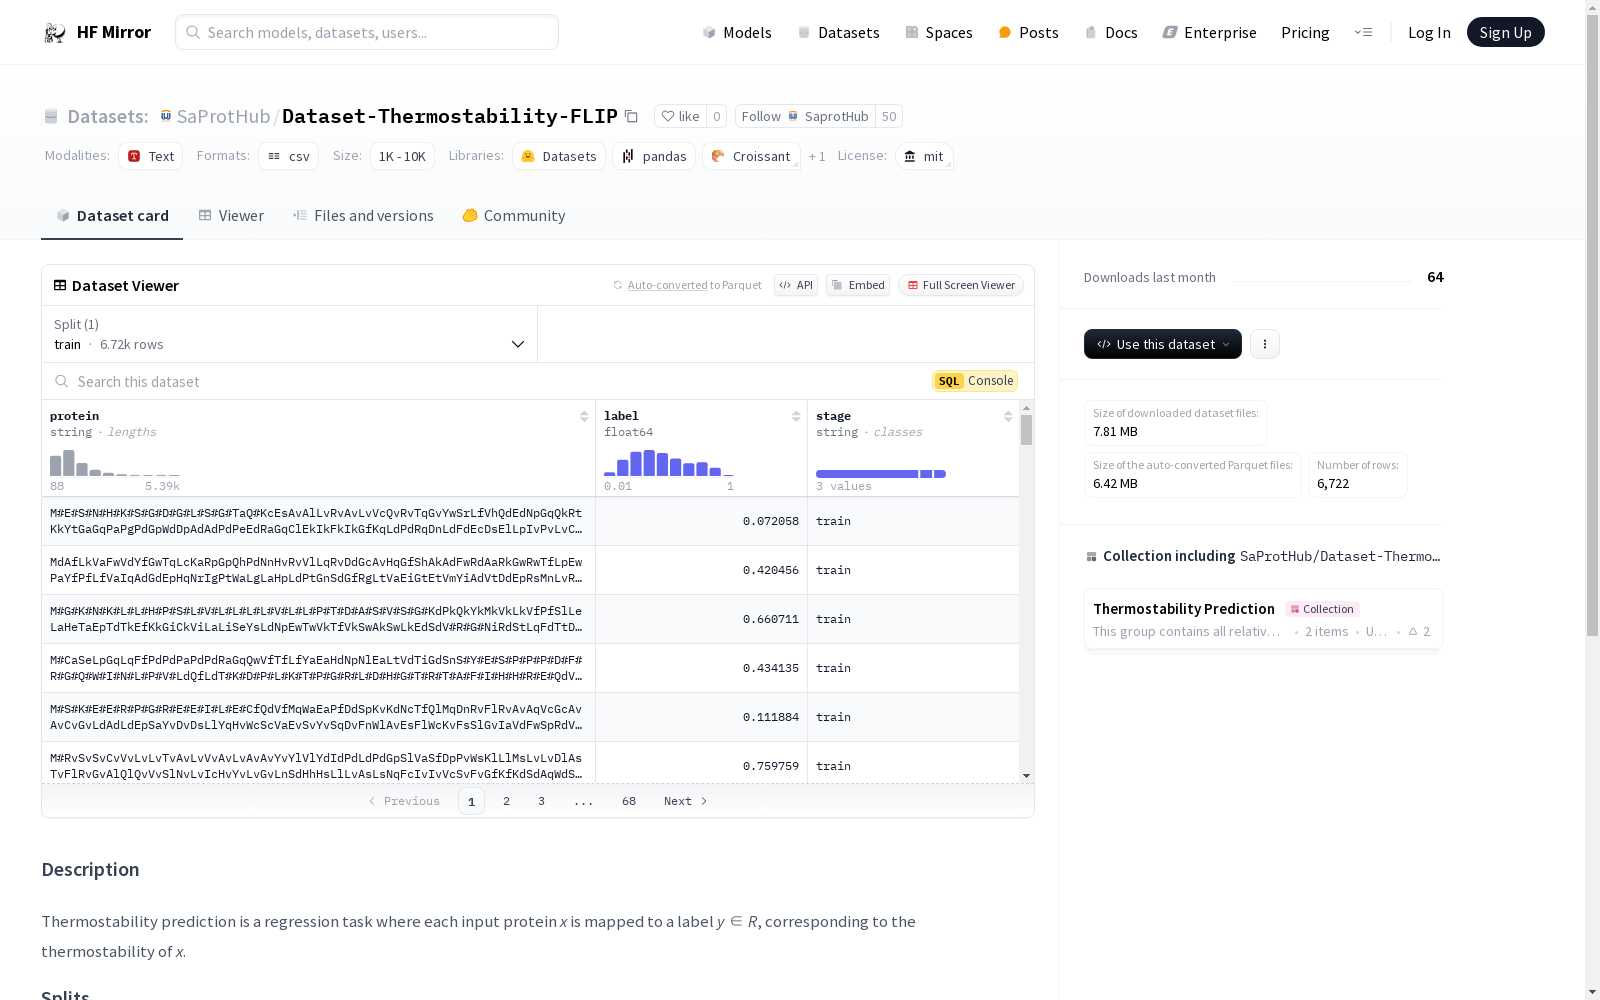
热稳定性预测是一个回归任务,每个输入蛋白质x被映射到一个标签y,y代表x的热稳定性。数据集来源于FLIP项目,具体使用了Human-cell分割的蛋白质数据,并且去除了没有AF2结构的蛋白质。数据集按照70%的结构相似性进行分割,分为训练集、验证集和测试集,数量分别为5310、706和706。数据格式为LMDB格式,包含样本数量、蛋白质的UniProt ID、结构感知序列和序列的适应性标签等信息。
Thermostability prediction is a regression task where each input protein x is mapped to a label y ∈ R, corresponding to the thermostability of x. The dataset is from FLIP: Benchmark tasks in fitness landscape inference for proteins, specifically using the Human-cell splits of protein data, with proteins lacking AF2 structures removed. The dataset is split based on 70% structure similarity into training, validation, and test sets with sizes of 5310, 706, and 706, respectively. The data is organized in LMDB format, including the number of samples, the UniProt ID of the protein, the structure-aware sequence, and the fitness label of the sequence.
数据集概述
数据集描述
- 任务类型: 回归任务
- 目标: 预测蛋白质的热稳定性,将每个输入蛋白质映射到一个实数标签,表示其热稳定性。
数据集分割
- 来源: 来自FLIP: Benchmark tasks in fitness landscape inference for proteins
- 结构类型: AF2
- 分割依据: 基于70%结构相似性
- 分割详情:
- 训练集: 5310个样本
- 验证集: 706个样本
- 测试集: 706个样本
数据格式
- 存储格式: LMDB
- 数据库结构:
- 长度: 样本总数
- 数据字段:
- name: 蛋白质的UniProt ID
- seq: 结构感知序列
- plddt: 所有位置的pLDDT值
- fitness: 序列的适应度标签