SABmark-dataset
收藏资源简介:
SABmark是一个蛋白质序列对齐的基准数据集,用于远程同源检测。它包括几个子集:twi(<25%相似度),sup(低到中等相似度),twi_fp和sup_fp(分别添加了虚假阳性的twi和sup子集)。数据集的特征包括序列对ID、组ID、序列名称、参考对齐列表、序列身份百分比、SCOP标签和元数据。
SABmark is a benchmark dataset for protein sequence alignment, designed for remote homology detection. It includes several subsets: twi (<25% sequence identity), sup (low to moderate sequence identity), twi_fp and sup_fp (the twi and sup subsets with false positives added, respectively). The features of this dataset consist of sequence pair ID, group ID, sequence name, reference alignment list, percentage sequence identity, SCOP label, and metadata.
SABmark数据集概述
数据集简介
SABmark是一个用于远程同源性蛋白质序列比对的基准数据集,涵盖整个已知折叠空间。
子集配置
数据集包含5个子集配置:
- twi:Twilight子集(<25%序列一致性)
- sup:超家族子集(低到中等一致性)
- twi_fp:Twilight子集(添加假阳性样本)
- sup_fp:超家族子集(添加假阳性样本)
- all:所有子集的并集
数据特征
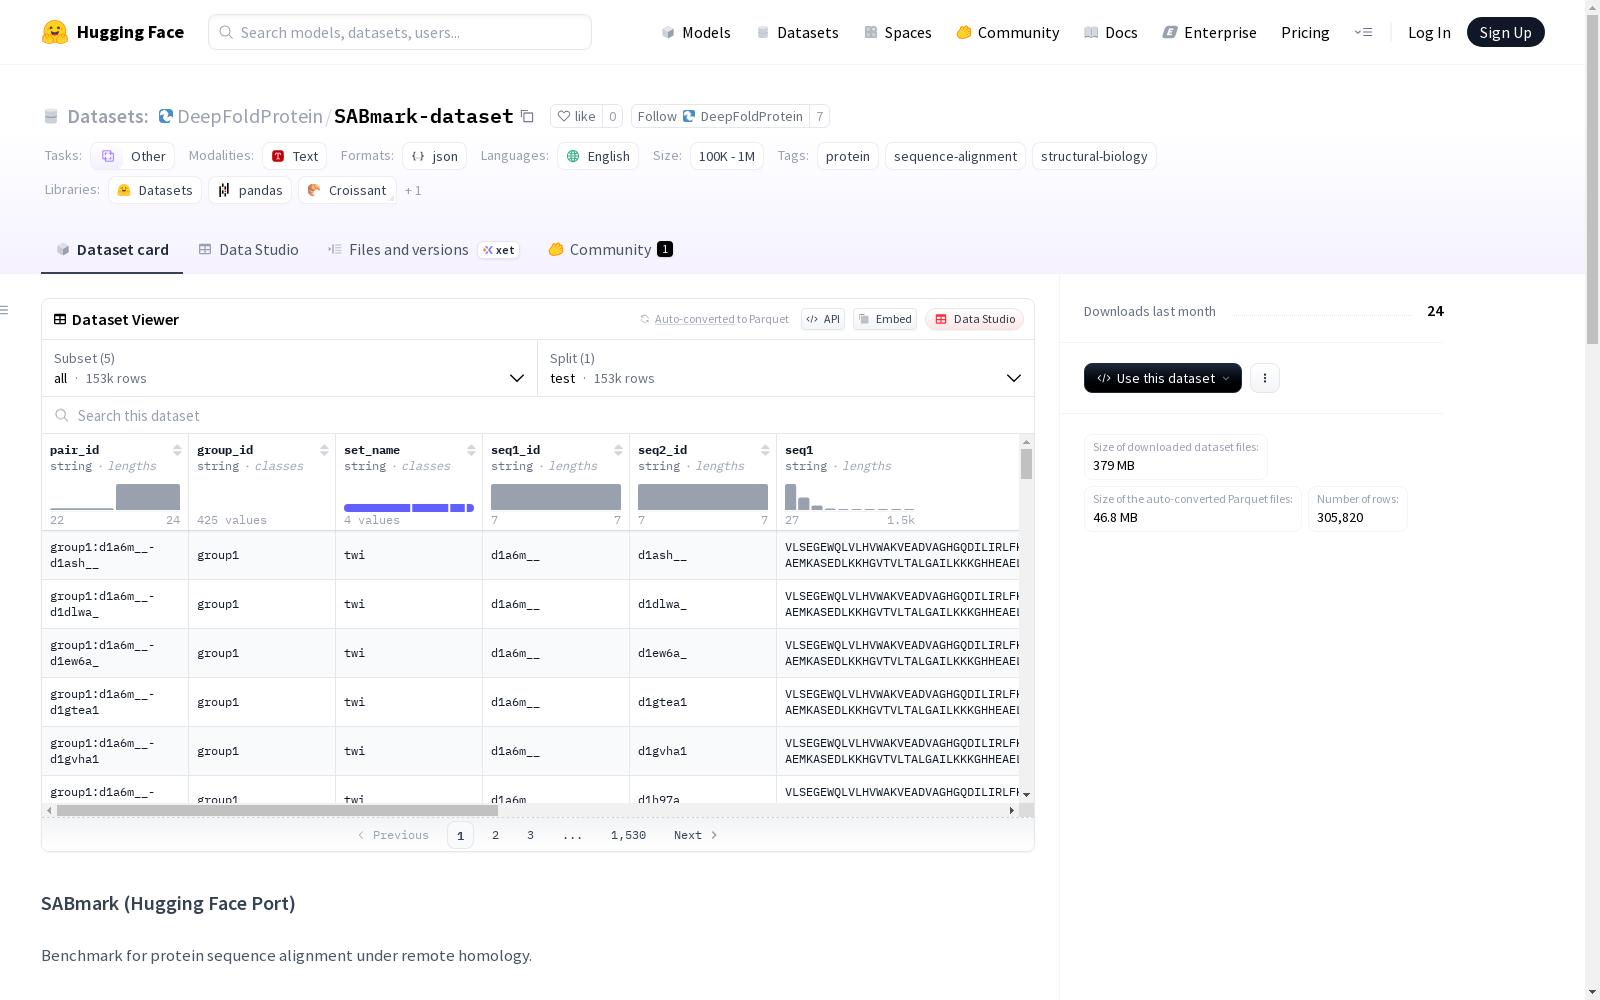
每个样本包含以下特征字段:
- 标识信息:
pair_id、group_id、set_name - 序列信息:
seq1_id、seq2_id、seq1、seq2 - 比对信息:
ref_alignment(基于0的索引对列表) - 统计信息:
percent_identity、scop_labels、meta
数据格式
- 数据文件格式:JSON Lines (.jsonl)
- 所有子集仅包含测试集分割
使用方式
python from datasets import load_dataset ds = load_dataset("DeepFoldProtein/SABmark", name="twi", split="test") ex = ds[0] print(ex["seq1"], ex["seq2"], ex["ref_alignment"][:5])
引用信息
bibtex @article{VanWalle2004SABmark, title={SABmark---a benchmark for sequence alignment that covers the entire known fold space}, author={Van Walle, Ivan and Lasters, Ignace and Wyns, Lode}, journal={Bioinformatics}, volume={21}, number={7}, pages={1267--1268}, year={2004}, publisher={Oxford University Press}, DOI = {10.1093/bioinformatics/bth493} }