common-pile/cccc
收藏资源简介:
--- task_categories: - text-generation language: - en pretty_name: Creative Commons Common Crawl --- # Creative Commons Common Crawl ## Description This dataset contains text from 52 Common Crawl snapshots, covering about half of Common Crawl snapshots available to date and covering all years of operations of Common Crawl up to 2024. We found a higher level of duplication across this collection, suggesting that including more snapshots would lead to a modest increase in total token yield. From these snapshots, we extract HTML content using [FastWarc](https://arxiv.org/abs/2112.03103). Then, using a regular expression adapted from [the C4Corpus project](https://aclanthology.org/L16-1146/). To ensure license accuracy, we manually verified the top 1000 domains by content volume, retaining only the 537 domains with confirmed licenses where the Creative Commons designation applied to the all text content rather than embedded media or a subset of the text on the domain. As an additional check, we did a second round of annotations with the assistance of OpenAI's o3 model. Specifically, we instructed the model to examine each web domain and identify the ones that were openly licensed. We then had a second team manually annotate the cases where the AI does not approve of the domain but the original human auditor did. This resulted in **todo** domains being removed. We extract the main content of these documents and remove boilerplate using [Resiliparse](https://github.com/chatnoir-eu/chatnoir-resiliparse). We perform URL-level exact deduplication and use Bloom filters to remove near-duplicates with 80% ngram overlap. We also employ rule-based filters matching [Dolma](https://arxiv.org/abs/2402.00159); namely, we use [C4-derived heuristics](https://arxiv.org/abs/1910.10683) to filter pages containing Javascript, Lorem Ipsum, and curly braces {}. We also apply all [Gopher rules](https://arxiv.org/abs/2112.11446) to remove low-quality pages. Per-document license information is available in the `license` entry of the `metadata` field of each example. Code for collecting, processing, and preparing this dataset is available in the [common-pile GitHub repo](https://github.com/r-three/common-pile). ## Dataset Statistics | Documents | UTF-8 GB | |-----------|----------| | 51,054,412 | 260 | ## License Issues While we aim to produce datasets with completely accurate licensing information, license laundering and inaccurate metadata can cause us to erroneously assign the incorrect license to some documents (for further discussion of this limitation, please see [our paper](https://huggingface.co/papers/2506.05209)). If you believe you have found an instance of incorrect licensing in this dataset, please [start a discussion](https://github.com/r-three/common-pile/discussions/new) on this repository. This dataset has been updated to remove instances of incorrect licensing. If you require the exact version that Comma v0.1 was trained on for non-commercial research purposes, please [start a discussion](https://github.com/r-three/common-pile/discussions/new) on this repository. ## Other Versions This is the "raw" version of Creative Commons Common Crawl. If you are looking for the filtered version used to train [Comma v0.1](https://huggingface.co/common-pile/comma-v0.1), you can find it [here](https://huggingface.co/datasets/common-pile/cccc_filtered). ## Citation If you use this dataset, please cite: ```bibtex @article{kandpal2025common, title={{The Common Pile v0.1: An 8TB Dataset of Public Domain and Openly Licensed Text}}, author={Nikhil Kandpal and Brian Lester and Colin Raffel and Sebastian Majstorovic and Stella Biderman and Baber Abbasi and Luca Soldaini and Enrico Shippole and A. Feder Cooper and Aviya Skowron and Shayne Longpre and Lintang Sutawika and Alon Albalak and Zhenlin Xu and Guilherme Penedo and Loubna Ben and Elie Bakouch and John David and Honglu Fan and Dashiell Stander and Guangyu Song and Aaron Gokaslan and John Kirchenbauer and Tom Goldstein and Brian R and Bhavya Kailkhura and Tyler Murray}, journal={arXiv preprint}, year={2025} } ```
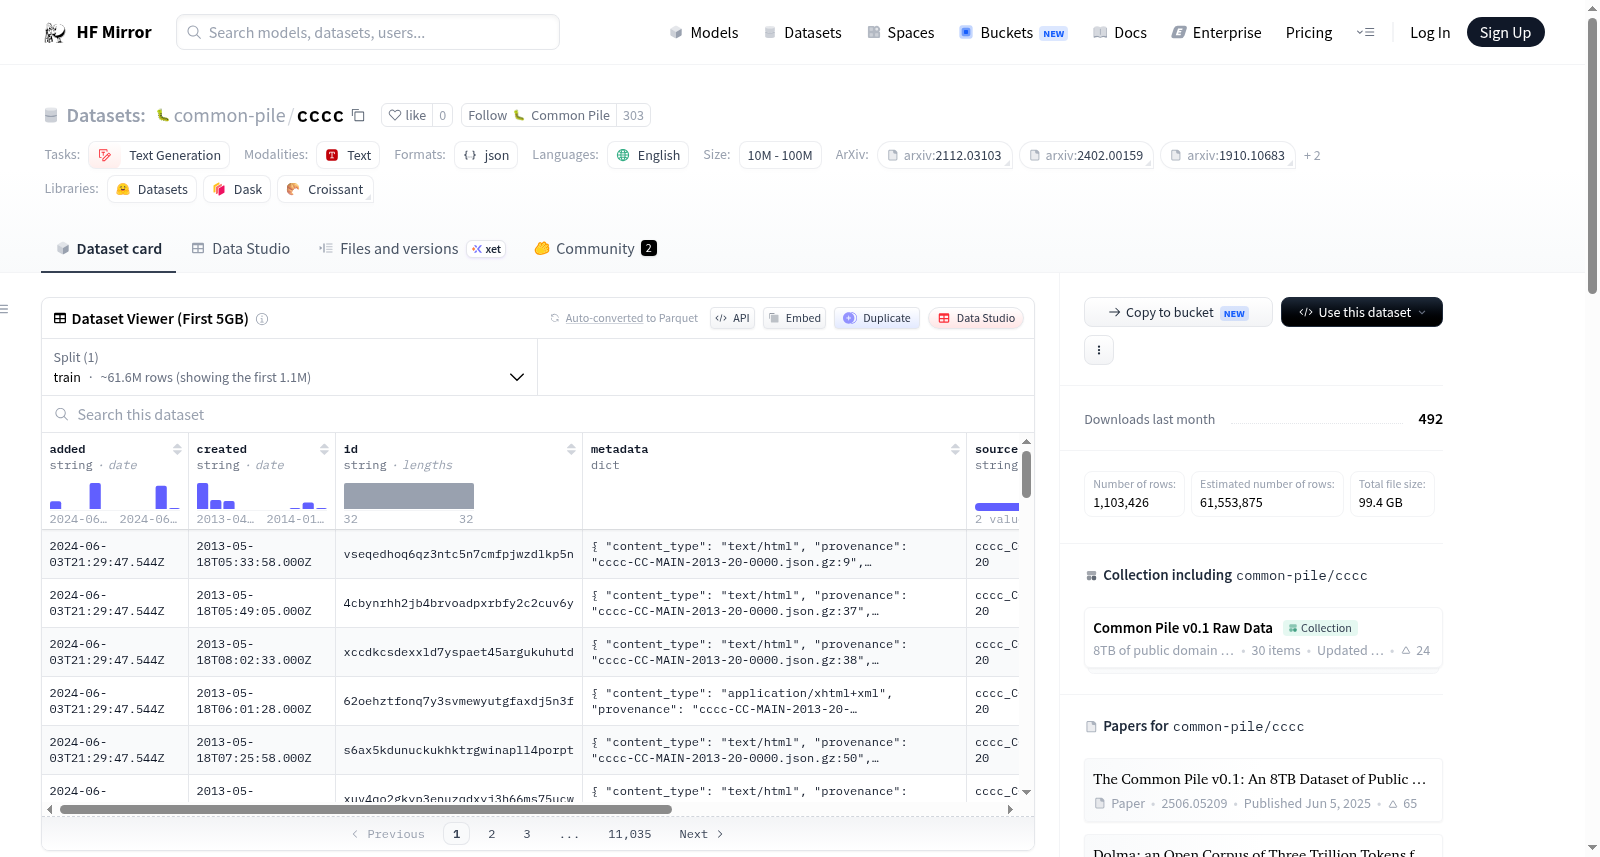
The Creative Commons Common Crawl dataset contains text from 52 Common Crawl snapshots, covering more than half of the available Common Crawl snapshots to date and includes all years of Common Crawl operations. The dataset has undergone a series of processing steps including license verification, duplicate and low-quality content removal, and more. It consists of over 51 million documents with a total size of 260GB.