food-VQA-benchmark
收藏资源简介:
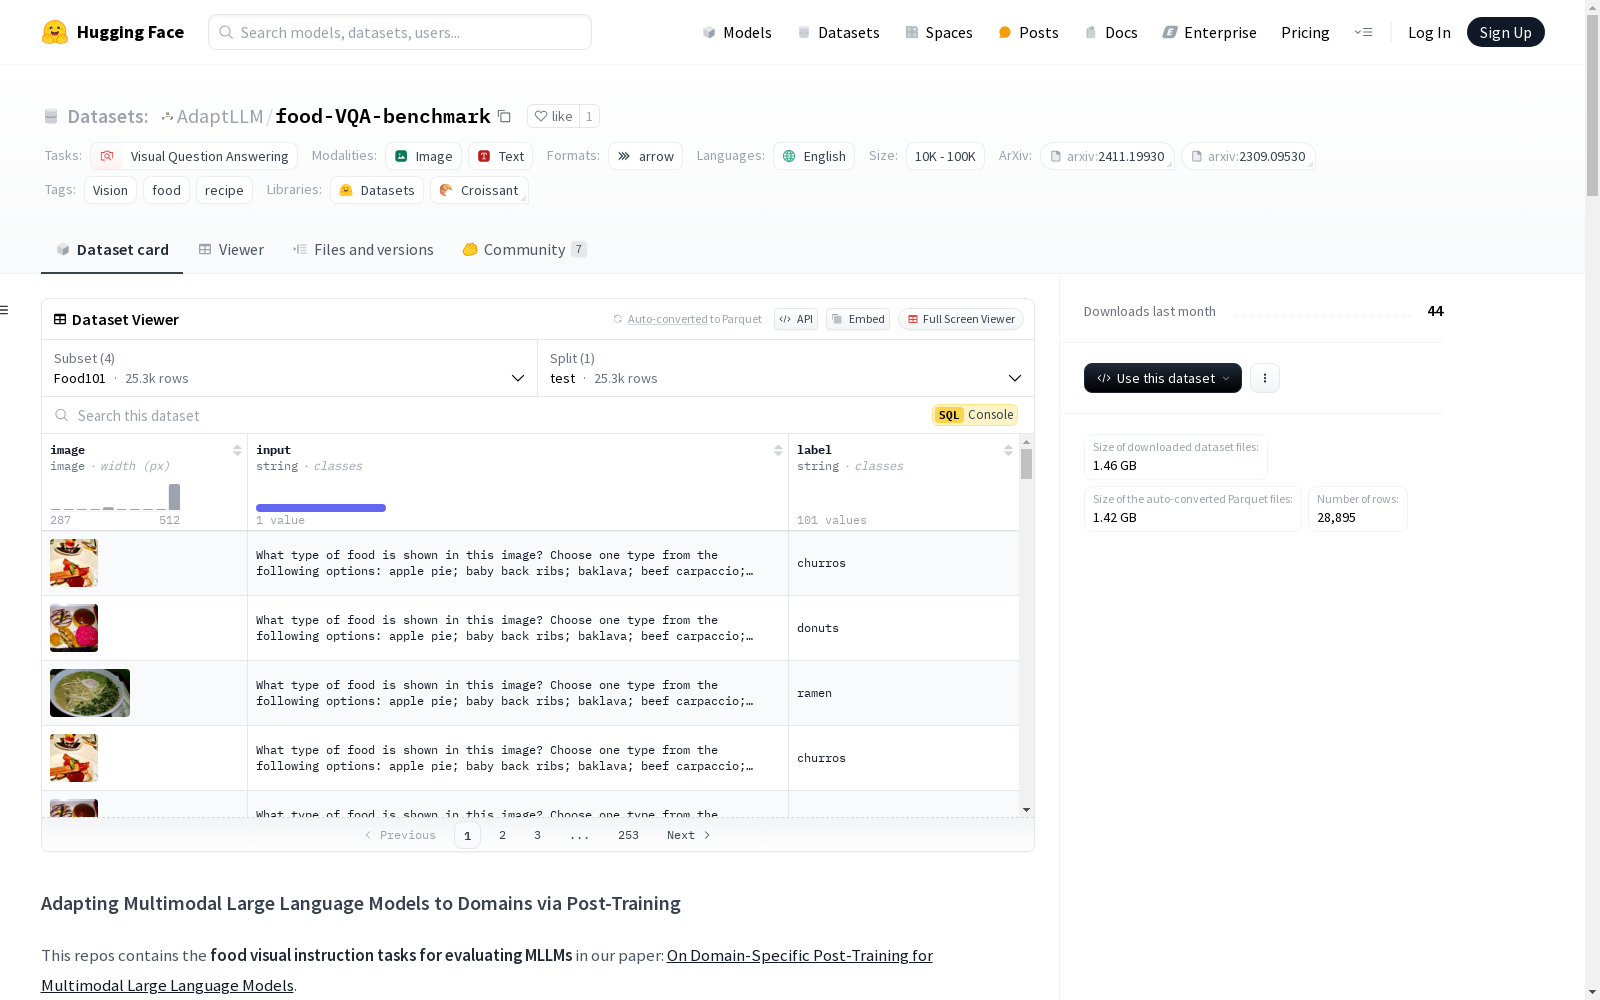
该项目包含多个与食品相关的数据集配置,用于测试和评估多模态大语言模型在食品领域的性能。主要数据集包括Recipe1M、Nutrition5K、Food101和FoodSeg103。这些数据集用于视觉问答任务,并提供了加载和使用这些数据集的示例代码。
This project includes multiple food-related dataset configurations for testing and evaluating the performance of multimodal large language models in the food domain. The primary datasets involved are Recipe1M, Nutrition5K, Food101, and FoodSeg103. These datasets are designed for visual question answering tasks, and sample code for loading and using these datasets is also provided.
数据集概述
基本信息
- 任务类别: 视觉问答 (Visual Question Answering)
- 语言: 英语 (en)
- 标签: 视觉 (Vision), 食物 (food), 食谱 (recipe)
配置详情
-
Recipe1M:
- 数据文件:
- 分割: 测试 (test)
- 路径:
food_eval_multitask_v2/data-*.arrow
- 数据文件:
-
Nutrition5K:
- 数据文件:
- 分割: 测试 (test)
- 路径:
nutrition50k/data-*.arrow
- 数据文件:
-
Food101:
- 数据文件:
- 分割: 测试 (test)
- 路径:
food101/data-*.arrow
- 数据文件:
-
FoodSeg103:
- 数据文件:
- 分割: 测试 (test)
- 路径:
foodseg103/data-*.arrow
- 数据文件:
数据集加载
-
使用
datasets库加载数据集的示例代码: python from datasets import load_datasettask_name = FoodSeg103 # 可选: Food101, FoodSeg103, Nutrition5K, Recipe1M data = load_dataset(AdaptLLM/food-VQA-benchmark, task_name, split=test) print(list(data)[0])
类别映射
- Food101:
food101_name_to_label_map.json - FoodSeg103:
foodSeg103_id2label.json - Nutrition5K:
nutrition5k_ingredients.py
引用
- 如果使用该数据集,请引用以下文献: bibtex @article{adamllm, title={On Domain-Specific Post-Training for Multimodal Large Language Models}, author={Cheng, Daixuan and Huang, Shaohan and Zhu, Ziyu and Zhang, Xintong and Zhao, Wayne Xin and Luan, Zhongzhi and Dai, Bo and Zhang, Zhenliang}, journal={arXiv preprint arXiv:2411.19930}, year={2024} }