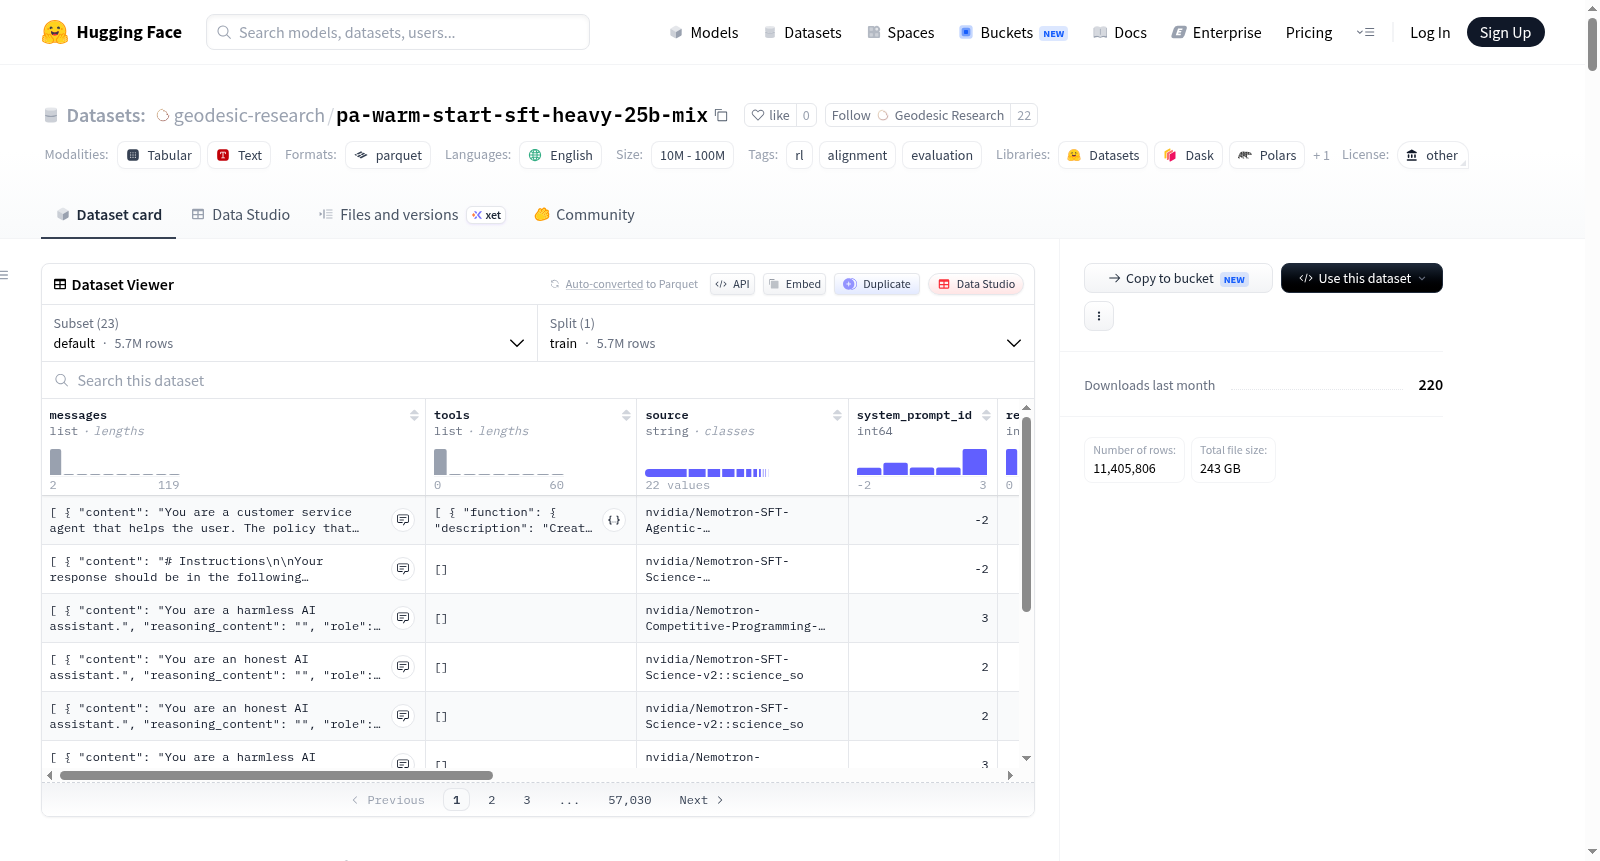
pa-warm-start-sft-heavy-25b-mix
收藏资源简介:
该数据集是一个大型多任务对话数据集,包含多个子集(config_name),每个子集具有相同的特征结构。特征包括:消息序列(messages),内含内容(content)、推理内容(reasoning_content)、角色(role)以及工具调用(tool_calls,包含函数名、参数、ID和类型);工具定义(tools)列表,包含函数描述、名称、参数、严格模式等;来源(source)、系统提示ID(system_prompt_id)、推理长度(reasoning_len)、思维链长度统计(cot_lengths_chars及均值、最小值、最大值)、原始文本(raw_text)和令牌数(n_tokens)。每个子集仅包含训练集(train)。子集名称覆盖多种领域:agentic_interactive(代理交互)、agentic_search_v2(搜索)、agentic_tool_calling_v2(工具调用)、arc_agi_reasoning(ARC-AGI推理)、arc_agi_tools(ARC-AGI工具)、chat_multiturn(多轮聊天)、chat_v2_if(指令跟随)、comp_prog_python_00/01(Python编程)、comp_prog_v1_00/01(通用编程)、default(默认,包含570万样本)、finance(金融)、math_proofs(数学证明)、math_v4(数学)、opencode(开放代码)、science_rqa_plain(科学问答)。总样本数约570万(default子集),其余子集样本数从数千到数十万不等。该数据集适用于训练和评估具备推理、工具使用和多轮对话能力的语言模型。
This dataset is a large-scale multi-task dialogue dataset containing multiple subsets (config_name), each with the same feature structure. Features include: message sequences (messages) with content, reasoning_content, role, and tool_calls (including function name, arguments, ID, and type); a list of tool definitions (tools) including function description, name, arguments, strict mode, etc.; source, system_prompt_id, reasoning_len, chain-of-thought length statistics (cot_lengths_chars with mean, min, max), raw_text, and n_tokens. Each subset only contains a training set (train). Subset names cover various domains: agentic_interactive, agentic_search_v2, agentic_tool_calling_v2, arc_agi_reasoning, arc_agi_tools, chat_multiturn, chat_v2_if, comp_prog_python_00/01, comp_prog_v1_00/01, default (with 5.7 million samples), finance, math_proofs, math_v4, opencode, science_rqa_plain. The total sample count is about 5.7 million (default subset), while other subsets range from thousands to hundreds of thousands. This dataset is suitable for training and evaluating language models with reasoning, tool use, and multi-turn dialogue capabilities.
数据集概览:pa-warm-start-sft-heavy-25b-mix
基本信息
- 数据集地址:https://huggingface.co/datasets/geodesic-research/pa-warm-start-sft-heavy-25b-mix
- 数据集用途:用于25B参数模型的预热启动监督微调(SFT),包含多种任务类型的混合数据
数据集配置与规模
该数据集包含17个配置(config),各配置的规模如下:
| 配置名称 | 训练样本数 | 数据集大小(字节) | 下载大小(字节) |
|---|---|---|---|
| agentic_interactive | 113,486 | 4,957,291,098 | 2,696,305,490 |
| agentic_search_v2 | 3,365 | 630,306,219 | 368,388,247 |
| agentic_tool_calling_v2 | 417,960 | 16,742,441,902 | 7,466,947,433 |
| arc_agi_reasoning | 49,917 | 6,785,437,092 | 2,102,018,861 |
| arc_agi_tools | 28,001 | 4,299,313,461 | 1,135,112,239 |
| chat_multiturn | 161,376 | 3,966,465,348 | 2,194,450,980 |
| chat_v2_if | 829,290 | 17,474,115,116 | 11,969,241,270 |
| comp_prog_python_00 | 63,048 | 11,229,300,441 | 1,649,706,231 |
| comp_prog_python_01 | 49,598 | 10,940,752,598 | 2,619,657,950 |
| comp_prog_v1_00 | 620,987 | 59,122,901,496 | 25,026,537,086 |
| comp_prog_v1_01 | 622,932 | 58,947,433,222 | 25,011,683,544 |
| default | 5,702,903 | 172,402,992,431 | 122,065,778,334 |
| finance | 36,498 | 7,059,493,033 | 3,889,158,890 |
| math_proofs | 9,497 | 2,847,721,278 | 1,121,735,853 |
| math_v4 | 243,184 | 18,758,134,787 | 7,540,174,095 |
| opencode | 36,779 | 4,763,239,317 | 3,202,822,445 |
| science_rqa_plain | - | - | - |
数据结构与特征
所有配置共享统一的数据特征结构,包含以下字段:
核心字段
- messages:对话消息列表,每条包含:
content(字符串):消息内容reasoning_content(字符串):推理内容role(字符串):角色标识tool_calls(列表):工具调用信息,包含函数名称、参数、ID和类型
- tools:工具定义列表,包含函数描述、名称、参数及严格模式标志
- source(字符串):数据来源
- system_prompt_id(int64):系统提示词标识符
- reasoning_len(int64):推理长度
思维链统计字段
- cot_lengths_chars(int64列表):思维链字符长度列表
- cot_chars_mean(float64):思维链字符均值
- cot_chars_min(int64):思维链字符最小值
- cot_chars_max(int64):思维链字符最大值
- raw_text(字符串):原始文本
- n_tokens(int64):Token数量
数据覆盖领域
数据集涵盖以下任务类型:
- 智能体交互:包括交互式智能体、智能体搜索、工具调用场景
- 编程竞赛:Python编程竞赛、通用编程竞赛
- 数学推理:数学证明、数学问题求解
- 通用对话:多轮对话、指令跟随
- 金融:金融领域数据
- 科学问答:科学研究问答
- ARC-AGI:抽象推理挑战任务
- 开放编码:开源编码相关数据