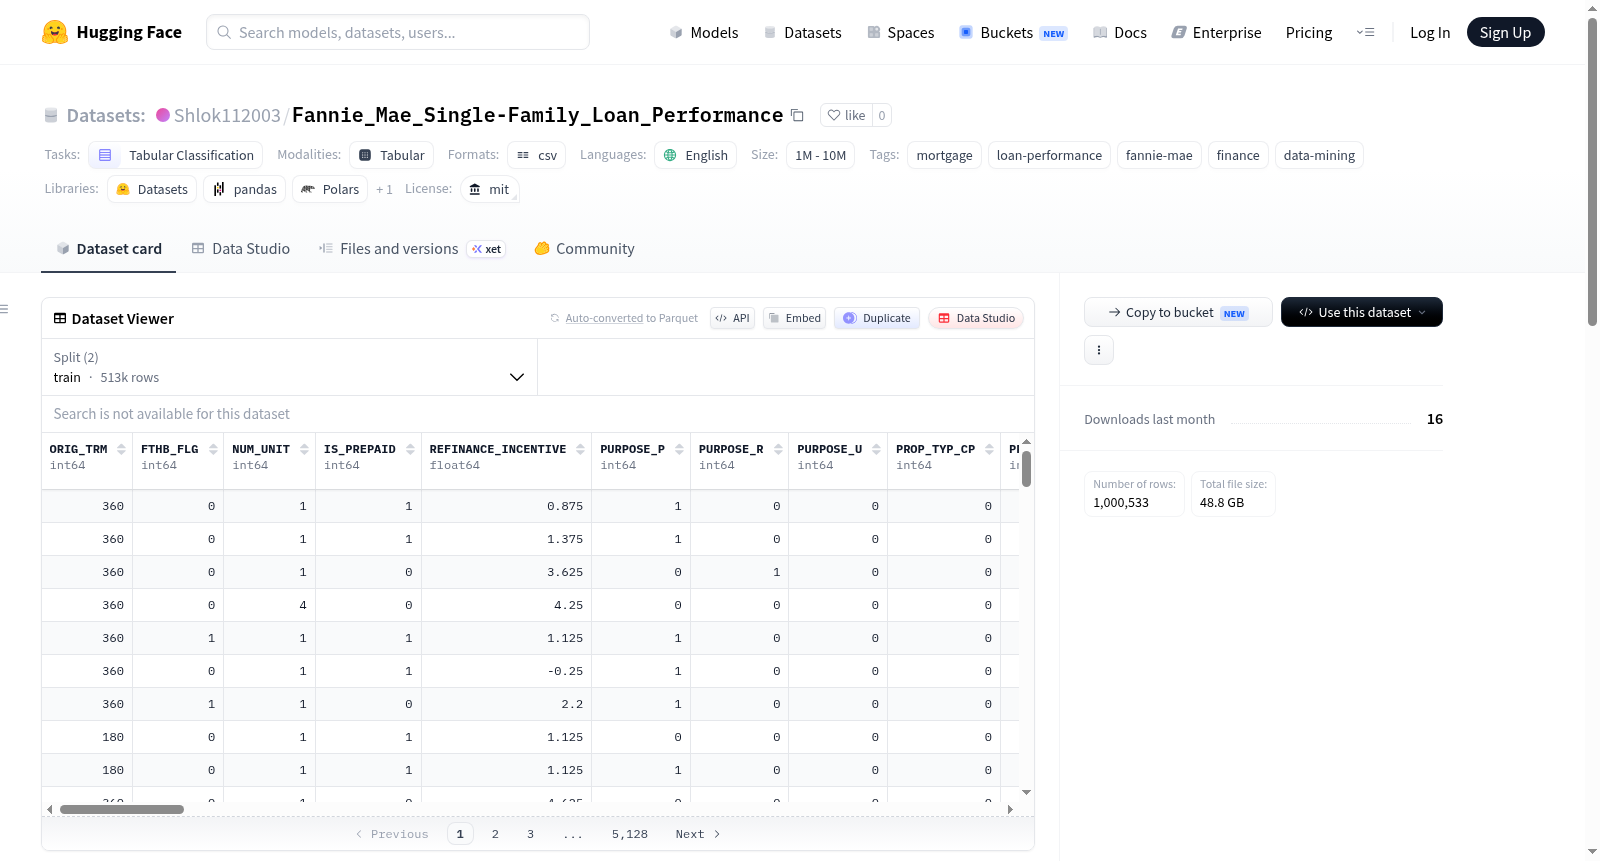
Fannie_Mae_Single-Family_Loan_Performance
收藏资源简介:
Fannie Mae Single-Family Loan Performance数据集是一个用于抵押贷款违约预测和贷款表现分析的开源表格分类数据集。该数据集包含美国房利美(Fannie Mae)公司提供的单户住宅贷款在多个历史季度的表现数据,覆盖了从2000年第一季度到2020年第一季度的关键时间点。数据集提供了两种形式:原始数据和已处理数据。原始数据以CSV格式存储,包含六个不同季度的文件(2000Q1、2005Q1、2008Q1、2013Q1、2017Q1、2020Q1),文件大小从约2.3GB到17.2GB不等,总计规模在1000万到1亿条记录之间。这些文件记录了贷款的基本信息、借款人特征、房产属性以及随时间变化的还款表现。已处理数据则经过了清洗、预处理和特征工程,分为训练集(train_ready.csv,约80MB)和测试集(test_ready.csv,约75MB),便于直接用于机器学习模型的开发与评估。该数据集主要适用于金融风控、信用评分、贷款违约预测等表格分类任务,是研究住房抵押贷款市场和信用风险建模的重要资源。
The Fannie Mae Single-Family Loan Performance dataset is an open-source tabular classification dataset designed for mortgage default prediction and loan performance analysis. It includes performance data for single-family residential loans provided by Fannie Mae across multiple historical quarters, covering key time points from the first quarter of 2000 to the first quarter of 2020. The dataset is available in two forms: raw data and processed data. The raw data is stored in CSV format, comprising six quarterly files (2000Q1, 2005Q1, 2008Q1, 2013Q1, 2017Q1, 2020Q1) with file sizes ranging from approximately 2.3GB to 17.2GB, totaling between 10 million and 100 million records. These files document loan basic information, borrower characteristics, property attributes, and repayment performance over time. The processed data has been cleaned, preprocessed, and feature-engineered, divided into a training set (train_ready.csv, about 80MB) and a test set (test_ready.csv, about 75MB), facilitating direct use in machine learning model development and evaluation. This dataset is primarily suitable for tabular classification tasks such as financial risk control, credit scoring, and loan default prediction, serving as a valuable resource for researching the housing mortgage market and credit risk modeling.
数据集概述
- 名称: Fannie Mae Single-Family Loan Performance Dataset
- 许可协议: MIT
- 任务类别: 表格分类
- 语言: 英语
- 标签: 抵押贷款、贷款表现、房利美、金融、数据挖掘
- 数据规模: 1000万至1亿条记录
数据结构
数据集包含原始数据和已处理数据两部分:
原始数据 (raw/)
| 文件 | 时间周期 | 大小 |
|---|---|---|
2000Q1.csv |
2000年第1季度 | 约2.3 GB |
2005Q1.csv |
2005年第1季度 | 约6.5 GB |
2013Q1.csv |
2013年第1季度 | 约17.2 GB |
2017Q1.csv |
2017年第1季度 | 约8.4 GB |
2020Q1.csv |
2020年第1季度 | 约8.2 GB |
已处理数据 (processed/)
| 文件 | 描述 | 大小 |
|---|---|---|
train_ready.csv |
训练集(已预处理和特征工程) | 约80 MB |
test_ready.csv |
测试集(已预处理和特征工程) | 约75 MB |
数据来源
数据来自房利美单户贷款表现数据。
使用示例
可通过以下Python代码直接加载已处理数据:
python import pandas as pd
train = pd.read_csv("https://huggingface.co/datasets/Shlok112003/Fannie_Mae_Single-Family_Loan_Performance/resolve/main/processed/train_ready.csv") test = pd.read_csv("https://huggingface.co/datasets/Shlok112003/Fannie_Mae_Single-Family_Loan_Performance/resolve/main/processed/test_ready.csv")