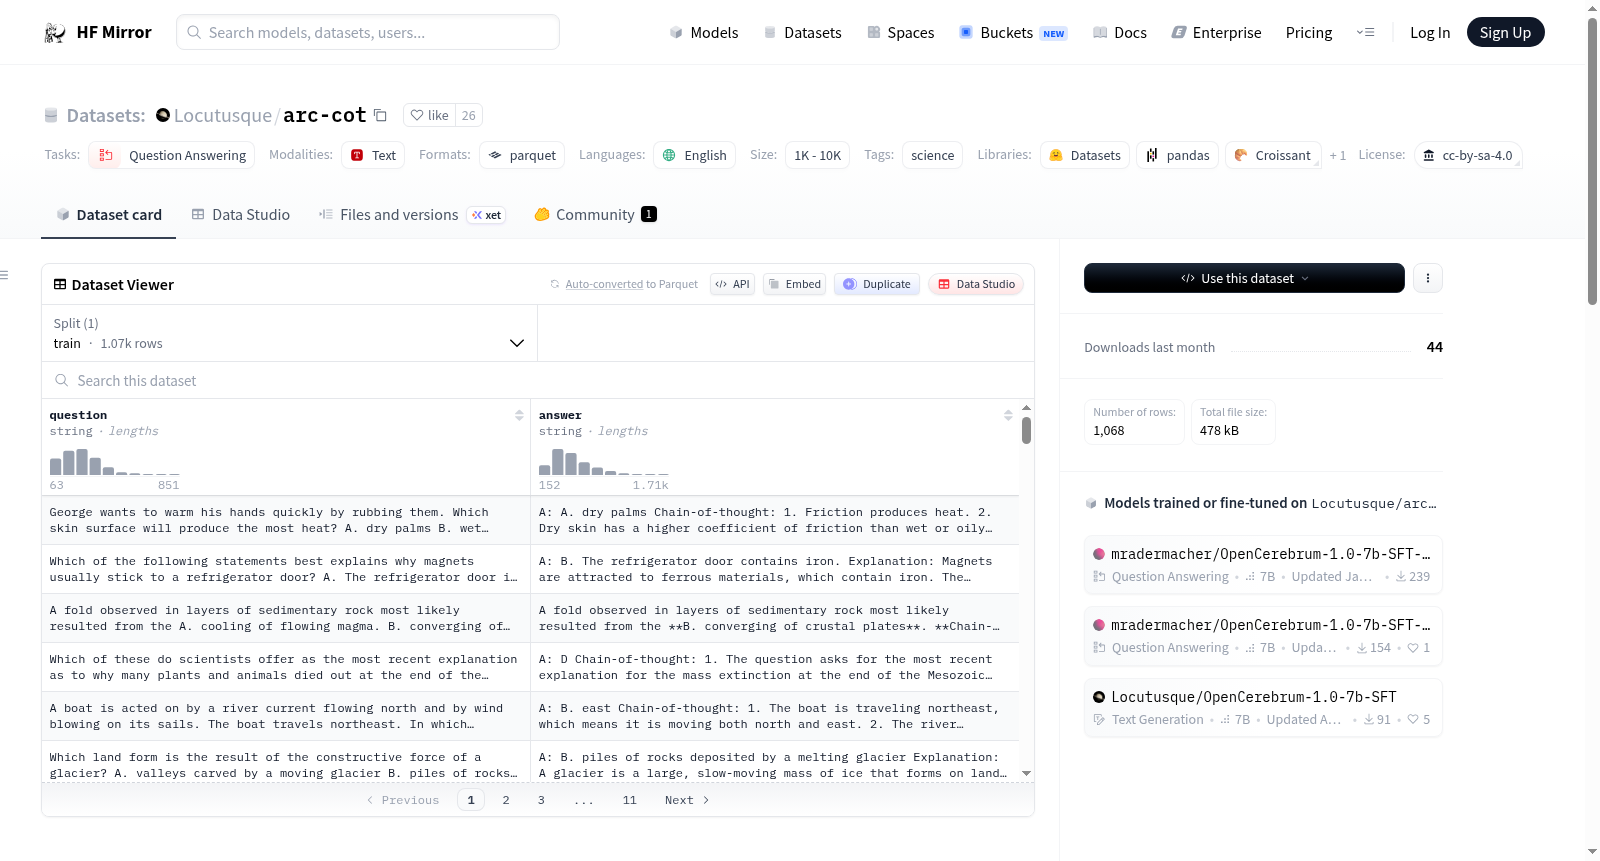
Locutusque/arc-cot
收藏资源简介:
--- dataset_info: features: - name: question dtype: string - name: answer dtype: string splits: - name: train num_bytes: 892187.4506283662 num_examples: 1068 download_size: 473080 dataset_size: 892187.4506283662 configs: - config_name: default data_files: - split: train path: data/train-* license: cc-by-sa-4.0 task_categories: - question-answering language: - en tags: - science size_categories: - n<1K --- # Augmented ARC-Challenge Dataset with Chain-of-Thought Reasoning ## Dataset Description This dataset was created by augmenting the train subset of the [AI2 Reasoning Challenge (ARC) dataset](https://allenai.org/data/arc) with chain-of-thought reasoning generated by Google's Gemini Pro language model. The goal is to provide additional context and intermediate reasoning steps to help models better solve the challenging multiple-choice science questions in ARC. ## Dataset Structure The dataset contains 1068 training examples, with the following features: - `question` (string): The natural language science question. - `answer` (string): The correct answer to the question. ## Dataset Creation The chain-of-thought reasoning for each question-answer pair was generated using Google's Gemini Pro model. The model was given each question and the correct answer, and prompted to provide a detailed chain of reasoning for why that answer is correct. The generated chains of thought aim to break down the reasoning process into clear steps, providing additional context and explanations. The train split of the ARC-Challenge dataset was used as the base, which contains 1068 multiple-choice science questions covering topics like physics, chemistry, biology, and earth science. The questions are generally at a 3rd-9th grade level. ## Intended Use This dataset is intended to be used as a resource to train question answering models on reasoning about science questions. By providing the intermediate reasoning steps, the hope is that models can learn to reason more effectively and transparently about complex questions. Potential use cases include: - Benchmarking question answering models on science reasoning - Analyzing the types of reasoning required for science QA - Improving model interpretability by generating reasoning traces - Studying few-shot learning with in-context chain-of-thought examples ## Limitations and Ethical Considerations The chains of thought are generated by an AI system and may not always be entirely accurate or complete. They should be viewed as a supplemental learning resource rather than guaranteed perfect reasoning. Additionally, the underlying ARC-Challenge questions may contain some social biases, as they are drawn from real-world science exams. Users should be aware of potential biases when training on this data. ## Dataset Specs - Number of examples: 1,068 - Dataset size: 472 KB - Format: parquet
数据集信息: 特征: - 名称:question(问题),数据类型:字符串 - 名称:answer(答案),数据类型:字符串 划分: - 名称:训练集(train),字节数:892187.4506283662,样本数:1068 下载大小:473080 数据集总大小:892187.4506283662 配置: - 配置名称:默认(default),数据文件: - 划分:训练集,路径:data/train-* 许可证:cc-by-sa-4.0 任务类别: - 问答(question-answering) 语言: - 英语(en) 标签: - 科学(science) 规模类别: - n<1K # 带有思维链(Chain-of-Thought)推理的增强型ARC-Challenge数据集 ## 数据集描述 本数据集通过为[AI2推理挑战赛(AI2 Reasoning Challenge, ARC)数据集](https://allenai.org/data/arc)的训练子集添加由谷歌Gemini Pro大语言模型(Large Language Model)生成的思维链推理内容构建而成。其目标是提供额外的上下文与中间推理步骤,帮助模型更好地解决ARC中具有挑战性的多项选择科学类问题。 ## 数据集结构 本数据集包含1068条训练样本,具备如下特征: - `question`(问题,string):自然语言形式的科学问题 - `answer`(答案,string):该问题的正确答案 ## 数据集创建 每条问答对的思维链推理内容均由谷歌的Gemini Pro模型生成。向模型输入对应问题与正确答案,并提示其详细阐述为何该答案正确的推理逻辑。生成的思维链旨在将推理过程拆解为清晰的步骤,提供额外的上下文与解释说明。 本数据集以ARC-Challenge数据集的训练子集为基础,该子集包含1068项多项选择科学问题,涵盖物理、化学、生物与地球科学等领域,题目难度大致对应3至9年级水平。 ## 预期用途 本数据集旨在作为训练问答模型以解决科学问题推理任务的资源。通过提供中间推理步骤,期望模型能够更高效且可解释地学习解决复杂问题的推理能力。 潜在应用场景包括: - 在科学推理任务中对问答模型进行基准测试 - 分析科学问答任务所需的推理类型 - 通过生成推理轨迹提升模型的可解释性 - 结合上下文思维链示例研究少样本(Few-shot)学习 ## 局限性与伦理考量 思维链内容由人工智能系统生成,未必始终完全准确或完备,应将其视为补充性学习资源,而非绝对正确的推理参考。 此外,底层ARC-Challenge数据集的问题可能存在一定社会偏见,因其源自真实的科学考试。使用者在基于该数据进行模型训练时,需注意潜在的偏见问题。 ## 数据集规格 - 样本数量:1068条 - 数据集大小:472 KB - 格式:parquet
数据集概述
数据集名称
Augmented ARC-Challenge Dataset with Chain-of-Thought Reasoning
数据集描述
本数据集通过对AI2 Reasoning Challenge (ARC) dataset的训练子集进行增强,利用Google的Gemini Pro语言模型生成了链式思维推理。旨在为ARC中的挑战性多选科学问题提供额外的上下文和中间推理步骤,以帮助模型更好地解答这些问题。
数据集结构
- 特征:
question(字符串): 自然语言科学问题。answer(字符串): 问题的正确答案。
数据集创建
使用Google的Gemini Pro模型为每个问题-答案对生成链式思维推理。模型被给予每个问题和正确答案,并被提示提供详细的推理链,解释为什么该答案是正确的。生成的推理链旨在将推理过程分解为清晰的步骤,提供额外的上下文和解释。
数据集用途
本数据集旨在作为训练问答模型对科学问题进行推理的资源。通过提供中间推理步骤,希望模型能够更有效地和透明地推理复杂问题。
数据集限制和伦理考虑
- 生成的推理链由AI系统生成,可能不完全准确或完整。
- 基础的ARC-Challenge问题可能包含一些社会偏见,因为它们来自现实世界的科学考试。
数据集规格
- 示例数量: 1,068
- 数据集大小: 472 KB
- 格式: parquet