proxectonos/MT_en-gl
收藏资源简介:
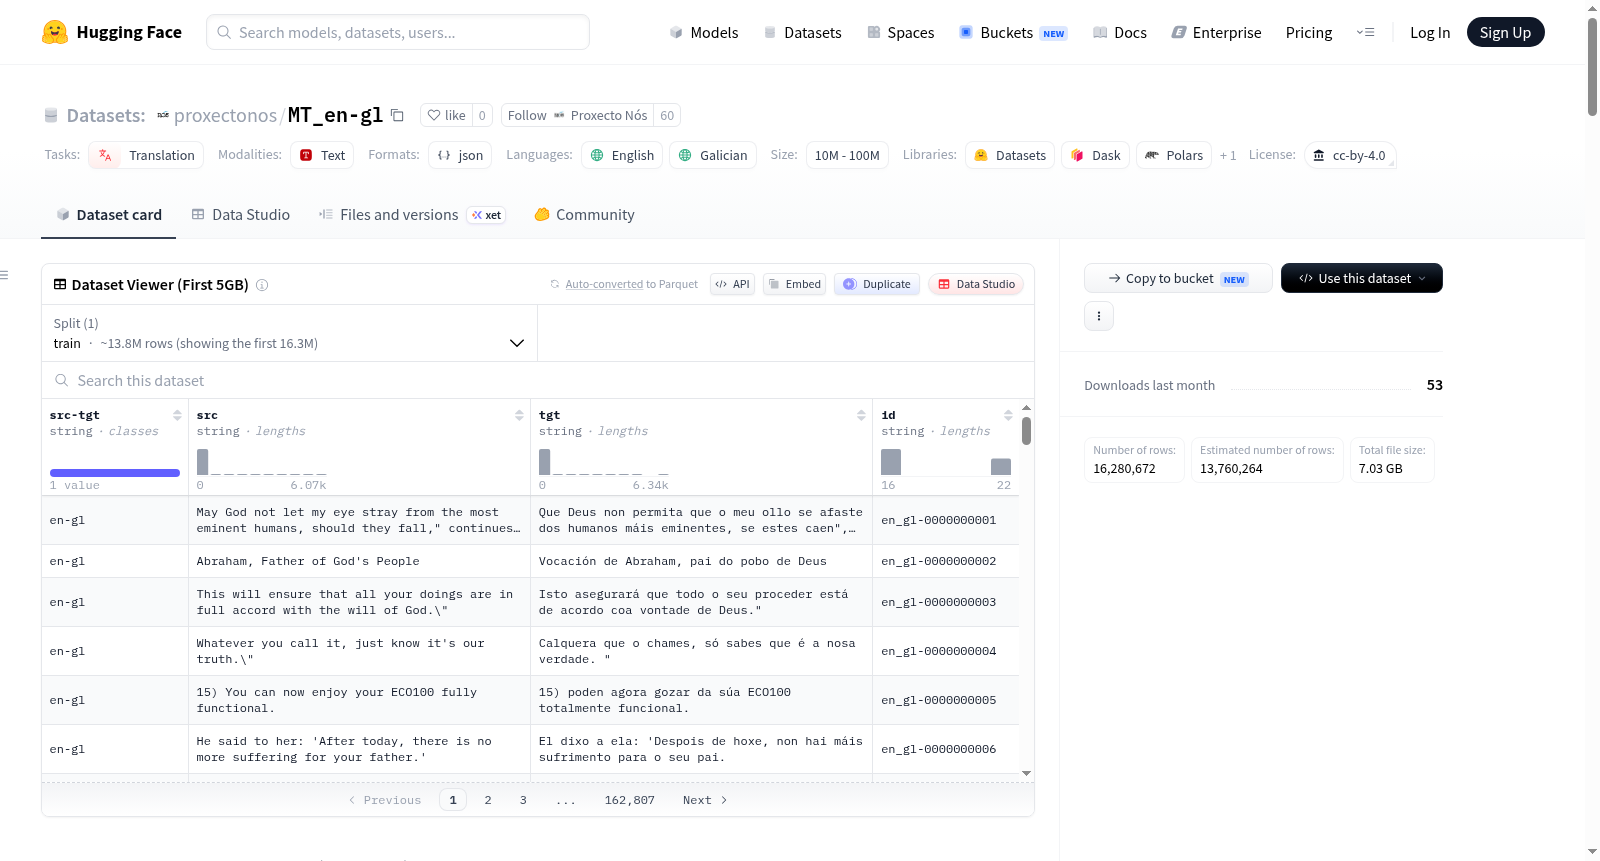
该数据集是一个英语-加利西亚语平行语料库,包含两个JSONL文件:en_gl.jsonl(约998万行,2.6GB)和en_gl_trans.jsonl(约1026万行,4.1GB)。数据格式为JSONL,每个条目包含源语言(英语)和目标语言(加利西亚语)的文本对,以及唯一标识符。en_gl.jsonl通过standard_pipeline处理,包括编码、去重、pyplexity评分、QueLingua语言过滤和标准化;en_gl_trans.jsonl通过PT_GL_parallel处理,涉及机器翻译去重、Apertium和port2gal工具的音译以及标准化。数据来源整合了OPUS中兼容CC BY 4.0许可证的英语-加利西亚语语料库,以及额外非OPUS语料库(如CLUVI文学平行语料库和自定义验证集)。en_gl.jsonl包含自然平行文本,en_gl_trans.jsonl包含机器翻译后编辑的文本。该数据集适用于机器翻译任务,支持英语到加利西亚语的翻译模型训练。
This dataset is an English-Galician parallel corpus consisting of two JSONL files: en_gl.jsonl (approximately 9,982,077 lines, 2.6 GB) and en_gl_trans.jsonl (approximately 10,262,102 lines, 4.1 GB). The data is in JSONL format, with each entry containing source (English) and target (Galician) text pairs, along with a unique identifier. en_gl.jsonl is processed via the standard_pipeline, which includes encoding, deduplication, pyplexity scoring, QueLingua language filtering, and normalization. en_gl_trans.jsonl is processed via the PT_GL_parallel pipeline, involving machine translation deduplication, transliteration using Apertium and port2gal tools, and normalization. The data sources incorporate all available OPUS corpora for the English-Galician pair compatible with the CC BY 4.0 license, as well as additional non-OPUS corpora (such as the CLUVI literary parallel corpus and a custom validation set). en_gl.jsonl contains naturally occurring parallel text, while en_gl_trans.jsonl contains machine-translated and post-edited text. This dataset is suitable for machine translation tasks, supporting training models for English-to-Galician translation.