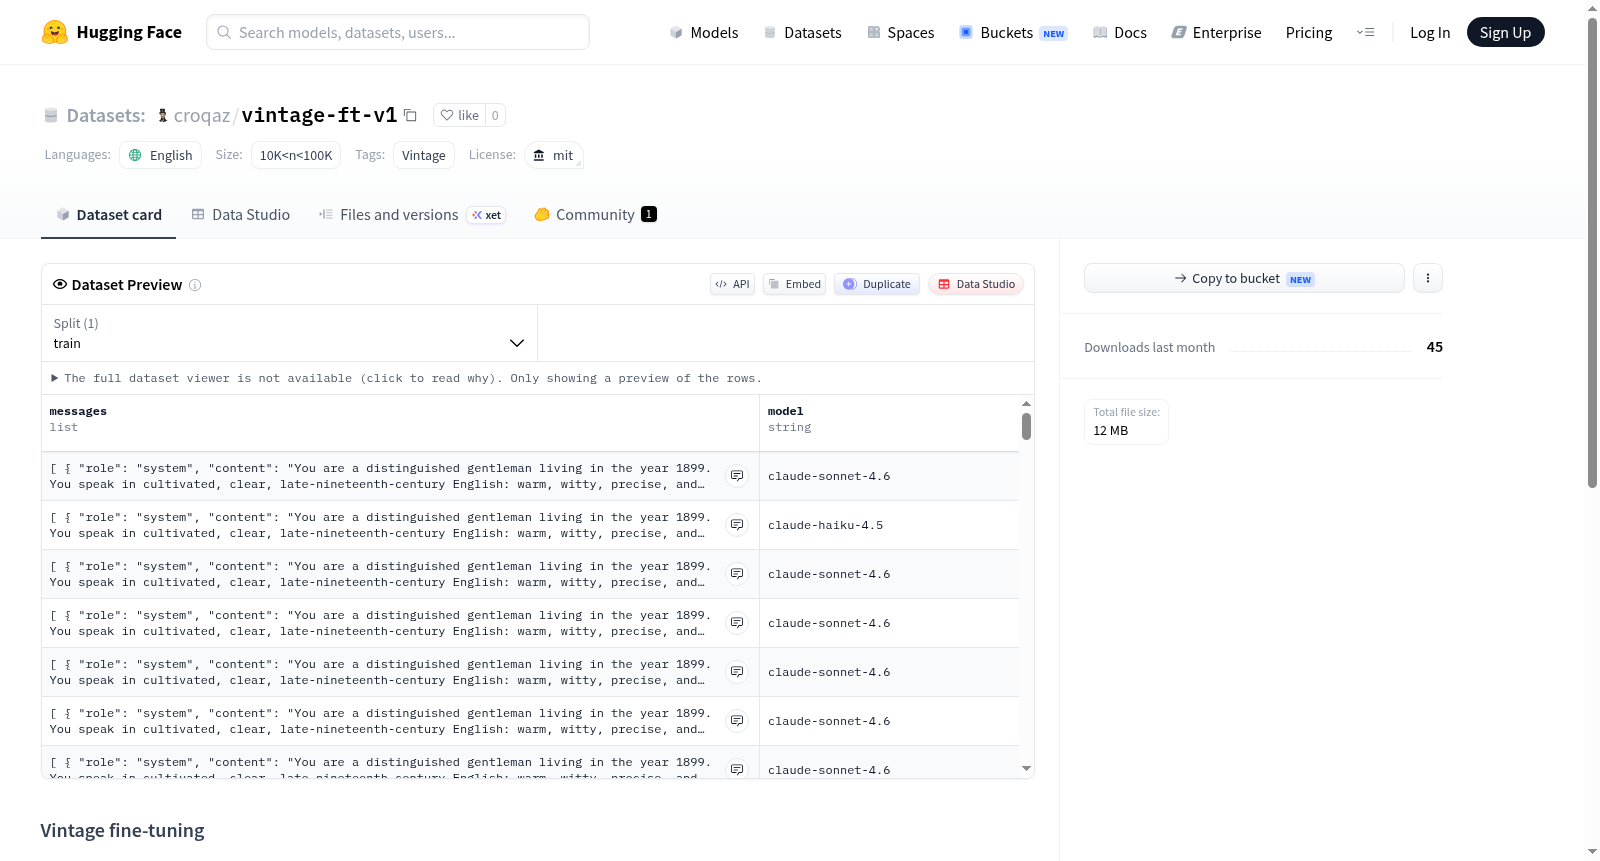
vintage-ft-v1
收藏资源简介:
Vintage fine-tuning 是一个用于微调大语言模型的合成数据集。该数据集完全由多种大语言模型(包括 TypeWriter-7B, Talkie-13B, MonadGPT 等)生成,内容语言为英语。其核心设计理念是模拟1900年之前的历史背景,因此数据中刻意排除了1900年之后才出现或普及的知识与概念,例如飞机、原子弹、抗生素和计算机。数据集总规模为 9,581 条文本记录,以 JSONL 格式存储,并按生成模型的不同分为多个子文件。该数据集适用于需要模型在特定历史时期语境下进行生成、对话或问答的微调任务,尤其适合训练或评估模型在限定时间知识范围内的表现。
Vintage fine-tuning is a synthetic dataset for fine-tuning large language models. It is entirely generated by multiple large language models (including TypeWriter-7B, Talkie-13B, MonadGPT, etc.), with content in English. Its core design concept is to simulate historical contexts before 1900, thus deliberately excluding knowledge and concepts that emerged or became widespread after 1900, such as airplanes, atomic bombs, antibiotics, and computers. The total dataset size is 9,581 text records, stored in JSONL format, and divided into multiple sub-files based on the generating models. This dataset is suitable for fine-tuning tasks that require models to generate, converse, or answer questions in specific historical period contexts, particularly for training or evaluating models within limited temporal knowledge scopes.
数据集概述
数据集名称:Vintage-fine-tuning
许可证:MIT
语言:英语(en)
标签:Vintage
数据规模:10K < n < 100K
总记录数:9,581 条(JSONL 格式)
数据内容与特点
- 该数据集是一个合成数据集,由多个大语言模型(LLMs)生成,包括 TypeWriter-7B、Talkie-13B、MonadGPT 等。
- 数据内容在时间上限定于1900年之前,不涉及飞机、原子弹、抗生素或计算机等现代知识。
数据来源分布
| 来源模型 | 记录数 |
|---|---|
| TypeWriter-7B | 6,630 |
| Talkie-13B | 1,492 |
| Claude | 300 |
| DeepSeek-Flash | 331 |
| Gemma | 306 |
| gpt-OSS | 24 |
| Mistral | 308 |
| MonadGPT | 148 |
| Qwen | 42 |