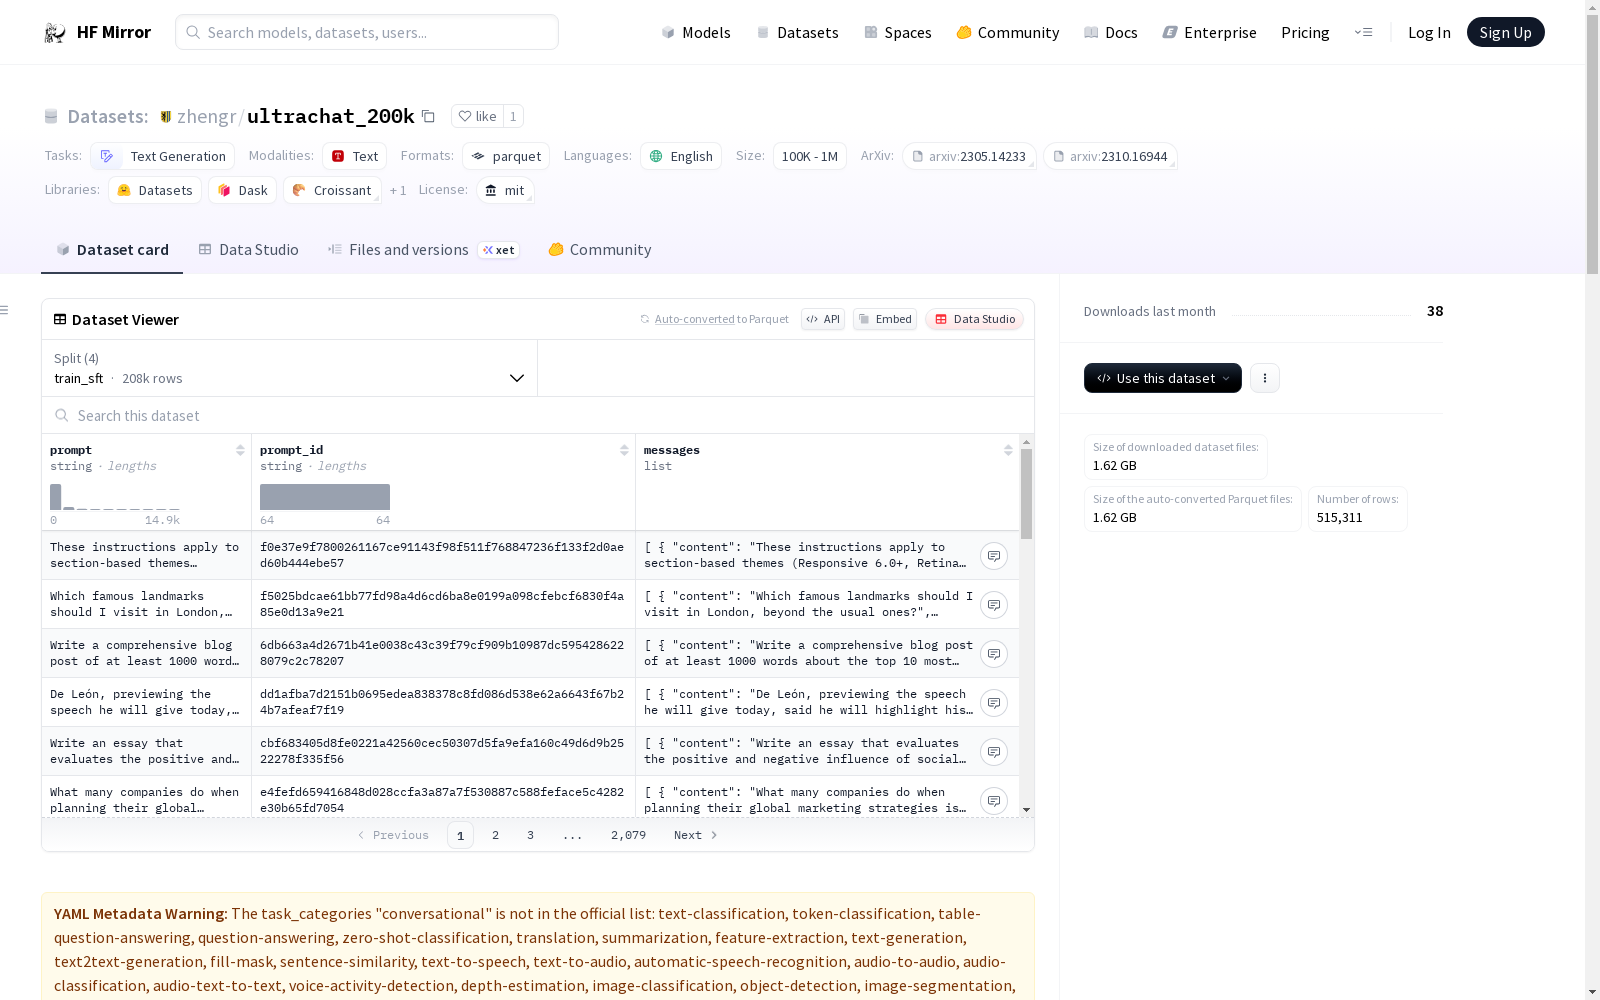
zhengr/ultrachat_200k
收藏资源简介:
--- language: - en license: mit size_categories: - 100K<n<1M task_categories: - conversational - text-generation pretty_name: UltraChat 200k configs: - config_name: default data_files: - split: train_sft path: data/train_sft-* - split: test_sft path: data/test_sft-* - split: train_gen path: data/train_gen-* - split: test_gen path: data/test_gen-* dataset_info: features: - name: prompt dtype: string - name: prompt_id dtype: string - name: messages list: - name: content dtype: string - name: role dtype: string splits: - name: train_sft num_bytes: 1397058554 num_examples: 207865 - name: test_sft num_bytes: 154695659 num_examples: 23110 - name: train_gen num_bytes: 1347396812 num_examples: 256032 - name: test_gen num_bytes: 148276089 num_examples: 28304 download_size: 1624049723 dataset_size: 3047427114 --- # Dataset Card for UltraChat 200k ## Dataset Description This is a heavily filtered version of the [UltraChat](https://github.com/thunlp/UltraChat) dataset and was used to train [Zephyr-7B-β](https://huggingface.co/HuggingFaceH4/zephyr-7b-beta), a state of the art 7b chat model. The original datasets consists of 1.4M dialogues generated by ChatGPT and spanning a wide range of topics. To create `UltraChat 200k`, we applied the following logic: - Selection of a subset of data for faster supervised fine tuning. - Truecasing of the dataset, as we observed around 5% of the data contained grammatical errors like "Hello. how are you?" instead of "Hello. How are you?" - Removal of dialogues where the assistant replies with phrases like "I do not have emotions" or "I don't have opinions", even for fact-based prompts that don't involve either. ## Dataset Structure The dataset has four splits, suitable for: * Supervised fine-tuning (`sft`). * Generation ranking (`gen`) via techniques like rejection sampling or PPO. The number of examples per split is shown as follows: | train_sft | test_sft | train_gen | test_gen | |:-------:|:-----------:|:-----:| :-----:| | 207865 | 23110 | 256032 | 28304 | The dataset is stored in parquet format with each entry using the following schema: ``` { "prompt": "Create a fully-developed protagonist who is challenged to survive within a dystopian society under the rule of a tyrant. ...", "messages":[ { "content": "Create a fully-developed protagonist who is challenged to survive within a dystopian society under the rule of a tyrant. ...", "role": "user" }, { "content": "Name: Ava\n\n Ava was just 16 years old when the world as she knew it came crashing down. The government had collapsed, leaving behind a chaotic and lawless society. ...", "role": "assistant" }, { "content": "Wow, Ava's story is so intense and inspiring! Can you provide me with more details. ...", "role": "user" }, { "content": "Certainly! ....", "role": "assistant" }, { "content": "That's really interesting! I would love to hear more...", "role": "user" } { "content": "Certainly! ....", "role": "assistant" }, ], "prompt_id": "d938b65dfe31f05f80eb8572964c6673eddbd68eff3db6bd234d7f1e3b86c2af" } ``` ## Citation If you find this dataset is useful in your work, please cite the original UltraChat dataset: ``` @misc{ding2023enhancing, title={Enhancing Chat Language Models by Scaling High-quality Instructional Conversations}, author={Ning Ding and Yulin Chen and Bokai Xu and Yujia Qin and Zhi Zheng and Shengding Hu and Zhiyuan Liu and Maosong Sun and Bowen Zhou}, year={2023}, eprint={2305.14233}, archivePrefix={arXiv}, primaryClass={cs.CL} } ``` You may also wish to cite the Zephyr 7B technical report: ``` @misc{tunstall2023zephyr, title={Zephyr: Direct Distillation of LM Alignment}, author={Lewis Tunstall and Edward Beeching and Nathan Lambert and Nazneen Rajani and Kashif Rasul and Younes Belkada and Shengyi Huang and Leandro von Werra and Clémentine Fourrier and Nathan Habib and Nathan Sarrazin and Omar Sanseviero and Alexander M. Rush and Thomas Wolf}, year={2023}, eprint={2310.16944}, archivePrefix={arXiv}, primaryClass={cs.LG} } ```
--- 语言: - en 许可证:mit 规模类别: - 10万<样本量<100万 任务类别: - 对话式 - 文本生成 展示名称:UltraChat 200k 配置项: - 配置名称:default 数据文件: - 拆分:train_sft(训练监督微调) 路径:data/train_sft-* - 拆分:test_sft(测试监督微调) 路径:data/test_sft-* - 拆分:train_gen(训练生成) 路径:data/train_gen-* - 拆分:test_gen(测试生成) 路径:data/test_gen-* 数据集信息: 特征: - 名称:prompt(提示词) 数据类型:字符串 - 名称:prompt_id(提示词ID) 数据类型:字符串 - 名称:messages(对话列表) 列表项: - 名称:content(对话内容) 数据类型:字符串 - 名称:role(对话角色) 数据类型:字符串 数据拆分: - 拆分名称:train_sft 字节数:1397058554 样本数:207865 - 拆分名称:test_sft 字节数:154695659 样本数:23110 - 拆分名称:train_gen 字节数:1347396812 样本数:256032 - 拆分名称:test_gen 字节数:148276089 样本数:28304 下载总大小:1624049723 数据集总大小:3047427114 --- # UltraChat 200k 数据集卡片 ## 数据集描述 本数据集是[UltraChat](https://github.com/thunlp/UltraChat)数据集的高精度过滤版本,曾用于训练当前业界领先的70亿参数对话模型[Zephyr-7B-β](https://huggingface.co/HuggingFaceH4/zephyr-7b-beta)。 原始UltraChat数据集包含140万段由ChatGPT生成的对话,涵盖海量主题。为构建`UltraChat 200k`,我们采用了如下筛选逻辑: - 选取精简子集以加速监督微调流程; - 对数据集进行大小写标准化处理:经观测,约5%的数据存在格式语法错误,例如将标准表达"Hello. How are you?"误写为"Hello. how are you?"; - 移除助手回复包含"我没有情绪"或"我不具备观点"这类语句的对话,即便提示词为不涉及此类内容的事实类问题。 ## 数据集结构 本数据集包含四个拆分,分别适配以下场景: * 监督微调(`sft`) * 基于生成排序(`gen`),可配合拒绝采样、近端策略优化(PPO,Proximal Policy Optimization)等技术使用。 各拆分的样本量如下: | 训练监督拆分(train_sft) | 测试监督拆分(test_sft) | 训练生成拆分(train_gen) | 测试生成拆分(test_gen) | |:-----------------------:|:-----------------------:|:-----------------------:|:-----------------------:| | 207865 | 23110 | 256032 | 28304 | 本数据集以Parquet格式存储,每条数据的结构示例如下: json { "prompt": "请塑造一个丰满的主角,使其在暴君统治的反乌托邦社会中挣扎求生。……", "messages":[ { "content": "请塑造一个丰满的主角,使其在暴君统治的反乌托邦社会中挣扎求生。……", "role": "用户(user)" }, { "content": "姓名:艾娃 艾娃16岁那年,她所熟知的世界彻底崩塌。政府倒台后,社会陷入混乱与无政府状态。……", "role": "助手(assistant)" }, { "content": "哇,艾娃的故事既紧张又鼓舞人心!能再给我讲讲更多细节吗?……", "role": "用户(user)" }, { "content": "当然可以!……", "role": "助手(assistant)" }, { "content": "这真的很有趣!我还想了解更多……", "role": "用户(user)" }, { "content": "当然可以!……", "role": "助手(assistant)" } ], "prompt_id": "d938b65dfe31f05f80eb8572964c6673eddbd68eff3db6bd234d7f1e3b86c2af" } ## 引用规范 若本数据集对你的研究有所帮助,请引用原始UltraChat数据集: bibtex @misc{ding2023enhancing, title={Enhancing Chat Language Models by Scaling High-quality Instructional Conversations}, author={Ning Ding and Yulin Chen and Bokai Xu and Yujia Qin and Zhi Zheng and Shengding Hu and Zhiyuan Liu and Maosong Sun and Bowen Zhou}, year={2023}, eprint={2305.14233}, archivePrefix={arXiv}, primaryClass={cs.CL} } 你也可以引用Zephyr 7B的技术报告: bibtex @misc{tunstall2023zephyr, title={Zephyr: Direct Distillation of LM Alignment}, author={Lewis Tunstall and Edward Beeching and Nathan Lambert and Nazneen Rajani and Kashif Rasul and Younes Belkada and Shengyi Huang and Leandro von Werra and Clémentine Fourrier and Nathan Habib and Nathan Sarrazin and Omar Sanseviero and Alexander M. Rush and Thomas Wolf}, year={2023}, eprint={2310.16944}, archivePrefix={arXiv}, primaryClass={cs.LG} }
UltraChat 200k 数据集概述
数据集描述
UltraChat 200k 是一个经过筛选的 UltraChat 数据集版本,用于训练 Zephyr-7B-β,这是一个先进的 7b 聊天模型。原始数据集包含 1.4M 个由 ChatGPT 生成的对话,涵盖广泛的主题。为了创建 UltraChat 200k,我们应用了以下逻辑:
- 选择部分数据以加快监督微调。
- 对数据集进行大小写修正,因为我们观察到约 5% 的数据包含语法错误,例如 "Hello. how are you?" 而不是 "Hello. How are you?"。
- 删除助手回复中包含 "I do not have emotions" 或 "I dont have opinions" 等短语的对话,即使在基于事实的提示中不涉及这些内容。
数据集结构
数据集包含四个部分,适用于:
- 监督微调(
sft)。 - 生成排序(
gen),通过拒绝采样或 PPO 等技术。
每个部分的示例数量如下:
| train_sft | test_sft | train_gen | test_gen |
|---|---|---|---|
| 207865 | 23110 | 256032 | 28304 |
数据集以 parquet 格式存储,每个条目使用以下模式:
json { "prompt": "Create a fully-developed protagonist who is challenged to survive within a dystopian society under the rule of a tyrant. ...", "messages":[ { "content": "Create a fully-developed protagonist who is challenged to survive within a dystopian society under the rule of a tyrant. ...", "role": "user" }, { "content": "Name: Ava
Ava was just 16 years old when the world as she knew it came crashing down. The government had collapsed, leaving behind a chaotic and lawless society. ...", "role": "assistant" }, { "content": "Wow, Avas story is so intense and inspiring! Can you provide me with more details. ...", "role": "user" }, { "content": "Certainly! ....", "role": "assistant" }, { "content": "Thats really interesting! I would love to hear more...", "role": "user" }, { "content": "Certainly! ....", "role": "assistant" }, ], "prompt_id": "d938b65dfe31f05f80eb8572964c6673eddbd68eff3db6bd234d7f1e3b86c2af" }
引用
如果您发现此数据集在您的工作中有用,请引用原始的 UltraChat 数据集:
bibtex @misc{ding2023enhancing, title={Enhancing Chat Language Models by Scaling High-quality Instructional Conversations}, author={Ning Ding and Yulin Chen and Bokai Xu and Yujia Qin and Zhi Zheng and Shengding Hu and Zhiyuan Liu and Maosong Sun and Bowen Zhou}, year={2023}, eprint={2305.14233}, archivePrefix={arXiv}, primaryClass={cs.CL} }
您也可以引用 Zephyr 7B 技术报告:
bibtex @misc{tunstall2023zephyr, title={Zephyr: Direct Distillation of LM Alignment}, author={Lewis Tunstall and Edward Beeching and Nathan Lambert and Nazneen Rajani and Kashif Rasul and Younes Belkada and Shengyi Huang and Leandro von Werra and Clémentine Fourrier and Nathan Habib and Nathan Sarrazin and Omar Sanseviero and Alexander M. Rush and Thomas Wolf}, year={2023}, eprint={2310.16944}, archivePrefix={arXiv}, primaryClass={cs.LG} }