
LibriTTS
收藏arXiv2025-09-30 收录
数据链接:
官方服务:
资源简介:
该数据集是一个大规模的多说话人数据集,专门用于训练语音转换模型。它包含了来自不同说话人的清晰音频样本。数据集还包括了如train-clean-360和train-clean-100等不同的子集。总规模达到了110小时的音频样本,涵盖了1,151位说话人,其任务重点是语音转换。
This dataset is a large-scale multi-speaker corpus specifically designed for training voice conversion models. It contains clear audio samples from a wide range of speakers. The dataset also includes distinct subsets such as train-clean-360 and train-clean-100. The total duration of the audio samples reaches 110 hours, covering 1,151 unique speakers, with its core task focusing on voice conversion.
提供机构:
LibriTTS搜集汇总
数据集介绍
背景与挑战
背景概述
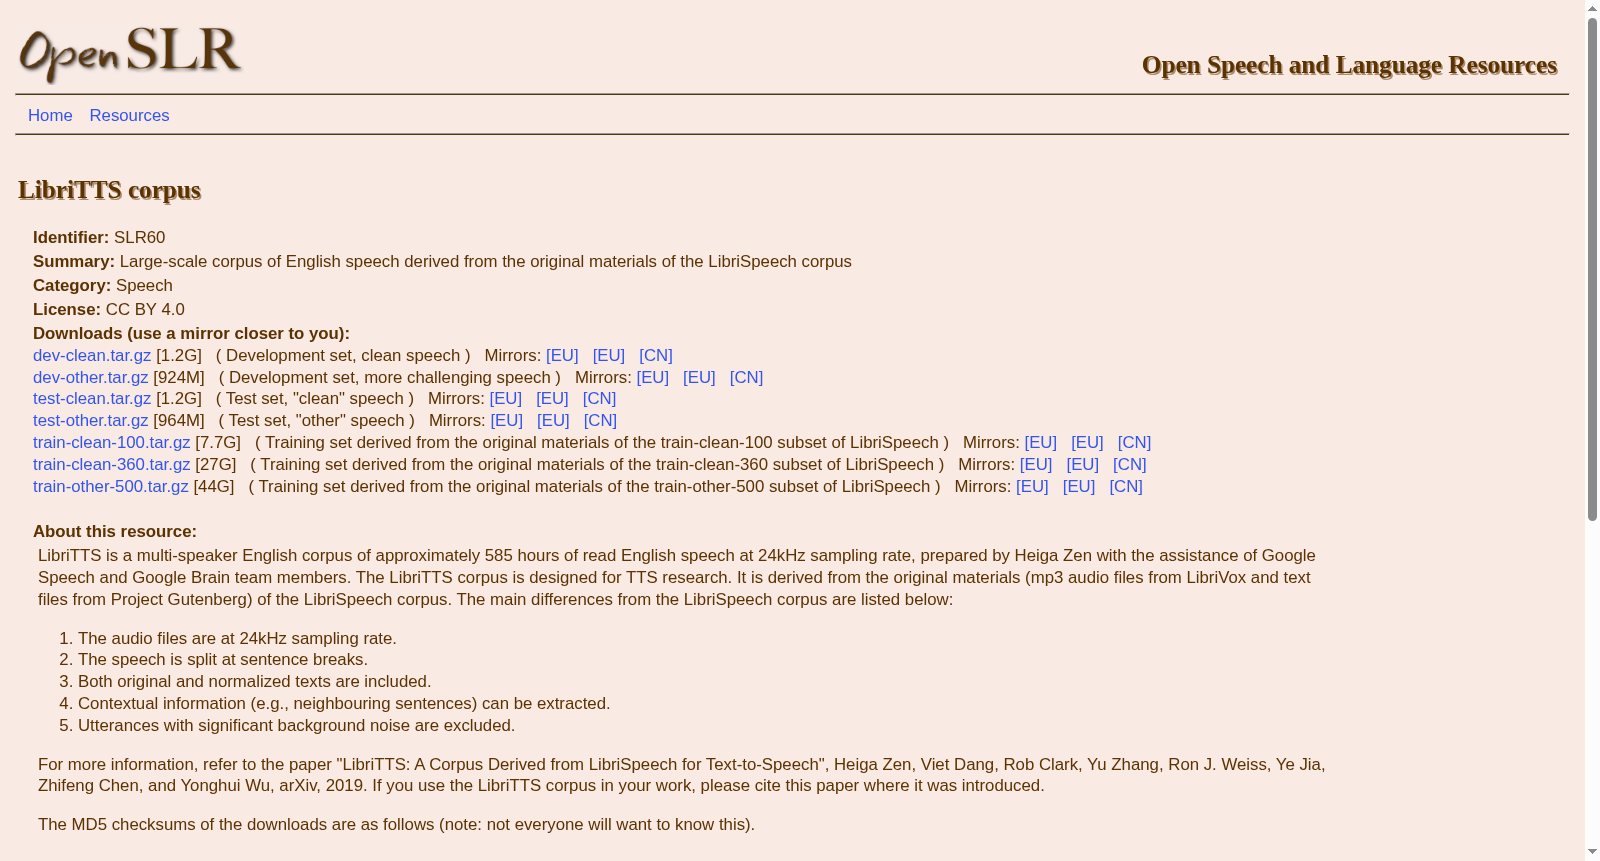
LibriTTS是一个大型英语语音语料库,源自LibriSpeech,包含约585小时的24kHz采样率朗读语音,专为文本到语音研究设计。其特点包括按句子分割音频、提供原始和规范化文本,并排除背景噪音,以提高语音合成模型训练的质量。数据集分为开发集、测试集和训练集,支持多说话人场景,适用于语音技术研究。
以上内容由遇见数据集搜集并总结生成


