jkorsvik/nowiki_second_scrape_merged
收藏资源简介:
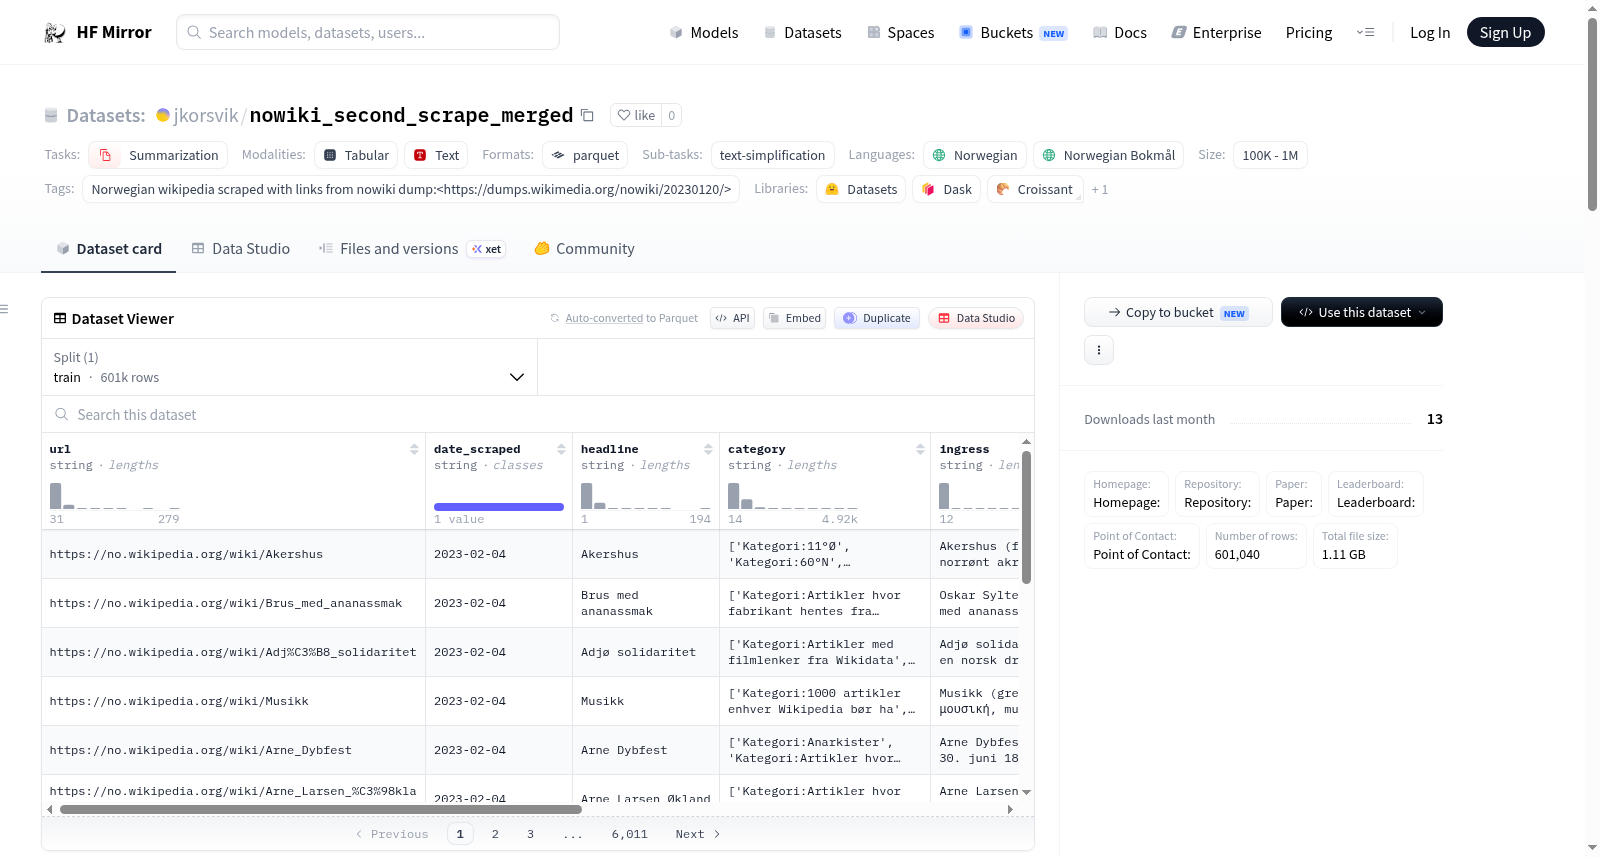
--- annotations_creators: - jkorsvik - machine-generated language: - no - nob language_creators: - found - jkorsvik license: [] multilinguality: - monolingual pretty_name: nowiki_second_scrape_merged size_categories: - 100K<n<1M source_datasets: - original tags: - 'Norwegian wikipedia scraped with links from nowiki dump:<https://dumps.wikimedia.org/nowiki/20230120/>' task_categories: - summarization - text2text-generation task_ids: - text-simplification dataset_info: features: - name: url dtype: string - name: date_scraped dtype: string - name: headline dtype: string - name: category dtype: string - name: ingress dtype: string - name: article dtype: string - name: abstract dtype: string - name: id dtype: int64 - name: __index_level_0__ dtype: int64 splits: - name: train num_bytes: 2321106744 num_examples: 601040 download_size: 1109052656 dataset_size: 2321106744 --- # Dataset Card for "nowiki_second_scrape_merged" ## Table of Contents - [Table of Contents](#table-of-contents) - [Dataset Description](#dataset-description) - [Dataset Summary](#dataset-summary) - [Supported Tasks and Leaderboards](#supported-tasks-and-leaderboards) - [Languages](#languages) - [Dataset Structure](#dataset-structure) - [Data Instances](#data-instances) - [Data Fields](#data-fields) - [Data Splits](#data-splits) - [Dataset Creation](#dataset-creation) - [Curation Rationale](#curation-rationale) - [Source Data](#source-data) - [Annotations](#annotations) - [Personal and Sensitive Information](#personal-and-sensitive-information) - [Considerations for Using the Data](#considerations-for-using-the-data) - [Social Impact of Dataset](#social-impact-of-dataset) - [Discussion of Biases](#discussion-of-biases) - [Other Known Limitations](#other-known-limitations) - [Additional Information](#additional-information) - [Dataset Curators](#dataset-curators) - [Licensing Information](#licensing-information) - [Citation Information](#citation-information) - [Contributions](#contributions) ## Dataset Description - **Homepage:** - **Repository:** - **Paper:** - **Leaderboard:** - **Point of Contact:** ### Dataset Summary [More Information Needed] ### Supported Tasks and Leaderboards [More Information Needed] ### Languages [More Information Needed] ## Dataset Structure ### Data Instances [More Information Needed] ### Data Fields [More Information Needed] ### Data Splits [More Information Needed] ## Dataset Creation ### Curation Rationale [More Information Needed] ### Source Data #### Initial Data Collection and Normalization [More Information Needed] #### Who are the source language producers? [More Information Needed] ### Annotations #### Annotation process [More Information Needed] #### Who are the annotators? [More Information Needed] ### Personal and Sensitive Information [More Information Needed] ## Considerations for Using the Data ### Social Impact of Dataset [More Information Needed] ### Discussion of Biases [More Information Needed] ### Other Known Limitations [More Information Needed] ## Additional Information ### Dataset Curators [More Information Needed] ### Licensing Information [More Information Needed] ### Citation Information [More Information Needed] ### Contributions Thanks to [@jkorsvik](https://github.com/jkorsvik) for adding this dataset.
annotations_creators: - jkorsvik - 机器生成 language: - 挪威语(no) - 书面挪威语(nob) language_creators: - 公开采集 - jkorsvik license: [] multilinguality: - 单语言 pretty_name: nowiki_second_scrape_merged size_categories: - 100K<n<1M source_datasets: - 原始数据集 tags: - '使用来自nowiki转储的链接抓取的挪威语维基百科:<https://dumps.wikimedia.org/nowiki/20230120/>' task_categories: - 摘要生成 - 文本到文本生成 task_ids: - 文本简化 dataset_info: features: - name: url dtype: 字符串 - name: date_scraped dtype: 字符串 - name: headline dtype: 字符串 - name: category dtype: 字符串 - name: ingress dtype: 字符串 - name: article dtype: 字符串 - name: abstract dtype: 字符串 - name: id dtype: 64位整数 - name: __index_level_0__ dtype: 64位整数 splits: - name: 训练集 num_bytes: 2321106744 num_examples: 601040 download_size: 1109052656 dataset_size: 2321106744 --- # 数据集卡片:nowiki_second_scrape_merged ## 目录 - [目录](#table-of-contents) - [数据集描述](#dataset-description) - [数据集摘要](#dataset-summary) - [支持任务与排行榜](#supported-tasks-and-leaderboards) - [语言](#languages) - [数据集结构](#dataset-structure) - [数据实例](#data-instances) - [数据字段](#data-fields) - [数据划分](#data-splits) - [数据集构建](#dataset-creation) - [构建依据](#curation-rationale) - [源数据](#source-data) - [注释信息](#annotations) - [个人与敏感信息](#personal-and-sensitive-information) - [数据集使用注意事项](#considerations-for-using-the-data) - [数据集的社会影响](#social-impact-of-dataset) - [偏差讨论](#discussion-of-biases) - [其他已知局限性](#other-known-limitations) - [附加信息](#additional-information) - [数据集维护者](#dataset-curators) - [许可信息](#licensing-information) - [引用信息](#citation-information) - [贡献](#contributions) ## 数据集描述 - **主页:** - **仓库地址:** - **相关论文:** - **排行榜:** - **联系人:** ### 数据集摘要 [需补充更多信息] ### 支持任务与排行榜 [需补充更多信息] ### 语言 [需补充更多信息] ## 数据集结构 ### 数据实例 [需补充更多信息] ### 数据字段 [需补充更多信息] ### 数据划分 [需补充更多信息] ## 数据集构建 ### 构建依据 [需补充更多信息] ### 源数据 #### 初始数据采集与标准化 [需补充更多信息] #### 源语言内容创作者是谁? [需补充更多信息] ### 注释信息 #### 注释流程 [需补充更多信息] #### 注释者是谁? [需补充更多信息] ### 个人与敏感信息 [需补充更多信息] ## 数据集使用注意事项 ### 数据集的社会影响 [需补充更多信息] ### 偏差讨论 [需补充更多信息] ### 其他已知局限性 [需补充更多信息] ## 附加信息 ### 数据集维护者 [需补充更多信息] ### 许可信息 [需补充更多信息] ### 引用信息 [需补充更多信息] ### 贡献 感谢[@jkorsvik](https://github.com/jkorsvik) 为本数据集提供支持。
数据集概述
数据集名称
- pretty_name: nowiki_second_scrape_merged
语言
- 语言: no, nob
- 语言创建者: found, jkorsvik
多语言性
- multilinguality: monolingual
大小分类
- size_categories: 100K<n<1M
源数据集
- source_datasets: original
标签
- tags: Norwegian wikipedia scraped with links from nowiki dump: https://dumps.wikimedia.org/nowiki/20230120/
任务类别
- task_categories: summarization, text2text-generation
任务ID
- task_ids: text-simplification
数据集结构
数据特征
- features:
- name: url dtype: string
- name: date_scraped dtype: string
- name: headline dtype: string
- name: category dtype: string
- name: ingress dtype: string
- name: article dtype: string
- name: abstract dtype: string
- name: id dtype: int64
- name: index_level_0 dtype: int64
数据分割
- splits:
- name: train num_bytes: 2321106744 num_examples: 601040
- download_size: 1109052656
- dataset_size: 2321106744