damlab/HIV_PI
收藏资源简介:
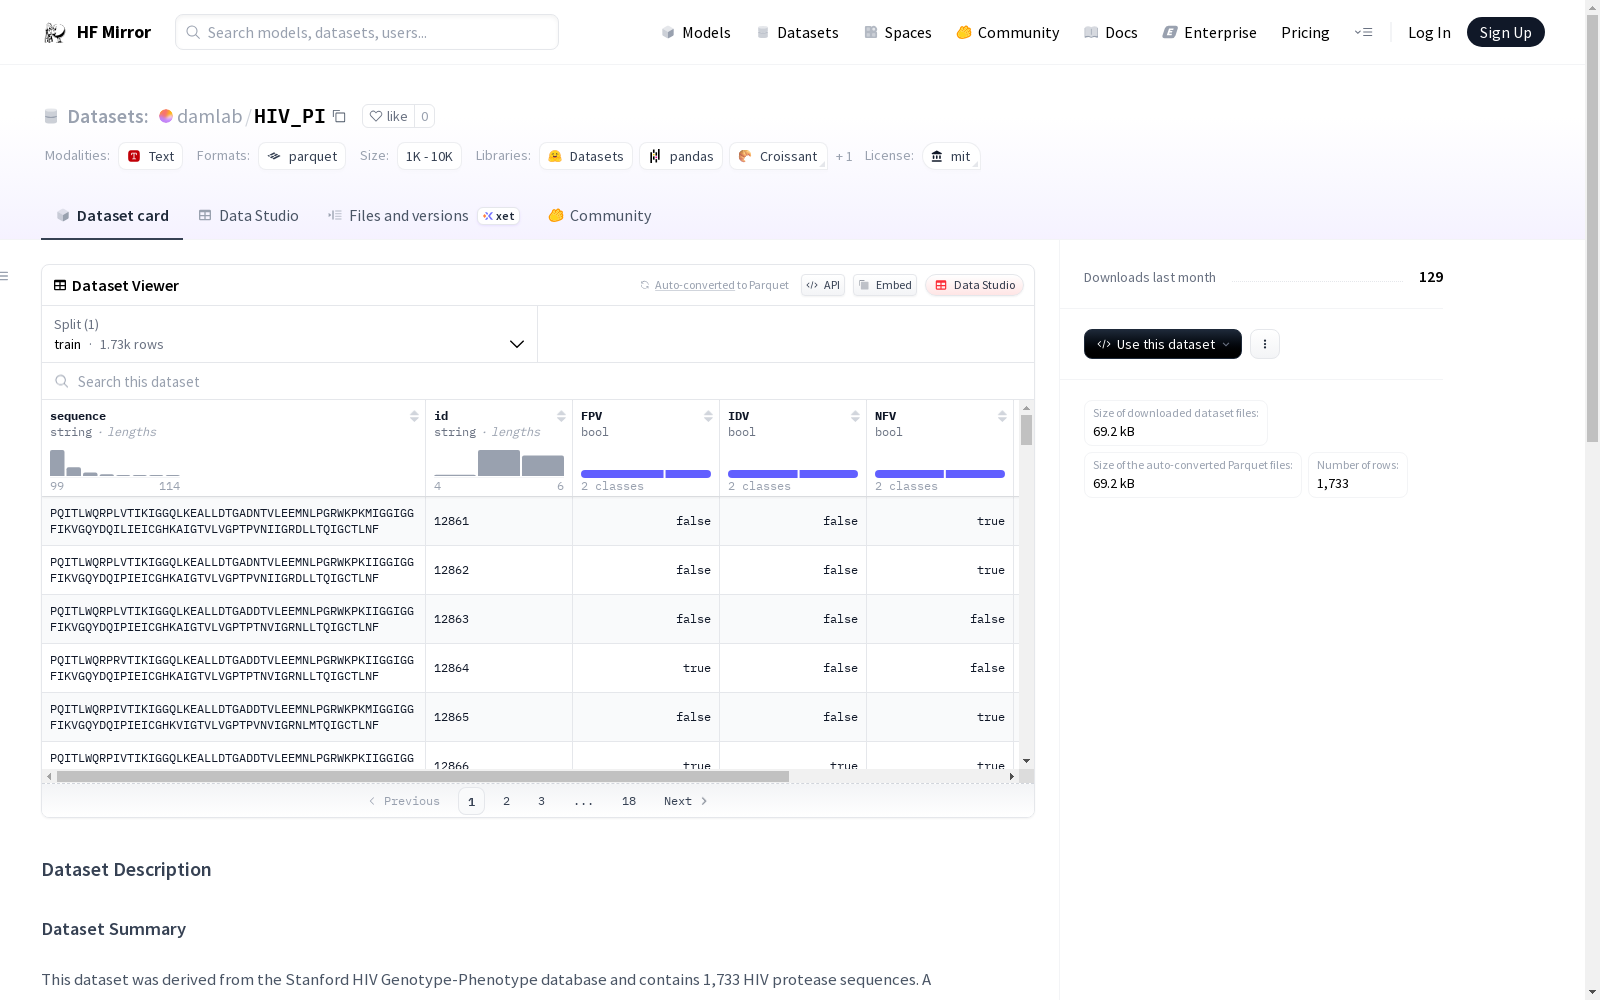
--- license: mit --- # Dataset Description ## Dataset Summary This dataset was derived from the Stanford HIV Genotype-Phenotype database and contains 1,733 HIV protease sequences. A pproximately half of the sequences are resistant to at least one antiretroviral therapeutic (ART). Supported Tasks and Leaderboards: None Languages: English ## Dataset Structure ### Data Instances Each column represents the protein amino acid sequence of the HIV protease protein. The ID field indicates the Genbank reference ID for future cross-referencing. There are 1,733 total protease sequences. Data Fields: ID, sequence, fold, FPV, IDV, NFV, SQV Data Splits: None ## Dataset Creation Curation Rationale: This dataset was curated to train a model (HIV-BERT-PI) designed to predict whether an HIV protease sequence would result in resistance to certain antiretroviral (ART) drugs. Initial Data Collection and Normalization: Dataset was downloaded and curated on 12/21/2021. ## Considerations for Using the Data Social Impact of Dataset: Due to the tendency of HIV to mutate, drug resistance is a common issue when attempting to treat those infected with HIV. Protease inhibitors are a class of drugs that HIV is known to develop resistance via mutations. Thus, by providing a collection of protease sequences known to be resistant to one or more drugs, this dataset provides a significant collection of data that could be utilized to perform computational analysis of protease resistance mutations. Discussion of Biases: Due to the sampling nature of this database, it is predominantly composed of subtype B sequences from North America and Europe with only minor contributions of Subtype C, A, and D. Currently, there was no effort made to balance the performance across these classes. As such, one should consider refinement with additional sequences to perform well on non-B sequences. ## Additional Information: - Dataset Curators: Will Dampier - Citation Information: TBA
许可证:MIT许可证 # 数据集描述 ## 数据集摘要 本数据集源自斯坦福HIV基因型-表型数据库(Stanford HIV Genotype-Phenotype database),共包含1733条HIV蛋白酶序列,其中约半数序列对至少一种抗逆转录病毒治疗药物(antiretroviral therapeutic, ART)具有耐药性。 支持任务与排行榜:无 语言:英语 ## 数据集结构 ### 数据实例 每一列对应HIV蛋白酶(HIV protease)的蛋白质氨基酸序列。ID字段用于标注基因银行(GenBank)参考编号,以便后续交叉引用。本数据集共包含1733条蛋白酶序列。 数据字段:ID、序列(sequence)、fold、FPV、IDV、NFV、SQV 数据划分:无 ## 数据集构建 ### 整理依据 本数据集的整理旨在用于训练HIV-BERT-PI模型,该模型用于预测某条HIV蛋白酶序列是否会对特定抗逆转录病毒治疗(ART)药物产生耐药性。 初始数据收集与标准化处理:本数据集于2021年12月21日完成下载与整理。 ## 数据使用注意事项 ### 数据集社会影响 由于HIV具有高频突变特性,在治疗HIV感染者过程中,耐药性是常见问题。蛋白酶抑制剂是一类HIV可通过突变产生耐药性的药物。本数据集收录了已知对一种或多种药物具有耐药性的蛋白酶序列,可为蛋白酶耐药突变的计算分析提供高质量的研究数据资源。 ### 偏差说明 受数据库采样方式限制,本数据集主要包含来自北美与欧洲的B亚型序列,仅少量收录C、A、D亚型序列。目前未针对各亚型类别进行性能均衡处理,因此在应用于非B亚型序列分析时,建议通过补充额外序列对数据集进行优化。 ## 补充信息 - 数据集整理者:Will Dampier - 引用信息:待补充(TBA)
数据集概述
数据集总结
该数据集源自斯坦福HIV基因型-表型数据库,包含1,733条HIV蛋白酶序列。约半数序列对至少一种抗逆转录病毒疗法(ART)具有抗药性。
数据集结构
数据实例
- 列信息:每列代表HIV蛋白酶蛋白的氨基酸序列。ID字段指示Genbank参考ID,用于未来交叉引用。
- 数据字段:ID, 序列, 折叠, FPV, IDV, NFV, SQV
- 总序列数:1,733
数据集创建
- 数据整理理由:用于训练HIV-BERT-PI模型,预测HIV蛋白酶序列对特定抗逆转录病毒药物的抗药性。
- 初始数据收集与规范化:数据集于2021年12月21日下载并整理。
使用数据时的考虑
- 社会影响:HIV的变异倾向导致药物抗性成为治疗感染者时的常见问题。本数据集提供了一组已知对一种或多种药物具有抗性的蛋白酶序列,可用于进行蛋白酶抗性突变的计算分析。
- 偏见讨论:数据集主要由北美和欧洲的B亚型序列组成,仅有少量C、A和D亚型序列。目前未对这些类别进行性能平衡,建议在使用时考虑加入更多序列以提高非B亚型序列的性能。
附加信息
- 数据集整理者:Will Dampier
- 引用信息:待定