llama3-ultrafeedback-hybrid-v2
收藏资源简介:
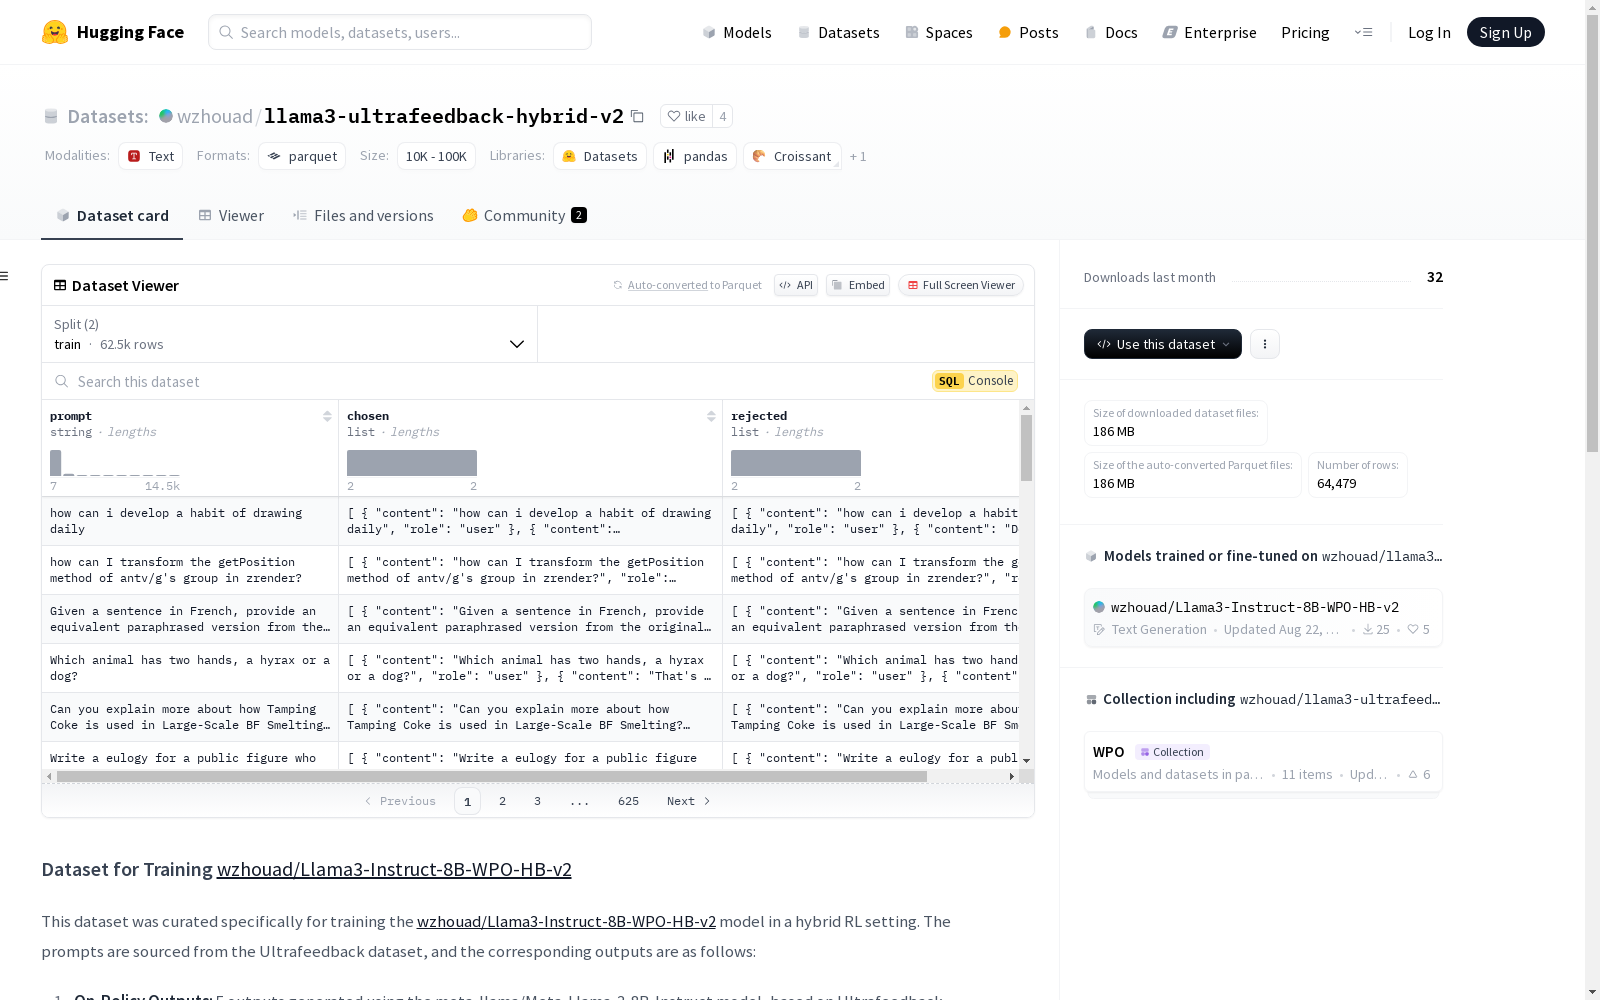
该数据集专为训练[wzhouad/Llama3-Instruct-8B-WPO-HB-v2](https://huggingface.co/wzhouad/Llama3-Instruct-8B-WPO-HB-v2)模型设计,采用混合强化学习设置。数据集包含三个主要特征:'prompt'(字符串类型)、'chosen'(包含'content'和'role'的字符串列表)和'rejected'(包含'content'和'role'的字符串列表)。数据集分为训练集和测试集,分别包含62479和2000个样本。提示来自Ultrafeedback数据集,输出包括由meta-llama/Meta-Llama-3-8B-Instruct模型生成的5个输出和由GPT-4-turbo生成的1个输出。选择输出时,采用特定方法确定'chosen'和'rejected'输出。
数据集概述
数据集信息
- 特征:
prompt: 字符串类型chosen: 列表类型,包含以下字段:content: 字符串类型role: 字符串类型
rejected: 列表类型,包含以下字段:content: 字符串类型role: 字符串类型
- 分割:
train: 包含62479个样本,占用336919685字节test: 包含2000个样本,占用8958822字节
- 下载大小: 185968741字节
- 数据集大小: 345878507字节
配置
- 默认配置:
train: 数据文件路径为data/train-*test: 数据文件路径为data/test-*
数据集用途
- 该数据集专门用于训练wzhouad/Llama3-Instruct-8B-WPO-HB-v2模型,采用混合强化学习(RL)设置。
- 提示语来源于Ultrafeedback数据集,输出包括:
- On-Policy输出: 使用meta-llama/Meta-Llama-3-8B-Instruct模型生成的5个输出。
- GPT-4-turbo输出: 使用GPT-4-turbo模型生成的1个输出。
数据选择方法
- 使用得分最低的响应作为被拒绝的响应。
- 当多个输出得分最高时,选择长度最短的输出。
- 当多个输出得分最低时,选择与被选输出长度差异最小的输出。
许可证
- 该模型遵循Zoom软件许可证,仅允许用于非商业、教育或学术研究目的。
引用
-
WPO:
@article{zhou2024wpo, title={WPO: Enhancing RLHF with Weighted Preference Optimization}, author={Zhou, Wenxuan and Agrawal, Ravi and Zhang, Shujian and Indurthi, Sathish Reddy and Zhao, Sanqiang and Song, Kaiqiang and Xu, Silei and Zhu, Chenguang}, journal={arXiv preprint arXiv:2406.11827}, year={2024} }
-
Ultrafeedback:
@article{cui2023ultrafeedback, title={{UltraFeedback}: Boosting language models with high-quality feedback}, author={Cui, Ganqu and Yuan, Lifan and Ding, Ning and Yao, Guanming and Zhu, Wei and Ni, Yuan and Xie, Guotong and Liu, Zhiyuan and Sun, Maosong}, journal={arXiv preprint arXiv:2310.01377}, year={2023} }