talby/spamassassin
收藏资源简介:
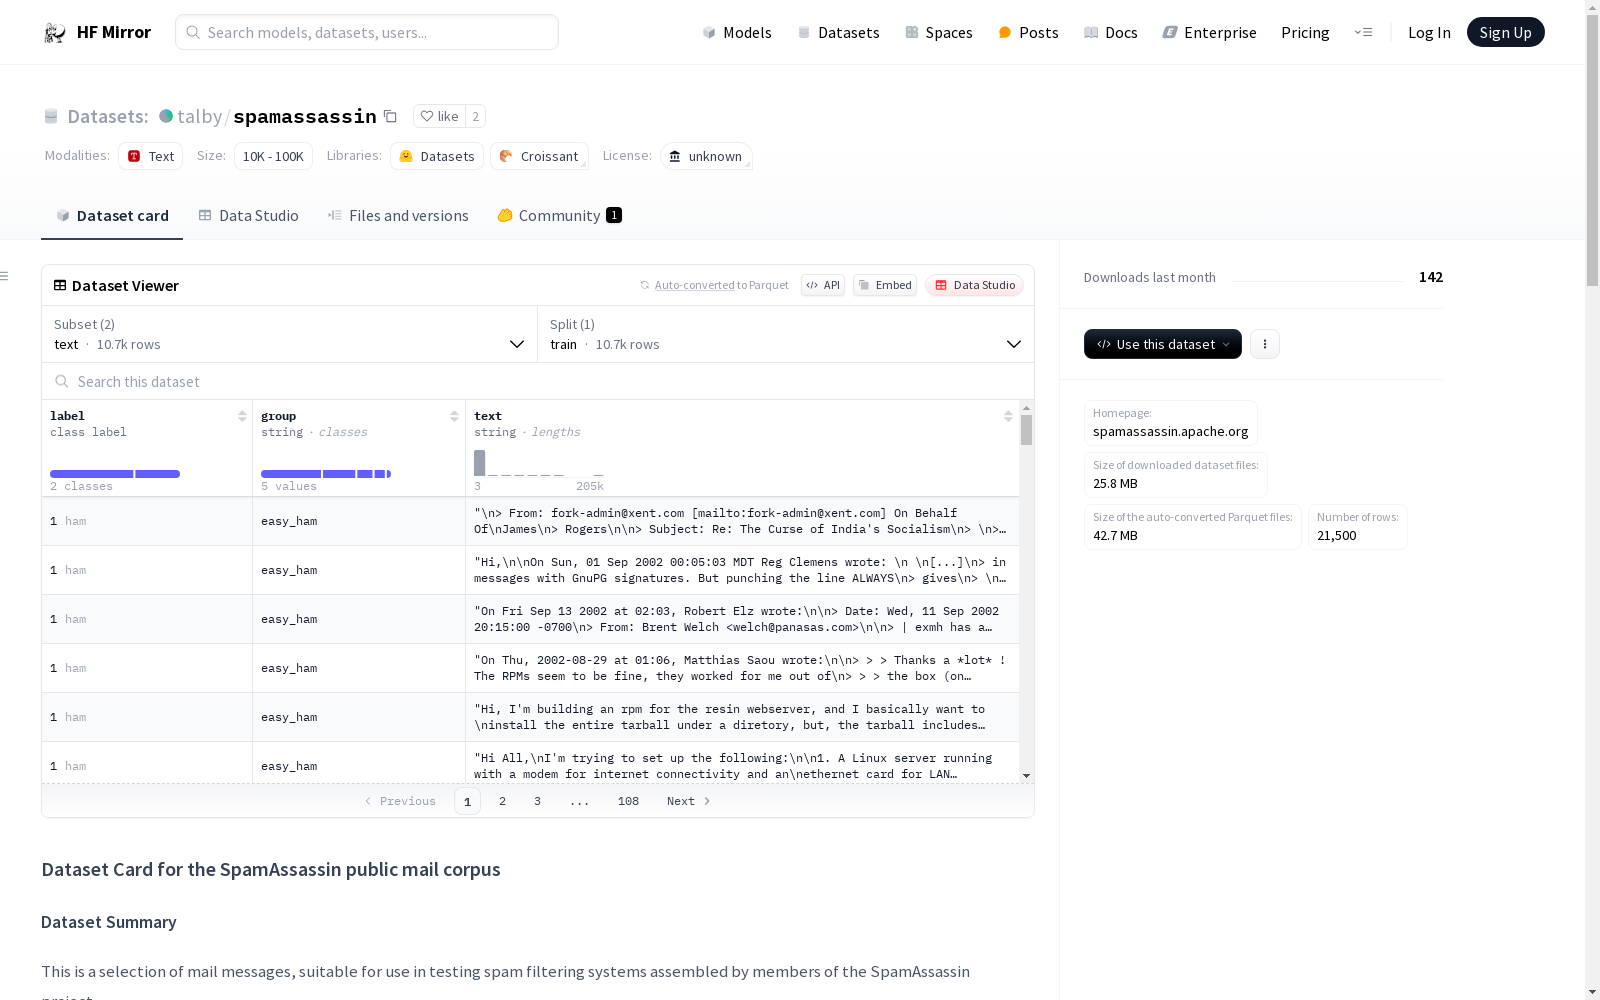
--- license: unknown --- # Dataset Card for the SpamAssassin public mail corpus ## Dataset Description - **Homepage:** https://spamassassin.apache.org/old/publiccorpus/readme.html ### Dataset Summary This is a selection of mail messages, suitable for use in testing spam filtering systems assembled by members of the SpamAssassin project. ### Supported Tasks and Leaderboards [More Information Needed] ### Languages [More Information Needed] ## Dataset Structure ### Data Instances - The `text` config normalizes all character sets to utf8 and dumps the MIME tree as a JSON list of lists. - The `unprocessed` config does not parse messages at all, leaving the full headers and content as binary. ### Data Fields - `label`: `spam` or `ham` - `group`: SpamAssassin has grouped these samples into categories {'hard_ham', 'spam_2', 'spam', 'easy_ham', 'easy_ham_2'} - `text`: normalized text of the message bodies - `raw`: full binary headers and contents of messages ### Data Splits Only a _train_ split has been provided. ## Dataset Creation ### Curation Rationale It is hoped this dataset can help verify that modern NLP tools can solve old NLP problems. ### Source Data #### Initial Data Collection and Normalization [The upstream corpus description](https://spamassassin.apache.org/old/publiccorpus/readme.html) goes into detail on collection methods. The work here to recover text bodies is largely done with [email.parser](https://docs.python.org/3/library/email.parser.html) and [ftfy](https://pypi.org/project/ftfy/). #### Who are the source language producers? [More Information Needed] ### Annotations #### Annotation process [More Information Needed] #### Who are the annotators? [More Information Needed] ### Personal and Sensitive Information [More Information Needed] ## Considerations for Using the Data ### Social Impact of Dataset [More Information Needed] ### Discussion of Biases [More Information Needed] ### Other Known Limitations [More Information Needed] ## Additional Information ### Dataset Curators [More Information Needed] ### Licensing Information [More Information Needed] ### Citation Information [More Information Needed] ### Contributions [More Information Needed]
--- license: 未知 --- # SpamAssassin公开邮件语料库数据集卡片 ## 数据集说明 - **Homepage:** https://spamassassin.apache.org/old/publiccorpus/readme.html ### 数据集概述 本数据集为精选邮件样本集,适用于测试由SpamAssassin项目成员搭建的垃圾邮件过滤系统。 ### 支持任务与排行榜 [需补充更多信息] ### 涉及语言 [需补充更多信息] ## 数据集结构 ### 数据实例 - `text` 配置项会将所有字符集统一规范化为UTF-8,并将MIME树形结构导出为JSON嵌套列表格式。 - `unprocessed` 配置项则不会对邮件进行任何解析,保留完整的邮件头与内容为二进制格式。 ### 数据字段 - `label`:取值为`spam`(垃圾邮件)或`ham`(正常邮件) - `group`:SpamAssassin将样本划分为以下类别:{'hard_ham', 'spam_2', 'spam', 'easy_ham', 'easy_ham_2'} - `text`:邮件正文的规范化文本 - `raw`:邮件完整头信息与内容的二进制数据 ### 数据划分 仅提供了训练集(_train_)划分。 ## 数据集构建 ### 筛选初衷 本数据集旨在助力验证现代自然语言处理(Natural Language Processing,以下简称NLP)工具能否解决经典自然语言处理问题。 ### 源数据 #### 初始数据收集与规范化 [上游语料库说明文档](https://spamassassin.apache.org/old/publiccorpus/readme.html) 详细阐述了数据收集方法。本数据集的正文文本恢复工作主要借助[email.parser](https://docs.python.org/3/library/email.parser.html)与[ftfy](https://pypi.org/project/ftfy/)完成。 #### 源文本创作者身份? [需补充更多信息] ### 标注信息 #### 标注流程 [需补充更多信息] #### 标注人员身份? [需补充更多信息] ### 个人与敏感信息 [需补充更多信息] ## 数据使用注意事项 ### 数据集社会影响 [需补充更多信息] ### 偏见相关讨论 [需补充更多信息] ### 其他已知局限性 [需补充更多信息] ## 补充信息 ### 数据集整理者 [需补充更多信息] ### 许可证信息 [需补充更多信息] ### 引用信息 [需补充更多信息] ### 贡献信息 [需补充更多信息]
数据集概述
数据集名称
SpamAssassin公共邮件语料库
数据集描述
这是一个由SpamAssassin项目成员组装的邮件消息选择,适合用于测试垃圾邮件过滤系统。
数据集结构
数据实例
text配置将所有字符集标准化为utf8,并将MIME树转储为JSON列表的列表。unprocessed配置不解析消息,保留完整的标题和内容为二进制格式。
数据字段
label: 标记为spam或hamgroup: 样本被SpamAssassin归类为{hard_ham, spam_2, spam, easy_ham, easy_ham_2}text: 消息正文的规范化文本raw: 消息的完整二进制标题和内容
数据分割
仅提供了_train_分割。
数据集创建
精选理由
希望此数据集能帮助验证现代NLP工具是否能解决旧的NLP问题。
源数据
初始数据收集和规范化
上游语料库描述详细说明了收集方法。恢复文本正文的工作主要使用email.parser和ftfy完成。
许可证
未知