recwizard/redial
收藏资源简介:
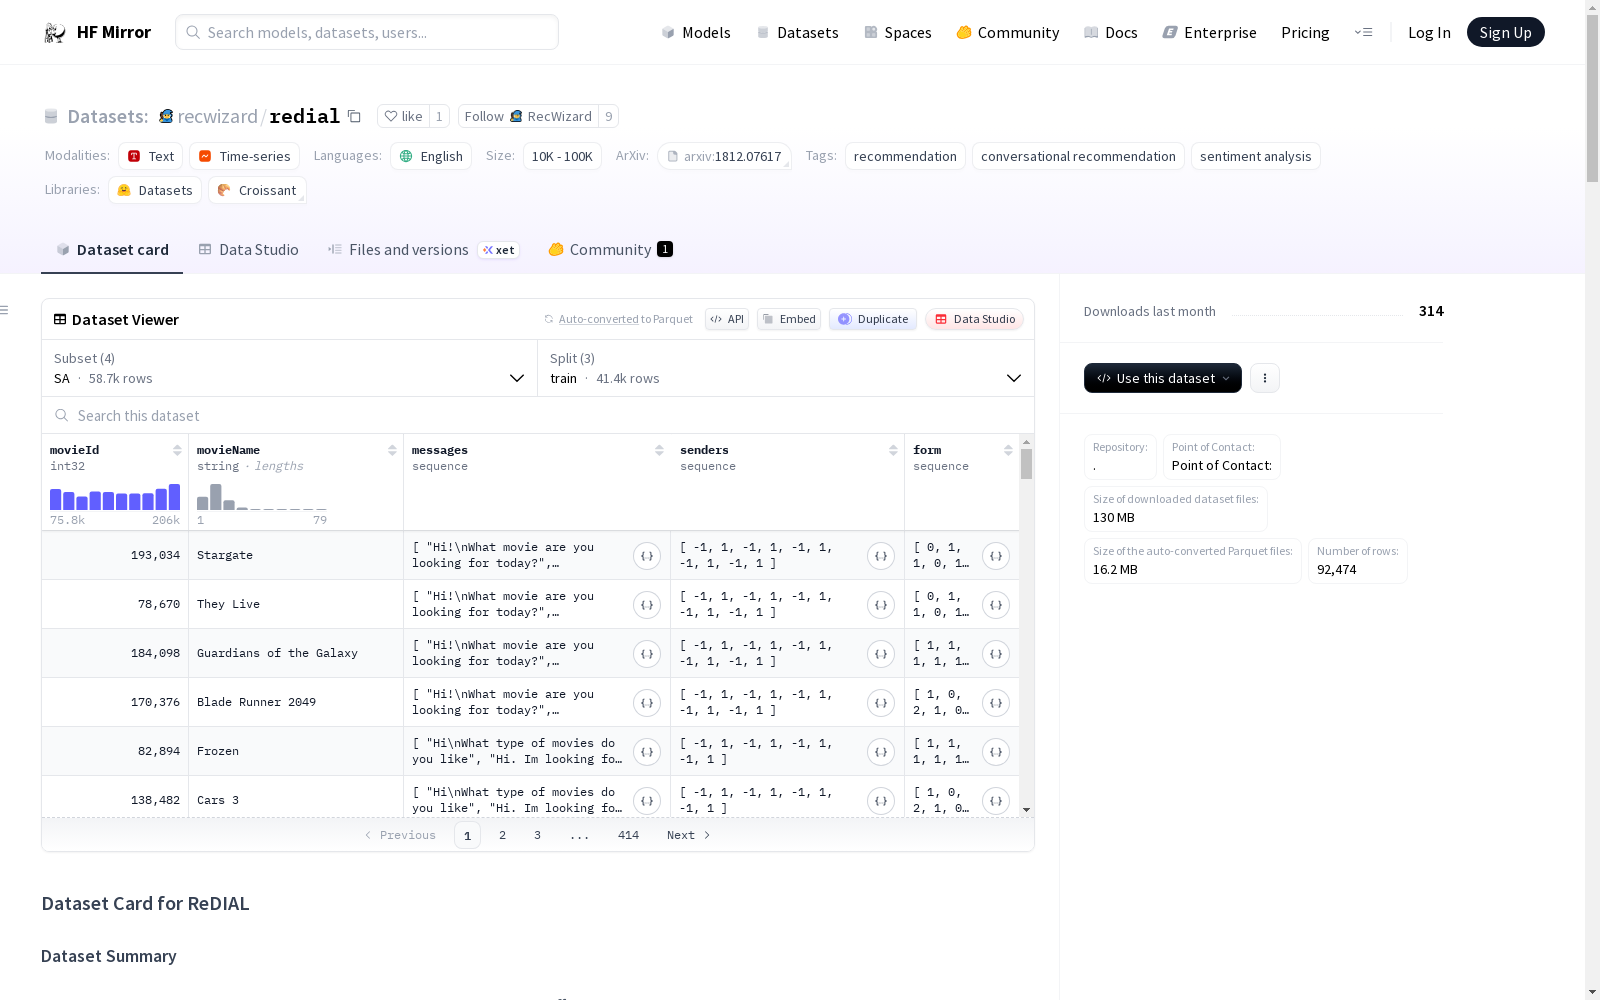
--- dataset_info: - config_name: SA features: - name: movieId dtype: int32 - name: movieName dtype: string - name: messages sequence: string - name: senders sequence: int32 - name: form sequence: int32 splits: - name: train num_bytes: 33174059 num_examples: 41370 - name: validation num_bytes: 8224594 num_examples: 10329 - name: test num_bytes: 5151856 num_examples: 6952 download_size: 32552755 dataset_size: 46550509 - config_name: rec features: - name: movieIds sequence: int32 - name: messages sequence: string - name: senders sequence: int32 splits: - name: train num_bytes: 6064195 num_examples: 8004 - name: validation num_bytes: 1511644 num_examples: 2002 - name: test num_bytes: 937739 num_examples: 1342 download_size: 4812520 dataset_size: 8513578 - config_name: autorec features: - name: movieIds sequence: int32 - name: ratings sequence: float32 splits: - name: train num_bytes: 350688 num_examples: 7840 - name: validation num_bytes: 87496 num_examples: 1966 - name: test num_bytes: 58704 num_examples: 1321 download_size: 32552755 dataset_size: 496888 config_names: - SA - rec - autorec tags: - recommendation - conversational recommendation - sentiment analysis language: - en pretty_name: ReDIAL size_categories: - 10K<n<100K --- # Dataset Card for ReDIAL ## Dataset Description - **Homepage:** - **Repository:** [RecBot](https://github.com/McAuley-Lab/RecBot). - **Paper:** - **Leaderboard:** - **Point of Contact:** ### Dataset Summary This is an adapted version of the [original redial dataset](https://huggingface.co/datasets/re_dial), for supporting different tasks in our project [RecBot](https://github.com/McAuley-Lab/RecBot). The redial dataset provides over 10,000 conversations centered around movie recommendations. It was released in the paper ["Towards Deep Conversational Recommendations"](https://arxiv.org/abs/1812.07617) at NeurIPS 2018. ### Supported Tasks and Leaderboards 1. Sentiment Analysis: Use the SA config for sentiment analysis. 2. Recommendation: Use the autorec config for recommendation task. 3. Conversational recommendation: Use the rec config for conversational recommendation task. ### Languages English ## Dataset Structure ### Data Instances #### SA An example of 'test' looks as follows. ``` { "movieId": 111776, "movieName": "Super Troopers", "messages": [ "Hi I am looking for a movie like @111776", "You should watch @151656", "Is that a great one? I have never seen it. I have seen @192131\nI mean @134643", "Yes @151656 is very funny and so is @94688", "It sounds like I need to check them out", "yes you will enjoy them", "I appreciate your time. I will need to check those out. Are there any others you would recommend?", "yes @101794", "Thank you i will watch that too", "and also @91481", "Thanks for the suggestions.", "you are welcome\nand also @124771", "thanks goodbye" ], "senders": [1, -1, 1, -1, 1, -1, 1, -1, 1, -1, 1, -1, 1], "form": [0, 1, 1, 0, 1, 1] } ``` #### rec An example of 'test' looks as follows. ``` { 'movieIds': [111776, 91481, 151656, 134643, 192131, 124771, 94688, 101794], 'messages': ['Hi I am looking for a movie like @111776', 'You should watch @151656', 'Is that a great one? I have never seen it. I have seen @192131\nI mean @134643', 'Yes @151656 is very funny and so is @94688', 'It sounds like I need to check them out', 'yes you will enjoy them', 'I appreciate your time. I will need to check those out. Are there any others you would recommend?', 'yes @101794', 'Thank you i will watch that too', 'and also @91481', 'Thanks for the suggestions.', 'you are welcome\nand also @124771', 'thanks goodbye'], 'senders': [1, -1, 1, -1, 1, -1, 1, -1, 1, -1, 1, -1, 1] } ``` #### autorec An example of 'test' looks as follows. ``` { "movieIds": [ 111776, 151656, 134643, 192131, 94688 ], "ratings": [ 1.0, 1.0, 1.0, 1.0, 1.0 ] } ``` ### Data Fields #### SA - movieId: the movie's ID in the [MovieLens](https://grouplens.org/datasets/movielens/latest/) dataset. - movieName: the movie's name. - messages: a list of string. The conversation messages related to the movie. Note that one conversation can contain mutiple movies. The conversation messages are repeated for each movie as a sample. - senders: a list of 1 or -1. It has the same length of messages. Each element indicates the message at the same index is from the initiatorWorker (with 1) or the respondentWorkerId (with -1). - form: a list generated by: [init_q[movieId]["suggested"], init_q[movieId]["seen"], init_q[movieId]["liked"], resp_q[movieId]["suggested"], resp_q[movieId]["seen"], resp_q[movieId]["liked"]. init_q is the initiator questions in the conversation. resp_q is the respondent questions in the conversation. #### rec - movieIds: a list of movie ids in a conversation. - messages: a list of string. see config SA for detail. - senders: a list of 1 or -1. see config SA for detail. #### autorec: - movieIds: a list of movie ids in a conversation. - ratings: a list of 0 or 1. It has the same length as movieIds. Each element indicates the inititator's "liked" value for the movie. ## Dataset Creation ### Curation Rationale [More Information Needed] ### Source Data #### Initial Data Collection and Normalization [More Information Needed] #### Who are the source language producers? [More Information Needed] ### Annotations #### Annotation process [More Information Needed] #### Who are the annotators? [More Information Needed] ### Personal and Sensitive Information [More Information Needed] ## Considerations for Using the Data ### Social Impact of Dataset [More Information Needed] ### Discussion of Biases [More Information Needed] ### Other Known Limitations [More Information Needed] ## Additional Information ### Dataset Curators [More Information Needed] ### Licensing Information [More Information Needed] ### Citation Information [More Information Needed] ### Contributions [More Information Needed]
dataset_info: - config_name: SA(情感分析(Sentiment Analysis)) features: - name: movieId dtype: int32 - name: movieName dtype: 字符串 - name: messages sequence: 字符串序列 - name: senders sequence: int32序列 - name: form sequence: int32序列 splits: - name: train num_bytes: 33174059 num_examples: 41370 - name: validation num_bytes: 8224594 num_examples: 10329 - name: test num_bytes: 5151856 num_examples: 6952 download_size: 32552755 dataset_size: 46550509 - config_name: rec(会话推荐(Conversational Recommendation)) features: - name: movieIds sequence: int32序列 - name: messages sequence: 字符串序列 - name: senders sequence: int32序列 splits: - name: train num_bytes: 6064195 num_examples: 8004 - name: validation num_bytes: 1511644 num_examples: 2002 - name: test num_bytes: 937739 num_examples: 1342 download_size: 4812520 dataset_size: 8513578 - config_name: autorec(自动推荐(AutoRec)) features: - name: movieIds sequence: int32序列 - name: ratings sequence: float32序列 splits: - name: train num_bytes: 350688 num_examples: 7840 - name: validation num_bytes: 87496 num_examples: 1966 - name: test num_bytes: 58704 num_examples: 1321 download_size: 32552755 dataset_size: 496888 config_names: - SA - rec - autorec tags: - 推荐(Recommendation) - 会话推荐(Conversational Recommendation) - 情感分析(Sentiment Analysis) language: - en pretty_name: ReDIAL size_categories: - 10K<n<100K # ReDIAL 数据集卡片 ## 数据集描述 - **主页:** 无 - **代码仓库:** [RecBot](https://github.com/McAuley-Lab/RecBot) - **论文:** 无 - **排行榜:** 无 - **联系人:** 无 ### 数据集概览 本数据集是[原始ReDIAL数据集](https://huggingface.co/datasets/re_dial)的适配版本,用于支持我们的项目[RecBot](https://github.com/McAuley-Lab/RecBot)中的各类任务。ReDIAL数据集包含超过10000条以电影推荐为主题的对话,其首次发布于NeurIPS 2018的论文《Towards Deep Conversational Recommendations》(arXiv:1812.07617)。 ### 支持的任务与排行榜 1. **情感分析(Sentiment Analysis):** 使用SA配置完成情感分析任务。 2. **推荐任务:** 使用autorec配置完成传统推荐任务。 3. **会话推荐(Conversational Recommendation):** 使用rec配置完成会话推荐任务。 ### 语言 英语 ## 数据集结构 ### 数据样例 #### SA配置 测试集(test)的一条样例如下: { "movieId": 111776, "movieName": "超级骑警", "messages": [ "嗨,我在找类似@111776的电影", "你可以看看@151656", "这部好看吗?我从没看过,我看过@192131,是说@134643", "没错,@151656非常有趣,@94688也是", "听起来我得去看看了", "是的,你会喜欢的", "谢谢你的推荐,我会去看看的,还有其他推荐吗?", "有的,@101794", "谢谢,我也会看这部", "还有@91481", "感谢这些建议", "不客气,还有@124771", "谢谢,再见" ], "senders": [1, -1, 1, -1, 1, -1, 1, -1, 1, -1, 1, -1, 1], "form": [0, 1, 1, 0, 1, 1] } #### rec配置 测试集的一条样例如下: { 'movieIds': [111776, 91481, 151656, 134643, 192131, 124771, 94688, 101794], 'messages': ['嗨,我在找类似@111776的电影', '你可以看看@151656', '这部好看吗?我从没看过,我看过@192131,是说@134643', '没错,@151656非常有趣,@94688也是', '听起来我得去看看了', '是的,你会喜欢的', '谢谢你的推荐,我会去看看的,还有其他推荐吗?', '有的,@101794', '谢谢,我也会看这部', '还有@91481', '感谢这些建议', '不客气,还有@124771', '谢谢,再见'], 'senders': [1, -1, 1, -1, 1, -1, 1, -1, 1, -1, 1, -1, 1] } #### autorec配置 测试集的一条样例如下: { "movieIds": [ 111776, 151656, 134643, 192131, 94688 ], "ratings": [ 1.0, 1.0, 1.0, 1.0, 1.0 ] } ### 数据字段说明 #### SA配置 - movieId:该电影在[MovieLens](https://grouplens.org/datasets/movielens/latest/)数据集中的唯一标识ID。 - movieName:电影名称。 - messages:字符串列表,存储与该电影相关的对话内容。注意一条对话可包含多部电影,且会以每部电影为样本重复对话内容。 - senders:取值为1或-1的列表,长度与messages一致。每个元素对应同索引位置的消息发送方:1代表对话发起者,-1代表对话应答者。 - form:由`[发起者问题[movieId]["suggested"], 发起者问题[movieId]["seen"], 发起者问题[movieId]["liked"], 应答者问题[movieId]["suggested"], 应答者问题[movieId]["seen"], 应答者问题[movieId]["liked"]]`生成的整数列表。其中`init_q`为对话发起者的问题,`resp_q`为对话应答者的问题。 #### rec配置 - movieIds:单条对话中涉及的所有电影ID列表。 - messages:字符串列表,详情参见SA配置的说明。 - senders:取值为1或-1的列表,详情参见SA配置的说明。 #### autorec配置 - movieIds:单条对话中涉及的所有电影ID列表。 - ratings:取值为0或1的列表,长度与movieIds一致。每个元素代表对话发起者对对应电影的“喜爱”评分。 ## 数据集创建 ### 筛选依据 [需补充更多信息] ### 源数据 #### 初始数据收集与标准化 [需补充更多信息] #### 原始文本生产者是谁? [需补充更多信息] ### 标注 #### 标注流程 [需补充更多信息] #### 标注者是谁? [需补充更多信息] ### 个人与敏感信息 [需补充更多信息] ## 数据使用注意事项 ### 数据集的社会影响 [需补充更多信息] ### 偏差讨论 [需补充更多信息] ### 其他已知限制 [需补充更多信息] ## 附加信息 ### 数据集策展人 [需补充更多信息] ### 许可信息 [需补充更多信息] ### 引用信息 [需补充更多信息] ### 贡献 [需补充更多信息]
数据集概述
数据集基本信息
配置名称
- SA
- rec
- autorec
特征信息
SA
- movieId: int32
- movieName: string
- messages: sequence of string
- senders: sequence of int32
- form: sequence of int32
rec
- movieIds: sequence of int32
- messages: sequence of string
- senders: sequence of int32
autorec
- movieIds: sequence of int32
- ratings: sequence of float32
数据集大小
SA
- 下载大小: 32552755 bytes
- 数据集大小: 46550509 bytes
- 训练集: 41370 examples, 33174059 bytes
- 验证集: 10329 examples, 8224594 bytes
- 测试集: 6952 examples, 5151856 bytes
rec
- 下载大小: 4812520 bytes
- 数据集大小: 8513578 bytes
- 训练集: 8004 examples, 6064195 bytes
- 验证集: 2002 examples, 1511644 bytes
- 测试集: 1342 examples, 937739 bytes
autorec
- 下载大小: 32552755 bytes
- 数据集大小: 496888 bytes
- 训练集: 7840 examples, 350688 bytes
- 验证集: 1966 examples, 87496 bytes
- 测试集: 1321 examples, 58704 bytes
数据集结构
数据实例
SA
- movieId: 电影ID
- movieName: 电影名称
- messages: 对话消息列表
- senders: 消息发送者标识列表
- form: 对话形式列表
rec
- movieIds: 对话中电影ID列表
- messages: 对话消息列表
- senders: 消息发送者标识列表
autorec
- movieIds: 对话中电影ID列表
- ratings: 电影评分列表
数据字段
SA
- movieId: MovieLens数据集中的电影ID
- movieName: 电影名称
- messages: 与电影相关的对话消息
- senders: 消息发送者标识
- form: 对话中的问题形式
rec
- movieIds: 对话中的电影ID列表
- messages: 对话消息
- senders: 消息发送者标识
autorec
- movieIds: 对话中的电影ID列表
- ratings: 电影评分