ultrachat-es-30k-topics
收藏资源简介:
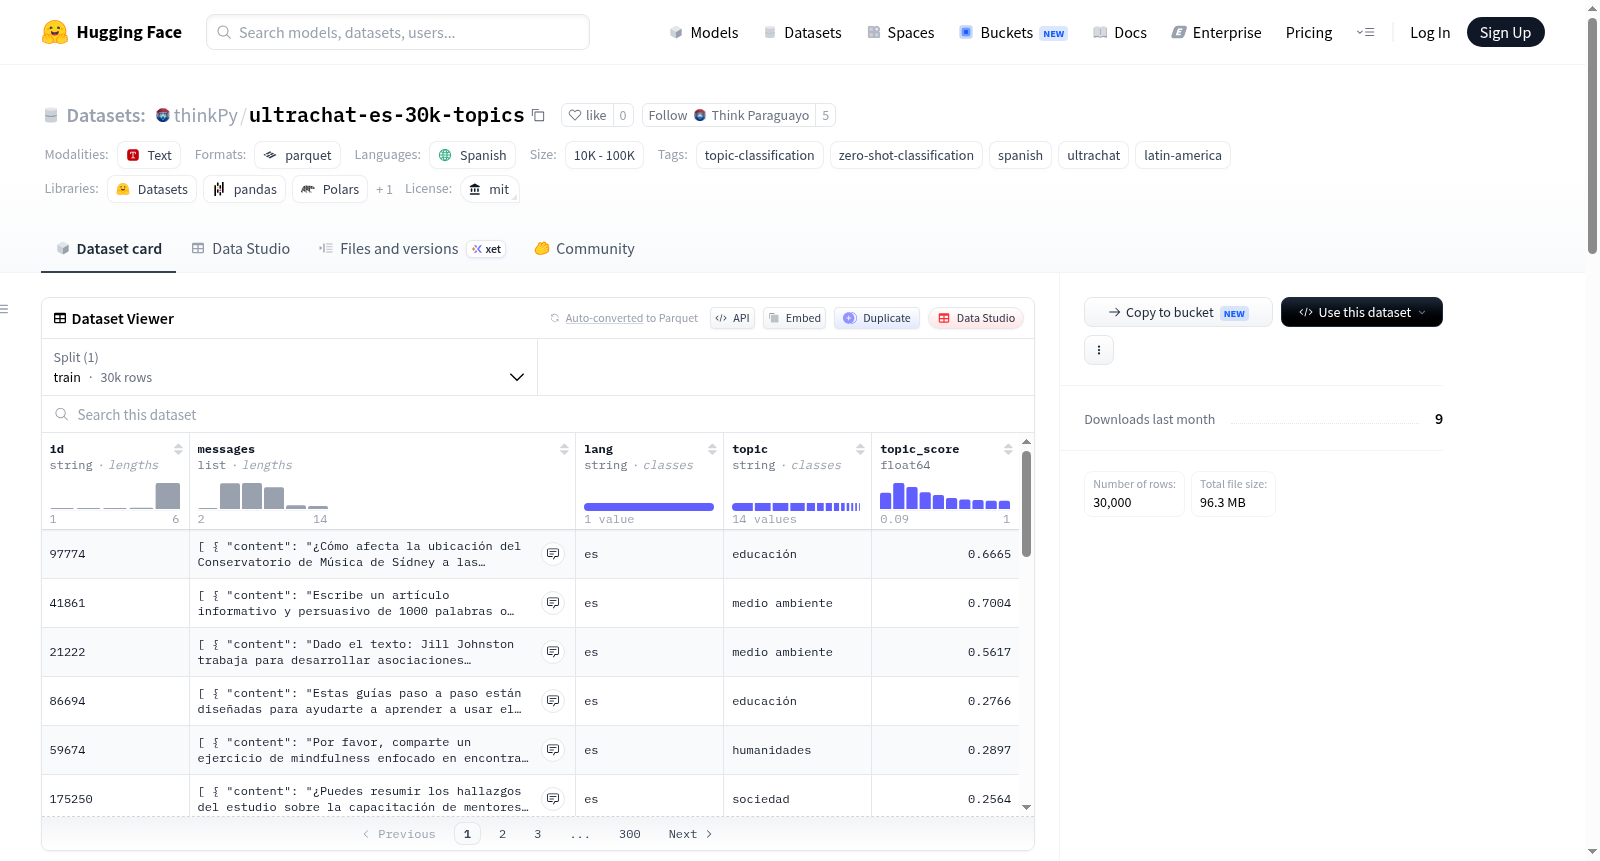
ultrachat-es-30k-topics 是一个包含 30,000 个西班牙语对话的数据集,每个对话都通过零样本分类方法自动标注了主题标签。该数据集源自 latam-gpt/es-ultrachat(后者是 HuggingFaceH4/ultrachat_200k 数据集的机器翻译版本,使用 Llama 3.1 70B 模型翻译成西班牙语)。本数据集从中随机采样了 30,000 个示例,并新增了两个关键字段:`topic`(主题)和 `topic_score`(主题分类置信度得分)。主题分类基于每个对话中用户的第一条消息(截断至 256 个字符),使用 MoritzLaurer/mDeBERTa-v3-base-mnli-xnli 模型进行零样本自然语言推理分类。涵盖的主题共 13 类,包括:技术、数学、科学、人文、历史、文化、政治、经济、健康、教育、社会、环境、娱乐。每个数据样本包含对话 ID、由用户和助手角色组成的消息列表、语言标识(es)、预测的主题以及对应的置信度分数。该数据集适用于西班牙语对话的主题分类模型训练、评估,或作为零样本/少样本学习任务的基准。需要注意的是,主题分类是自动生成的,可能存在错误;且原始内容源自英语,经翻译而来,对拉丁美洲文化的代表性有限。
ultrachat-es-30k-topics is a dataset containing 30,000 Spanish dialogues, each automatically annotated with topic labels using a zero-shot classification method. The dataset is derived from latam-gpt/es-ultrachat (which is a machine-translated version of the HuggingFaceH4/ultrachat_200k dataset, translated into Spanish using the Llama 3.1 70B model). This dataset randomly samples 30,000 examples from it and adds two key fields: `topic` (topic) and `topic_score` (topic classification confidence score). Topic classification is based on the users first message in each dialogue (truncated to 256 characters), using the MoritzLaurer/mDeBERTa-v3-base-mnli-xnli model for zero-shot natural language inference classification. It covers 13 topic categories, including: technology, mathematics, science, humanities, history, culture, politics, economics, health, education, society, environment, and entertainment. Each data sample includes a dialogue ID, a list of messages with user and assistant roles, a language identifier (es), a predicted topic, and the corresponding confidence score. The dataset is suitable for training and evaluating topic classification models for Spanish dialogues, or as a benchmark for zero-shot/few-shot learning tasks. It should be noted that the topic classification is automatically generated and may contain errors; moreover, the original content is from English and has been translated, with limited representation of Latin American culture.
数据集概述
ultrachat-es-30k-topics 是一个包含 30,000 条西班牙语对话的子集,每条对话都经过自动主题分类标注。该数据集来源于 latam-gpt/es-ultrachat,后者是使用 Llama 3.1 70B 对 HuggingFaceH4/ultrachat_200k 进行自动翻译得到的西班牙语版本。
数据规模与划分
- 训练集:30,000 条示例
- 字节数:197,704,577
- 下载大小:96,263,022 字节
- 数据集总大小:197,704,577 字节
数据特征
每条数据包含以下字段:
| 字段名 | 类型 | 说明 |
|---|---|---|
id |
string | 唯一标识符 |
messages |
list[dict] | 对话消息列表,每条消息包含 content(内容)和 role(角色) |
lang |
string | 语言(固定为 es) |
topic |
string | 自动分类的主题标签 |
topic_score |
float64 | 主题分类的置信度分数 |
主题分类
使用 MoritzLaurer/mDeBERTa-v3-base-mnli-xnli 模型,基于用户的第一条消息(截取前 256 个字符)进行零样本主题分类。
可用的 13 个主题
| 主题 | 描述 |
|---|---|
tecnología |
编程、软件、硬件、人工智能 |
matemática |
代数、统计学、微积分 |
ciencia |
物理、化学、生物、研究 |
humanidades |
哲学、语言学、文学 |
historia |
历史事件和历史人物 |
cultura |
传统、艺术、音乐、美食 |
política |
政府、国际关系 |
economía |
金融、市场、创业 |
salud |
医学、健康、营养 |
educación |
教育学、学习、学术 |
sociedad |
人际关系、伦理、日常生活 |
medio ambiente |
生态学、气候变化、自然 |
entretenimiento |
体育、电影、电子游戏、旅行 |
数据来源
原始数据为 latam-gpt/es-ultrachat 的随机样本(随机种子 seed=42),并额外添加了两列主题分类信息。
使用示例
python from datasets import load_dataset
ds = load_dataset("thinkPy/ultrachat-es-30k-topics", split="train")
按主题过滤
ds_cultura = ds.filter(lambda x: x["topic"] == "cultura")
按置信度过滤
ds_alta_confianza = ds.filter(lambda x: x["topic_score"] >= 0.5)
限制与注意事项
- 主题分类为自动完成,在文本模糊或过短的情况下可能存在错误。
- 内容源于英文翻译,对拉丁美洲文化的代表性有限。
- 对于
topic_score较低的示例应谨慎处理。