ncbi-genbank-complete
收藏资源简介:
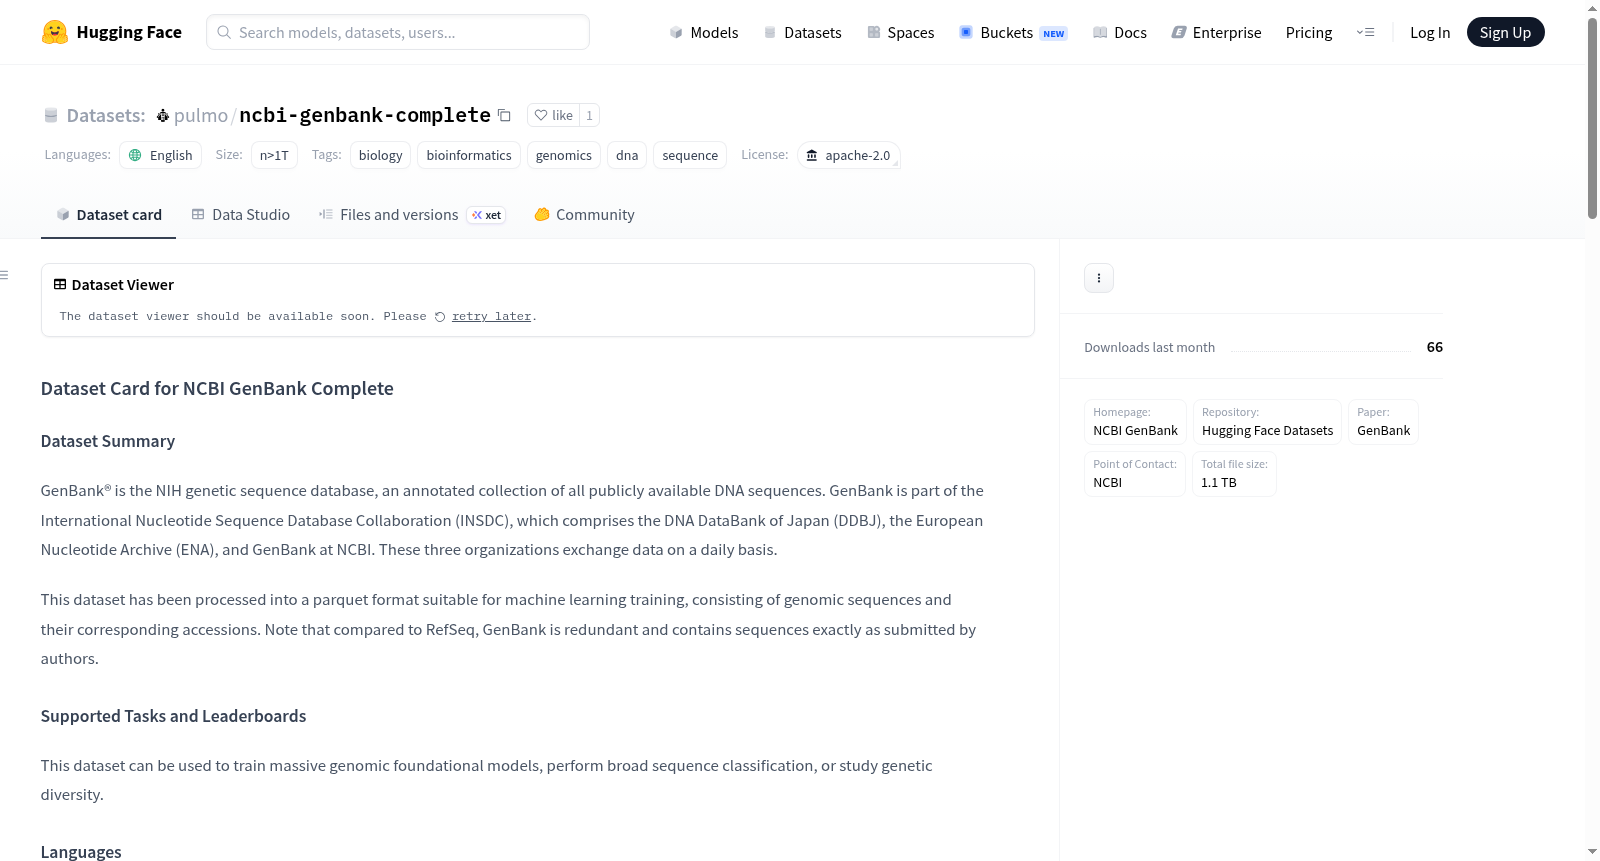
NCBI GenBank Complete 是一个包含所有公开可用DNA序列的注释集合,由美国国立卫生研究院(NIH)维护。该数据集是国际核苷酸序列数据库合作(INSDC)的一部分,与日本的DNA数据库(DDBJ)和欧洲核苷酸档案(ENA)每日交换数据。数据集已处理为适合机器学习训练的parquet格式,包含基因组序列及其对应的访问号。每个数据实例代表一个核苷酸序列,包含accession(NCBI访问标识符)和sequence(原始核苷酸序列字符串)两个字段。数据集适用于训练大规模基因组基础模型、进行广泛的序列分类或研究遗传多样性。需要注意的是,GenBank依赖于科学界的提交,因此研究或测序频繁的物种会显著过多表示。数据集由NCBI维护,数据属于公共领域,可自由使用。
NCBI GenBank Complete is an annotated collection of all publicly available DNA sequences, maintained by the National Institutes of Health (NIH). This dataset is part of the International Nucleotide Sequence Database Collaboration (INSDC) and exchanges data daily with the DNA Data Bank of Japan (DDBJ) and the European Nucleotide Archive (ENA). The dataset has been processed into parquet format suitable for machine learning training, containing genomic sequences and their corresponding accession numbers. Each data instance represents a nucleotide sequence, including two fields: accession (NCBI accession identifier) and sequence (raw nucleotide sequence string). The dataset is suitable for training large-scale genomic foundational models, conducting extensive sequence classification, or studying genetic diversity. It should be noted that GenBank relies on submissions from the scientific community, so species that are frequently researched or sequenced will be significantly overrepresented. The dataset is maintained by NCBI and the data is in the public domain, freely available for use.
数据集卡片:NCBI GenBank Complete
数据集描述
- 主页: NCBI GenBank
- 论文: GenBank
- 联系方式: NCBI
- 许可协议: apache-2.0
- 语言: 英语
- 标签: 生物学、生物信息学、基因组学、DNA、序列
- 数据集大小: 超过1TB
数据集摘要
GenBank® 是美国国立卫生研究院(NIH)的基因序列数据库,是一个收录所有公开可用DNA序列的带注释集合。GenBank 是国际核苷酸序列数据库联盟(INSDC)的一部分,该联盟由日本DNA数据库(DDBJ)、欧洲核苷酸档案库(ENA)和NCBI的GenBank组成。这三个组织每日交换数据。
本数据集已处理为适合机器学习训练的parquet格式,包含基因组序列及其对应的登录号。需要注意的是,与RefSeq相比,GenBank具有冗余性,包含作者提交的原始序列。
支持的任务与排行榜
本数据集可用于:
- 训练大规模基因组基础模型
- 执行广泛的序列分类
- 研究遗传多样性
语言
数据为基因组序列数据(DNA/RNA),表示为核苷酸字符串(A、C、G、T、N)。
数据集结构
数据实例
每个实例代表一段核苷酸序列:
json { "accession": "U49845.1_part1", "sequence": "GATCGATCGATC..." }
数据字段
accession:序列的NCBI访问标识符(例如U49845.1)。大序列可能带有_partXXX后缀以限制数据块大小。sequence:原始核苷酸序列字符串。
数据划分
数据集提供单一的 train 划分,包含所有序列。
数据集创建
策划理由
GenBank 旨在为科学界提供并鼓励访问最新、最全面的DNA序列信息。
源数据
- 初始数据收集与标准化: 序列由全球科学家直接提交给GenBank。
- 源语言生产者: 数据代表来自各种生物体的遗传物质,由全球科学界提交。
使用数据的注意事项
数据集的社会影响
基因组数据集对医学研究、药物发现和生物学理解具有深远影响。GenBank 的庞大规模使得研究前所未有的生物多样性成为可能。
偏倚讨论
GenBank 完全依赖于科学界的提交。因此,被广泛研究或频繁测序的物种在数据集中被显著过度代表。
附加信息
数据集策展人
该数据库由美国国家生物技术信息中心(NCBI)托管和维护。
许可信息
NCBI GenBank 的数据属于公共领域,可免费使用。
机器学习数据集归属
本数据集(GenBank Release 272)由 huggingworld 检索并优化处理。序列数据已使用最新的 pyarrow 标准序列化为parquet格式,专门面向机器学习研究和大规模模型训练。如果您在研究中使用了本处理版本的数据集,请引用或致谢本仓库。
引用信息
bibtex @misc{huggingworld2026ncbigenbank, author = {huggingworld}, title = {NCBI GenBank Complete (Release 271) April 15 2026 - Processed for ML Research}, year = {2026}, publisher = {Hugging Face}, howpublished = {url{https://huggingface.co/datasets/pulmo/ncbi-genbank-complete}} }
bibtex @article{10.1093/nar/gks1195, author = {Benson, Dennis A. and Cavanaugh, Mark and Clark, Karen and Karsch-Mizrachi, Ilene and Lipman, David J. and Ostell, James and Sayers, Eric W.}, title = "{GenBank}", journal = {Nucleic Acids Research}, volume = {41}, number = {D1}, pages = {D36-D42}, year = {2012}, month = {11}, issn = {0305-1048}, doi = {10.1093/nar/gks1195}, url = {https://doi.org/10.1093/nar/gks1195}, eprint = {https://huggingface.co/datasets/pulmo/ncbi-genbank-complete/resolve/main/gks1195.pdf}, }