oasst2-es-3k-topics
收藏资源简介:
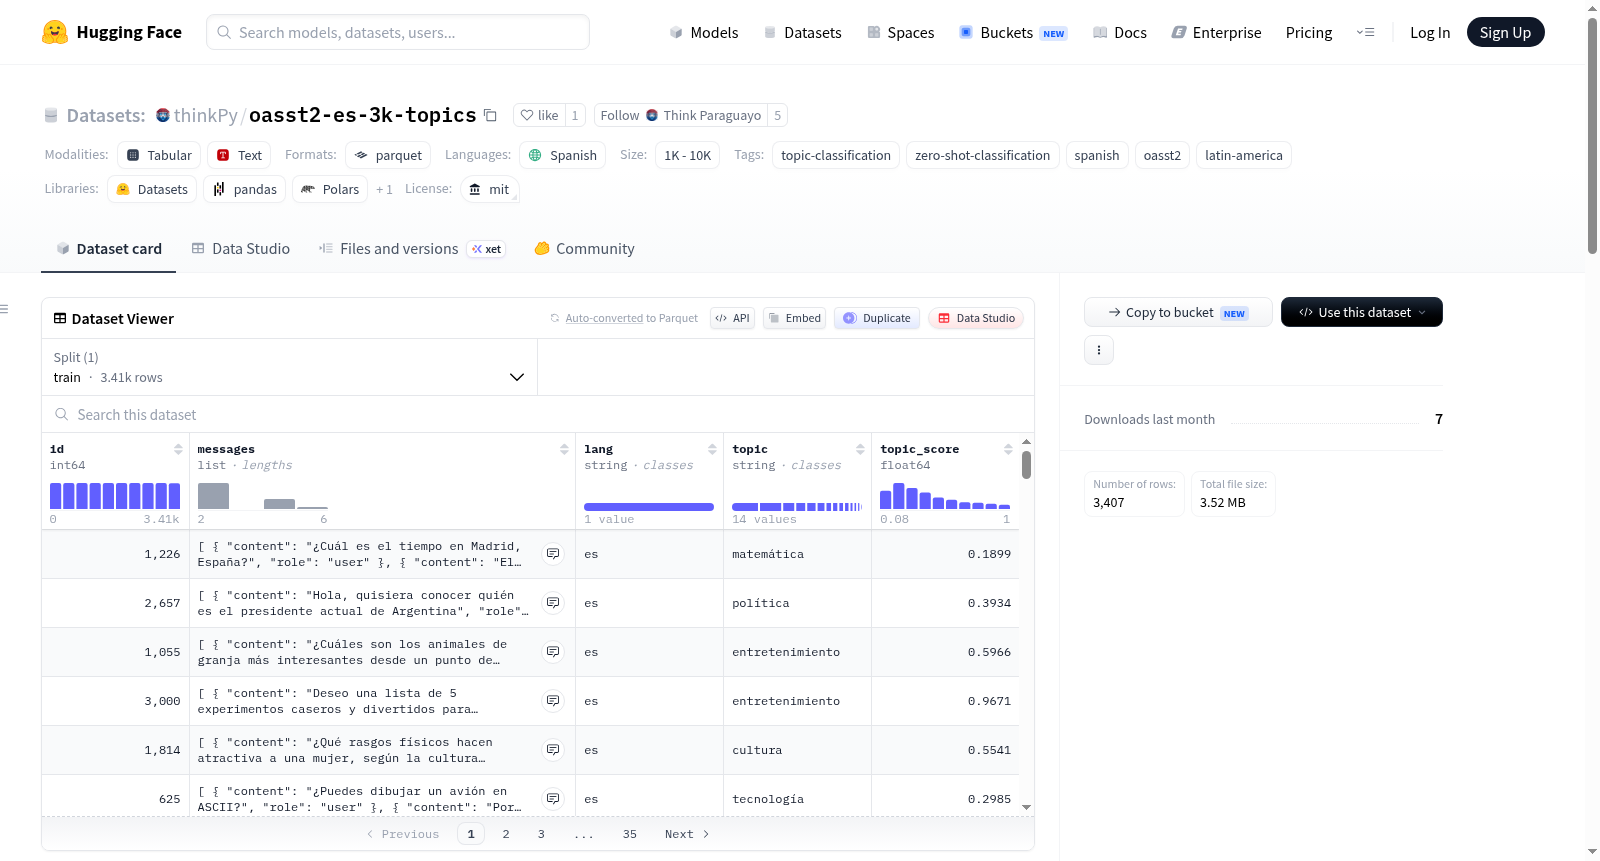
oasst2-short-es-topics 是一个西班牙语短对话数据集,其特点是包含了自动生成的主题分类标签。该数据集源自 thinkPy/oasst2-short-es(一个基于 OpenAssistant/oasst2 的西班牙语短对话数据集),通过对原始数据进行随机抽样(种子为42)并新增两个主题分类字段而构建。主题分类任务是通过零样本分类(自然语言推理)技术完成的,具体使用了 MoritzLaurer/mDeBERTa-v3-base-mnli-xnli 模型对对话中用户的第一条消息(截断至256个字符)进行分析。数据集共定义了14个涵盖广泛领域的主题,包括:技术、数学、科学、人文、历史、文化、政治、经济、健康、教育、社会、环境、娱乐和体育。每个数据样本包含以下字段:唯一标识符(id)、由用户和助手角色消息组成的对话列表(messages)、语言代码(lang,固定为‘es’)、预测的主题标签(topic)以及该预测的置信度分数(topic_score)。数据集规模为3,407个训练样本。该数据集主要适用于西班牙语的主题分类和零样本分类任务的研究与评估。需要注意的是,所有主题标签均为模型自动生成,可能存在错误,对于置信度分数较低的样本应谨慎使用。
oasst2-short-es-topics is a Spanish short dialogue dataset characterized by automatically generated topic classification labels. It originates from thinkPy/oasst2-short-es (a Spanish short dialogue dataset based on OpenAssistant/oasst2), constructed by randomly sampling the original data (with a seed of 42) and adding two topic classification fields. The topic classification task is completed through zero-shot classification (natural language inference) technology, specifically using the MoritzLaurer/mDeBERTa-v3-base-mnli-xnli model to analyze the users first message in the dialogue (truncated to 256 characters). The dataset defines 14 topics covering a wide range of fields, including: technology, mathematics, science, humanities, history, culture, politics, economics, health, education, society, environment, entertainment, and sports. Each data sample includes the following fields: unique identifier (id), a list of dialogues composed of user and assistant role messages (messages), language code (lang, fixed as es), predicted topic label (topic), and the confidence score of that prediction (topic_score). The dataset size is 3,407 training samples. This dataset is primarily suitable for research and evaluation of Spanish topic classification and zero-shot classification tasks. It should be noted that all topic labels are automatically generated by the model and may contain errors; samples with low confidence scores should be used with caution.
数据集概述:oasst2-es-3k-topics
该数据集提供约 3407 条西班牙语短对话,并附带自动标注的主题分类信息。
基本信息
- 语言: 西班牙语 (es)
- 许可证: MIT
- 数据集大小: 1K < n < 10K
- 来源数据集: thinkPy/oasst2-short-es (基于 OpenAssistant/oasst2 的西班牙语短对话版本)
数据特征
每条样本包含以下字段:
id(int64): 样本唯一标识符messages(list): 对话消息列表,包含角色 (role: user/assistant) 和内容 (content: string)lang(string): 语言,固定为 "es"topic(string): 自动分类的主题标签topic_score(float64): 主题分类的置信度分数
数据集划分
- 训练集 (train): 3407 条样本,大小约 6.57 MB
主题分类
使用零样本分类模型 MoritzLaurer/mDeBERTa-v3-base-mnli-xnli 对用户的第一条消息(截断至 256 字符)进行分类。共包含 14 个主题:
| 主题 | 描述 |
|---|---|
| tecnología | 编程、软件、硬件、人工智能 |
| matemática | 代数、统计学、微积分 |
| ciencia | 物理、化学、生物学、研究 |
| humanidades | 哲学、语言学、文学 |
| historia | 历史事件与人物 |
| cultura | 传统、艺术、音乐、美食 |
| política | 政府、国际关系 |
| economía | 金融、市场、创业 |
| salud | 医学、健康、营养 |
| educación | 教育学、学习、学术 |
| sociedad | 人际关系、伦理、日常生活 |
| medio ambiente | 生态、气候变化、自然 |
| entretenimiento | 电影、电子游戏、旅行 |
| deportes | 竞赛、体育项目、体育活动 |
数据样例 (JSON 格式)
json { "id": "0", "messages": [ {"role": "user", "content": "..."}, {"role": "assistant", "content": "..."} ], "lang": "es", "topic": "cultura", "topic_score": 0.7231 }
使用方法(Python)
python from datasets import load_dataset
ds = load_dataset("thinkPy/oasst2-short-es-topics", split="train")
按主题筛选
ds_cultura = ds.filter(lambda x: x["topic"] == "cultura")
按置信度筛选
ds_alta_confianza = ds.filter(lambda x: x["topic_score"] >= 0.5)
注意事项
- 主题分类为自动生成,可能包含错误,尤其是对于内容模糊或过短的文本。
- 置信度较低的样本 (
topic_score较低) 应谨慎使用。