adi-gov-tw/Taiwan-Tongues-ASR-CE-dataset-id
收藏资源简介:
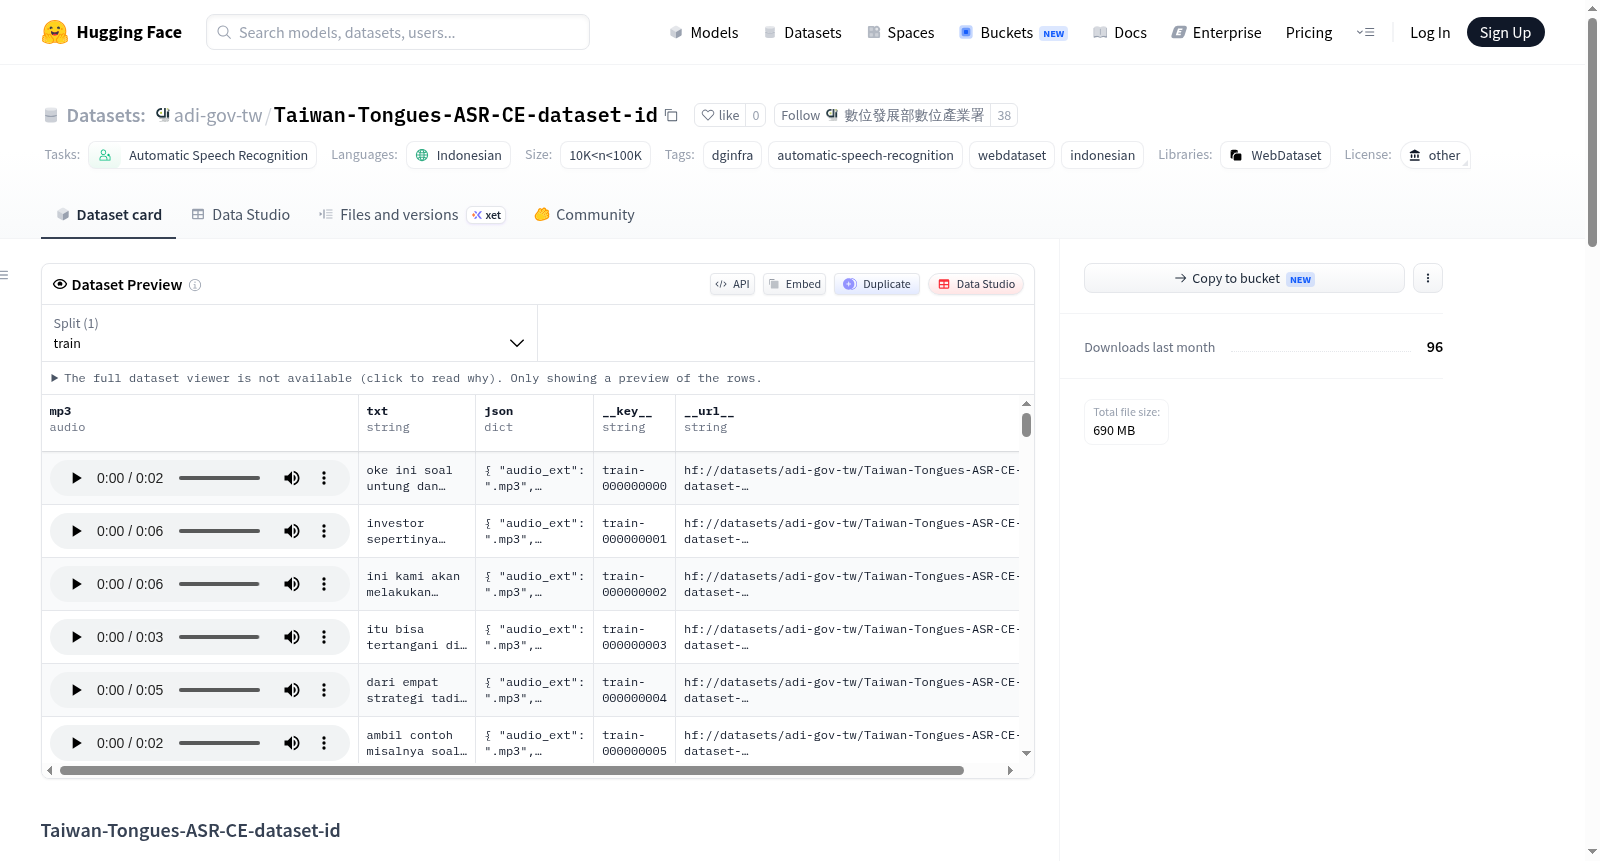
Taiwan-Tongues-ASR-CE-dataset-id 是 Taiwan-Tongues-ASR-CE 项目使用的印尼语训练数据分割。该数据集以 WebDataset tar 分片形式打包,用于自动语音识别训练,包含约20小时的印尼语语音数据,共计17,897条话语。音频文件存储在压缩的tar分片中,无需解压即可通过WebDataset流式读取。数据集包含元数据文件(train.tsv),列包括音频文件名、转录文本、音频扩展名、区域代码、句子标识符、数据分割和时长。
Taiwan-Tongues-ASR-CE-dataset-id is the Indonesian training split used by the Taiwan-Tongues-ASR-CE project. The dataset is packaged as WebDataset tar shards for ASR training, containing approximately 20 hours of Indonesian speech data with 17,897 utterances. Audio files remain inside compressed tar shards and can be streamed without unpacking via WebDataset. It includes a metadata file (train.tsv) with columns for audio file name, transcript, audio extension, locale code, sentence identifier, split, and duration.