tdtu_vietnamese_hsd_final
收藏资源简介:
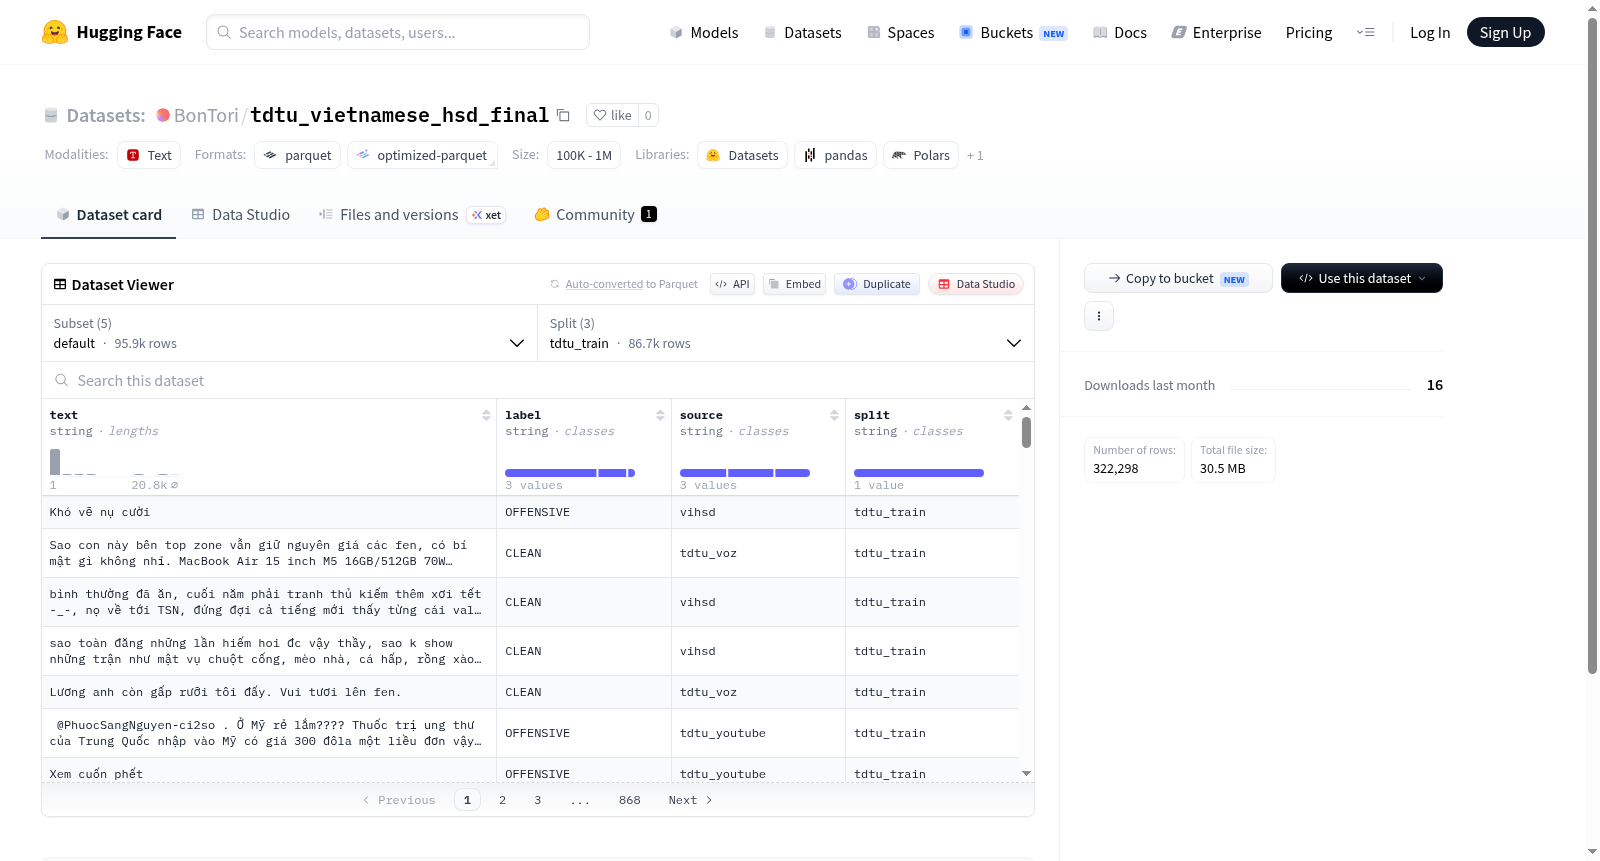
该数据集包含多个配置版本,主要用于文本分类任务。核心数据包含四个字段:text(文本内容)、label(类别标签)、source(数据来源标识)和split(数据划分标识,如训练集)。数据集提供了五种不同的配置:1) default 配置:包含标准的训练集(tdtu_train,86,719条)、开发集(tdtu_dev,2,650条)和测试集(tdtu_test,6,576条);2) baseline_llm 配置:包含一个扩增的训练集(88,279条),可能由基础大语言模型生成或处理;3) eda 配置:包含一个通过EDA(简易数据增强)技术大幅扩增的训练集(135,010条);4) llm_gemma 和 5) llm_qwen 配置:分别包含由Gemma和Qwen大语言模型生成或处理的较小规模训练集(分别为1,572条和1,492条)。不同配置旨在支持对比研究,例如评估不同数据增强方法或不同大语言模型生成数据对文本分类模型性能的影响。
This dataset contains multiple configurations primarily for text classification tasks. The core data includes four fields: text (text content), label (category label), source (data source identifier), and split (data split identifier, e.g., training set). Five configurations are provided: 1) default configuration: includes standard training set (tdtu_train, 86,719 samples), development set (tdtu_dev, 2,650 samples), and test set (tdtu_test, 6,576 samples); 2) baseline_llm configuration: includes an augmented training set (88,279 samples), possibly generated or processed by a base large language model; 3) eda configuration: includes a training set (135,010 samples) significantly augmented via EDA (Easy Data Augmentation) technique; 4) llm_gemma and 5) llm_qwen configurations: include smaller training sets (1,572 and 1,492 samples respectively) generated or processed by the Gemma and Qwen large language models. These configurations are designed to support comparative studies, such as evaluating the impact of different data augmentation methods or data generated by different large language models on text classification model performance.
数据集概述
该数据集是一个用于越南语辱骂性言论检测(Hate Speech Detection)的数据集,包含多个配置(config),每个配置代表不同的数据增强或生成方式。数据集由四个字段组成:文本(text)、标签(label)、来源(source)和划分(split)。
配置详情
数据集共提供五个配置,各配置的划分与规模如下:
| 配置名称 | 划分 | 样本数量 | 数据大小(字节) |
|---|---|---|---|
| default | tdtu_train | 86,719 | 16,524,140 |
| tdtu_dev | 2,650 | 255,536 | |
| tdtu_test | 6,576 | 641,101 | |
| baseline_llm | tdtu_train | 88,279 | 19,274,023 |
| eda | tdtu_train | 135,010 | 27,604,330 |
| llm_gemma | tdtu_train | 1,572 | 367,249 |
| llm_qwen | tdtu_train | 1,492 | 392,200 |
字段说明
所有配置均包含以下四个字段:
- text:文本内容(字符串类型)。
- label:标签(字符串类型,如正常/辱骂等)。
- source:数据来源。
- split:数据划分标识(如训练集/开发集/测试集)。
数据来源
default配置包含完整的三部分划分(训练、开发、测试),是基础数据集。baseline_llm、eda、llm_gemma、llm_qwen配置仅提供训练集,分别代表由大语言模型生成或经过数据增强(EDA)处理后的版本。