457k-prices-build-a-burger
收藏资源简介:
该数据集是一个固定研究快照,包含457,352条经过质量过滤的未聚合价格观测,覆盖10个汉堡配料类别、12个美国邮政编码市场和29个连续日期(2026年7月21日至8月18日)。数据集旨在研究汉堡常见配料在不同美国邮政编码市场和不同日期之间的标价及包装标准化价格差异。每条记录代表一个产品在特定类别、市场、日期的包装数量和标价观测,并包含一个源中立的包装等效价格字段(当数量可解析时)。数据集的字段包括:类别标识符、类别标题、相关URL、地理类型、邮政编码、地理标签、观测日期、产品名称、解析的包装数量、数量单位、数量描述、标价金额、货币代码、标准化价格金额、标准化数量值和标准化数量单位。数据集支持10个汉堡配料类别(如汉堡面包、牛肉饼、美国奶酪、生菜、洋葱、泡菜、蛋黄酱、番茄酱、芥末、泡菜酱),每个类别有特定的比较目标。所有29个日期、12个邮政编码市场和3480个类别×邮政编码×日期单元格均完整覆盖。数据集适用于时间序列分析、零售价格比较、数据可视化以及经济学研究,可用Pandas等工具进行快速分析。该数据集由CostInflation团队发布,采用CC0 1.0通用许可证,允许无限制重用。
This dataset is a fixed research snapshot containing 457,352 quality-filtered, unaggregated price observations covering 10 hamburger ingredient categories, 12 U.S. ZIP code markets, and 29 consecutive dates (July 21 to August 18, 2026). The dataset aims to study the differences in list prices and package-standardized prices of common hamburger ingredients across different U.S. ZIP code markets and dates. Each record represents a products package quantity and list price observation for a specific category, market, and date, and includes a source-neutral package equivalent price field (when quantity is parseable). The dataset fields include: category identifier, category title, related URL, geography type, ZIP code, geography label, observation date, product name, parsed package quantity, quantity unit, quantity description, list price amount, currency code, standardized price amount, standardized quantity value, and standardized quantity unit. The dataset supports 10 hamburger ingredient categories (e.g., hamburger buns, beef patties, American cheese, lettuce, onion, pickles, mayonnaise, ketchup, mustard, relish), each with a specific comparison target. All 29 dates, 12 ZIP code markets, and 3,480 category × ZIP code × date cells are fully covered. The dataset is suitable for time series analysis, retail price comparison, data visualization, and economic research, and can be quickly analyzed using tools like Pandas. It is released by the CostInflation team under the CC0 1.0 Universal License, allowing unrestricted reuse.
数据集概述
该数据集是一个固定研究快照,记录了美国12个ZIP市场中10个汉堡配料类别的457,352条未聚合、经质量筛选的价格观测数据,时间跨度为2026年7月21日至8月18日,共29天。
核心信息
| 项目 | 内容 |
|---|---|
| 名称 | Burger Ingredient Prices Raw Dataset (2026) |
| 发布方 | CostInflation Team |
| 许可协议 | CC0 1.0 Universal |
| 语言 | 英语 |
| 任务类型 | 表格回归 |
| 数据规模 | 457,352行(约457K),文件大小约130.7MB |
| 数据格式 | CSV,货币为美元(USD) |
| 时间范围 | 2026-07-21 至 2026-08-18(29天) |
| 地理覆盖 | 12个美国ZIP市场(邮政编码) |
| 类别数量 | 10个汉堡配料类别 |
| 完整度 | 3,480个 类别×ZIP×日期 单元格全部覆盖,无缺失 |
| 重复行 | 0(已去除精确重复) |
| 更新频率 | 无(固定快照,不再更新) |
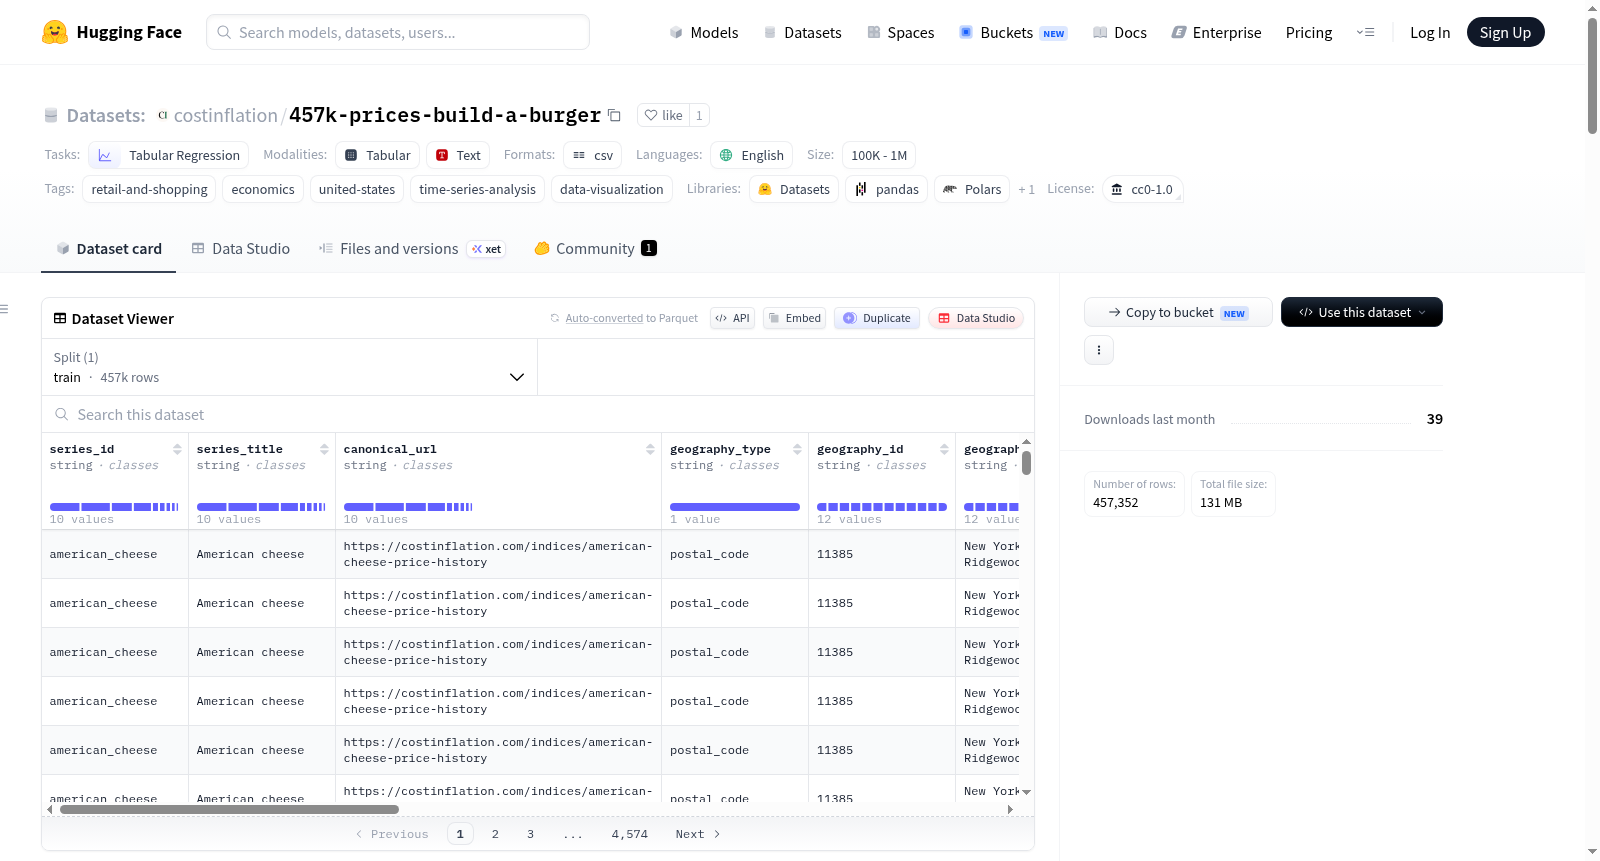
数据字段(16列)
- 标识:
series_id、series_title、canonical_url - 地理:
geography_type(固定为postal_code)、geography_id(5位邮编,需按文本处理)、geography_label - 时间:
observed_date(YYYY-MM-DD格式) - 产品:
product_name(描述性标题,非稳定产品ID) - 数量与价格:
quantity_value、quantity_unit、quantity_name、price_amount、currency_code(固定为USD) - 标准化字段:
normalized_price_amount(可为空)、normalized_quantity_value、normalized_quantity_unit
数据含义与可比价格方法
- 每行表示:一个类别中,某个产品标题在特定ZIP市场、特定日期的包装数量与标价观测,并非销售、订单或库存记录。
- 价格保留:
price_amount为原始标价;若包装数量可解析,normalized_price_amount按类别专属的比较目标缩放,便于跨产品比较。 - 比较目标:如汉堡面包按10个、牛肉饼按1磅、美国奶酪按0.375磅等(详见README中的类别参考表)。
- 注意:仅在同一
series_id内比较标准化值;数量未解析或不兼容的行,normalized_price_amount为空。
类别参考
| 类别键 | 类别名称 | 比较目标 |
|---|---|---|
hamburger_bun |
汉堡面包 | 10个 |
beef_patties |
牛肉饼 | 1磅 |
american_cheese |
美国奶酪 | 0.375磅 |
lettuce |
生菜 | 1个 |
onions |
洋葱 | 1磅 |
pickles |
腌黄瓜 | 16液量盎司 |
mayonnaise |
蛋黄酱 | 30液量盎司 |
ketchup |
番茄酱 | 20盎司 |
mustard |
芥末 | 12盎司 |
pickle_relish |
腌黄瓜酱 | 12液量盎司 |
数据质量与解释
- 质量筛选:已进行类别、安全性和精确重复过滤,不含公式引导的产品标题。
- 可比价格:268,580行(58.73%)有可比价格;188,772行(41.28%)无法比较,标准化价格字段为空。
- 限制:产品标题为描述性文本,非稳定ID;ZIP标签仅代表所选市场,不代表城市、都市区、州或全国估计;不含运费、税费、促销、购买、消费或库存信息。
使用建议
适合用于:
- 跨ZIP市场的类别内可比价格分布比较;
- 29天窗口内的每日中位数和离散度变化分析;
- 基于类别比较目标构建购物篮场景;
- 研究哪些产品标题和包装格式最可能导致可比价格缺失。
快速开始(Pandas示例)
数据集提供Python代码示例,演示如何加载CSV(将geography_id按字符串处理)并计算核心类别的标准化价格中位数。数据文件名为:costinflation-build-a-burger-prices-2026-07-21-to-2026-08-18.csv。