oruk-bench-leaderboard
收藏资源简介:
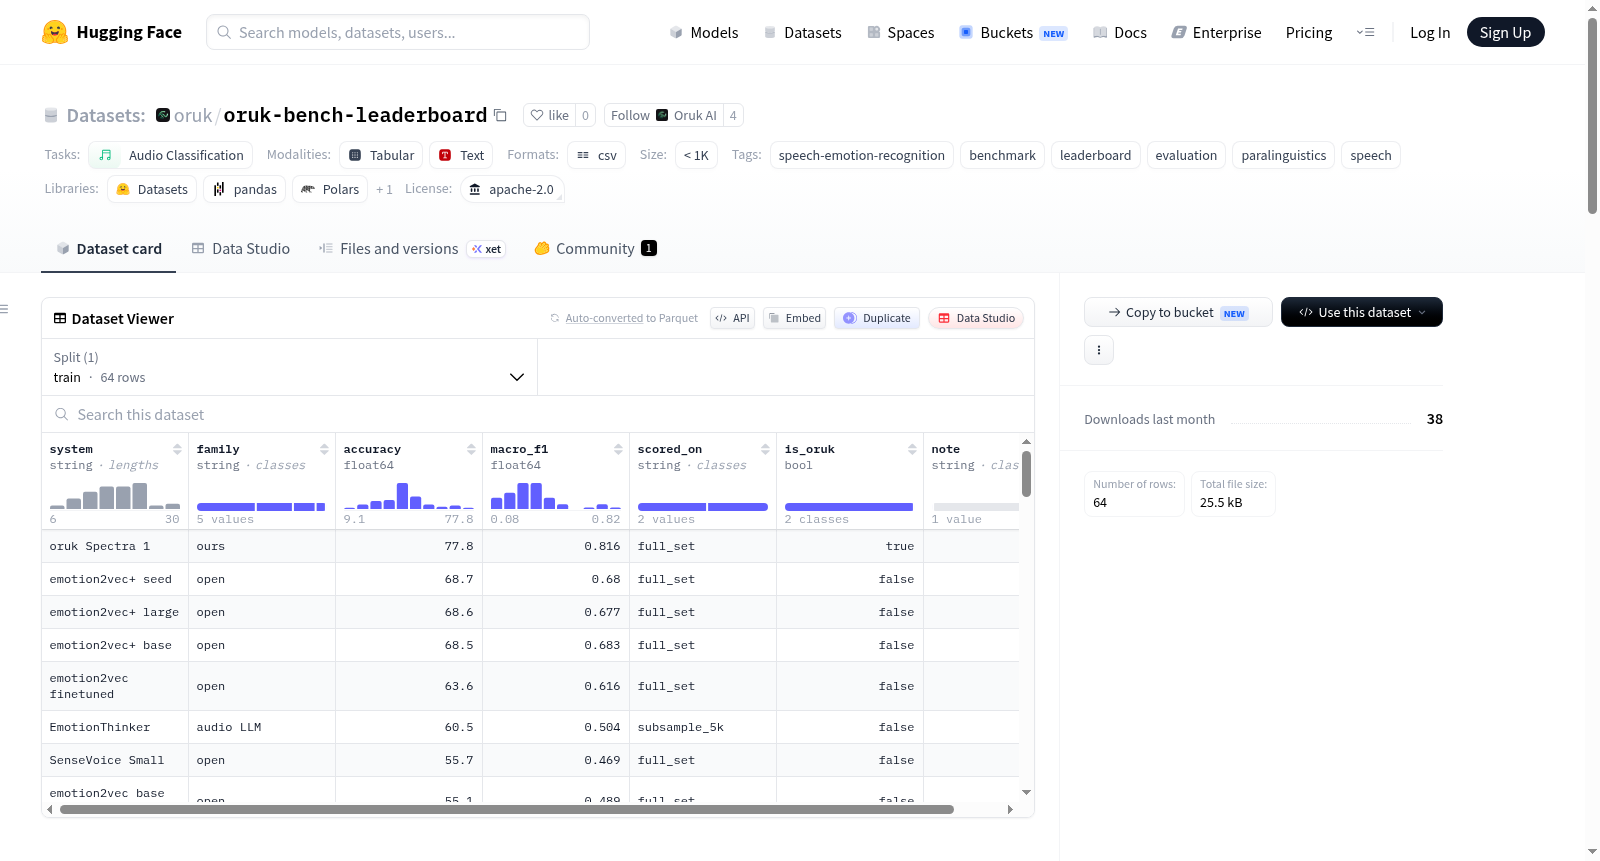
oruk-bench leaderboard 是一个用于语音情感识别(SER)的基准测试排行榜数据集,记录了64个语音情感识别系统在一个多语言留出评估集上的性能结果。该数据集仅包含结果表,不包含音频数据。评估集由64,384个保留片段组成,涵盖约20种语言,包括表演、诱发和自发的语音。情感类别为7类:愤怒、快乐、悲伤、恐惧、厌恶、惊讶和中性,采用单标签分类。音频为16kHz单声道,截断至前16秒。主要评估指标是宏平均F1(macro-F1),同时报告准确率。数据集字段包括:system(系统名称)、family(系统类别,如ours/open/API/audio LLM/text only)、accuracy(准确率,0-100)、macro_f1(宏平均F1,0-1)、scored_on(评分集,full_set或subsample_5k)、is_oruk(是否为oruk模型)、note(快照说明)。系统组成:29个开源模型,18个音频LLM,11个API,5个纯文本基线,1个oruk模型。其中30个系统在完整64,384片段上评分,34个在5,000片段子样本上评分。该数据集适用于比较架构和训练方法、追踪跨语料多语言情感识别进展、审计能力声明以及研究失败模式。需注意:oruk Spectra 1模型是分布内训练,其他系统为零样本跨语料评估,因此性能差距不可直接比较;full_set和subsample_5k的评分结果不可互换。该数据集不得用于开发、营销或验证在职场或教育环境中推断自然人情绪的系统。
The oruk-bench leaderboard is a benchmark dataset for Speech Emotion Recognition (SER), recording the performance results of 64 SER systems on a multilingual held-out evaluation set. The dataset contains only result tables, not audio data. The evaluation set consists of 64,384 held-out segments spanning approximately 20 languages, including acted, elicited, and spontaneous speech. Seven emotion categories are used: anger, happiness, sadness, fear, disgust, surprise, and neutral, with single-label classification. Audio is 16kHz mono, truncated to the first 16 seconds. The primary evaluation metric is macro-averaged F1 (macro-F1), with accuracy also reported. Dataset fields include: system (system name), family (system category, e.g., ours/open/API/audio LLM/text only), accuracy (0-100), macro_f1 (0-1), scored_on (evaluation set: full_set or subsample_5k), is_oruk (whether the model is an oruk model), and note (snapshot description). System composition: 29 open-source models, 18 audio LLMs, 11 APIs, 5 text-only baselines, and 1 oruk model. Among them, 30 systems are scored on the full 64,384 segments, and 34 on a 5,000-segment subsample. The dataset is suitable for comparing architectures and training methods, tracking progress in cross-corpora multilingual SER, auditing capability claims, and studying failure modes. Note: The oruk Spectra 1 model is trained in-distribution, while other systems are evaluated zero-shot cross-corpora, so performance gaps are not directly comparable; results on full_set and subsample_5k are not interchangeable. This dataset must not be used for developing, marketing, or validating systems that infer natural human emotions in workplace or educational settings.
oruk-bench 排行榜数据集
数据集概览
oruk-bench leaderboard 是一个语音情感识别(Speech Emotion Recognition, SER)系统的评测结果汇总数据集。该数据集包含 64 个语音情感识别系统 在单一留出多语言评测协议上的表现结果,涵盖开源检查点、商业封闭 API、音频大语言模型(LLM)及纯文本基线系统。
注意:本数据集仅包含结果表格,不包含音频数据本身。评测音频来自多个许可不同的情感语音语料库,不可再分发。
评测设置
- 评测规模:64,384 条留出音频片段,覆盖约 20 种语言,包含表演型、诱发型和自发性语音
- 分类任务:7 类情感(愤怒、快乐、悲伤、恐惧、厌恶、惊讶、中性),单标签分类
- 音频规格:16 kHz 单声道,截取前 16 秒
- 主要指标:宏平均 F1(macro-F1),同时报告准确率(accuracy)
- 系统构成:29 个开源模型、18 个音频 LLM、11 个 API、5 个纯文本基线、1 个 oruk 自研模型;其中 30 个系统在完整集上评测,34 个在子样本上评测
数据字段说明
| 字段 | 含义 |
|---|---|
system |
被评测的模型或产品名称 |
family |
系统类别:ours、open、API、audio LLM 或 text only |
accuracy |
准确率百分比(0–100) |
macro_f1 |
宏平均 F1 分数(0–1),主要评测指标 |
scored_on |
评测范围:full_set(全部 64,384 条)或 subsample_5k(5,000 条子样本) |
is_oruk |
是否为 oruk 自研模型 |
note |
快照局限性说明,需结合时间背景理解 |
关键结果与注意事项
评测结果
- 宏 F1 分布极广:最高 0.816,最低 0.079,大量知名系统得分低于 0.40
- 领先系统:oruk Spectra 1 以 77.8% 准确率和 0.816 宏 F1 领先
- 最强开源基线:emotion2vec+ 系列,准确率 68.7%,宏 F1 0.683
- 压缩模型表现:HuBERT-large SUPERB 为 40.9%/0.249,DistilHuBERT SUPERB 为 29.5%/0.186,表明蒸馏模型在此任务中表现不佳
重要局限
- 分布内训练偏差:oruk Spectra 1 在评测分布内训练,而其他所有系统均为跨语料库零样本评测,两者差距不可直接对比
- 评测集不可互换:
full_set与subsample_5k的结果并行记录,不可混用;开放性系统在子样本上重新评分差异小于 2 个百分点
使用限制
- 适用用途:比较不同架构和训练方案,追踪跨语料库多语言情感识别进展,核验能力声明,研究失败模式
- 标签性质:标注为人类对声音表现的感知层面注释,高分仅代表与人类评分者感知一致,不代表能判定真实情绪
- 禁止用途:根据欧盟《人工智能法案》第 5(1)(f) 条(2025年2月2日起生效),该基准不得用于在工作场所或教育环境中开发、营销或验证推断自然人情绪的系统
引用与资源
- 引用格式(BibTeX):见数据集原始文档
- 相关链接:
- 交互式排行榜:https://oruk.ai/benchmarks
- 方法论说明:https://oruk.ai/benchmarks/methodology
- 代码与基准卡:https://github.com/Oruk-AI/oruk-bench
- 体验最高分模型:https://oruk.ai/try