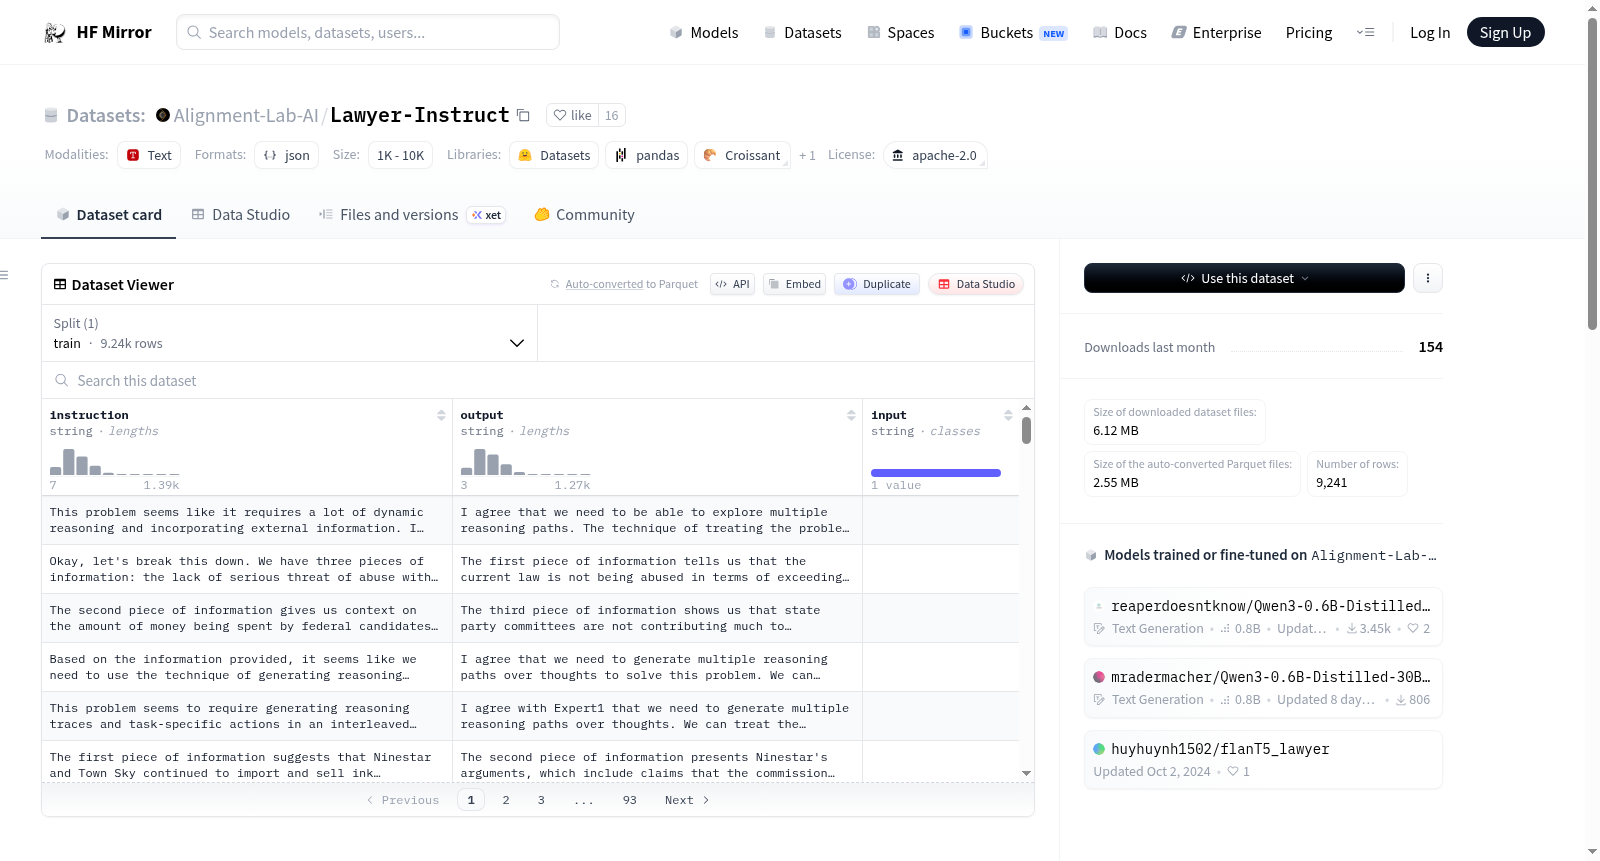
Alignment-Lab-AI/Lawyer-Instruct
收藏资源简介:
--- license: apache-2.0 --- # Dataset Card for "Lawyer-Instruct" ## Table of Contents - [Dataset Description](#dataset-description) - [Dataset Summary](#dataset-summary) - [Supported Tasks and Leaderboards](#supported-tasks-and-leaderboards) - [Languages](#languages) - [Dataset Structure](#dataset-structure) - [Data Instances](#data-instances) - [Data Fields](#data-fields) - [Data Splits](#data-splits) ## Dataset Description ### Dataset Summary Lawyer-Instruct is a conversational dataset primarily in English, reformatted from the original LawyerChat dataset. It contains legal dialogue scenarios reshaped into an instruction, input, and expected output format. This reshaped dataset is ideal for supervised dialogue model training. Dataset generated in part by dang/futures ### Supported Tasks and Leaderboards - `dialogue-modeling`: The dataset can be used to train a model for dialogue understanding and response generation based on given instruction. Performance can be evaluated based on dialogue understanding and the quality of the generated responses. - There is no official leaderboard associated with this dataset at this time. ### Languages The text in the dataset is in English. ## Dataset Structure ### Data Instances An instance in the Lawyer-Instruct dataset represents a dialogue instruction and its corresponding output. Example: ```json { "instruction": "What are the possible legal consequences of not paying taxes?", "input": "", "output": "There can be several legal consequences, ranging from fines to imprisonment..." } ``` ### Data Fields - `instruction`: a string representing the client's question or statement in the dialogue, serving as the input for dialogue model training. - `input`: - `output`: a string representing the legal professional's response. ### Data Splits This dataset does not have a standard split. Users should carefully consider how they wish to split the data for training, validation, and testing purposes.
--- license: apache-2.0 --- # "律师指令(Lawyer-Instruct)"数据集卡片 ## 目录 - [数据集描述](#dataset-description) - [数据集概况](#dataset-summary) - [支持的任务与评测基准](#supported-tasks-and-leaderboards) - [语言](#languages) - [数据集结构](#dataset-structure) - [数据实例](#data-instances) - [数据字段](#data-fields) - [数据划分](#data-splits) ## 数据集描述 ### 数据集概况 律师指令(Lawyer-Instruct)是一个主要以英语呈现的对话型数据集,其源自原始LawyerChat数据集并经重新格式化处理。该数据集将法律对话场景重构为指令、输入与预期输出的标准格式,十分适用于监督式对话模型的训练。本数据集部分内容由dang/futures生成。 ### 支持的任务与评测基准 - `对话建模(dialogue-modeling)`:该数据集可用于训练基于给定指令的对话理解与响应生成模型,模型性能可通过对话理解能力与生成响应的质量进行评估。 - 目前本数据集暂无官方评测基准。 ### 语言 数据集中的文本均为英语。 ## 数据集结构 ### 数据实例 律师指令(Lawyer-Instruct)数据集中的每个实例代表一条对话指令及其对应的输出内容。示例如下: json { "instruction": "未缴纳税款可能面临哪些法律后果?", "input": "", "output": "可能存在多种法律后果,范围从罚款到监禁不等……" } ### 数据字段 - `instruction`:字符串类型,表示对话中客户的问题或陈述,作为对话模型训练的输入内容。 - `input`: - `output`:字符串类型,表示法律专业人士的回复内容。 ### 数据划分 本数据集暂无标准划分方案,用户需自行规划如何将数据划分为训练集、验证集与测试集。
数据集概述:Lawyer-Instruct
数据集描述
数据集总结
- 名称: Lawyer-Instruct
- 语言: 英语
- 内容: 包含法律对话场景,重塑为指令、输入和预期输出格式,适合监督式对话模型训练。
- 来源: 由LawyerChat数据集重塑而来。
支持的任务和排行榜
- 任务: 对话建模
- 用途: 用于训练模型理解对话并生成基于给定指令的响应。
- 评估: 根据对话理解和生成响应的质量进行评估。
- 排行榜: 目前无官方排行榜。
语言
- 主要语言: 英语
数据集结构
数据实例
- 实例结构: 每个实例包含一个对话指令及其对应的输出。
- 示例: json { "instruction": "What are the possible legal consequences of not paying taxes?", "input": "", "output": "There can be several legal consequences, ranging from fines to imprisonment..." }
数据字段
- instruction: 字符串,代表对话中的客户问题或陈述,作为对话模型训练的输入。
- input: (未详细说明)
- output: 字符串,代表法律专业人士的回应。
数据分割
- 分割方式: 数据集未提供标准分割,用户需自行考虑如何分割数据以用于训练、验证和测试。