ekacare/indian_protocols_based_clinical_QnA
收藏资源简介:
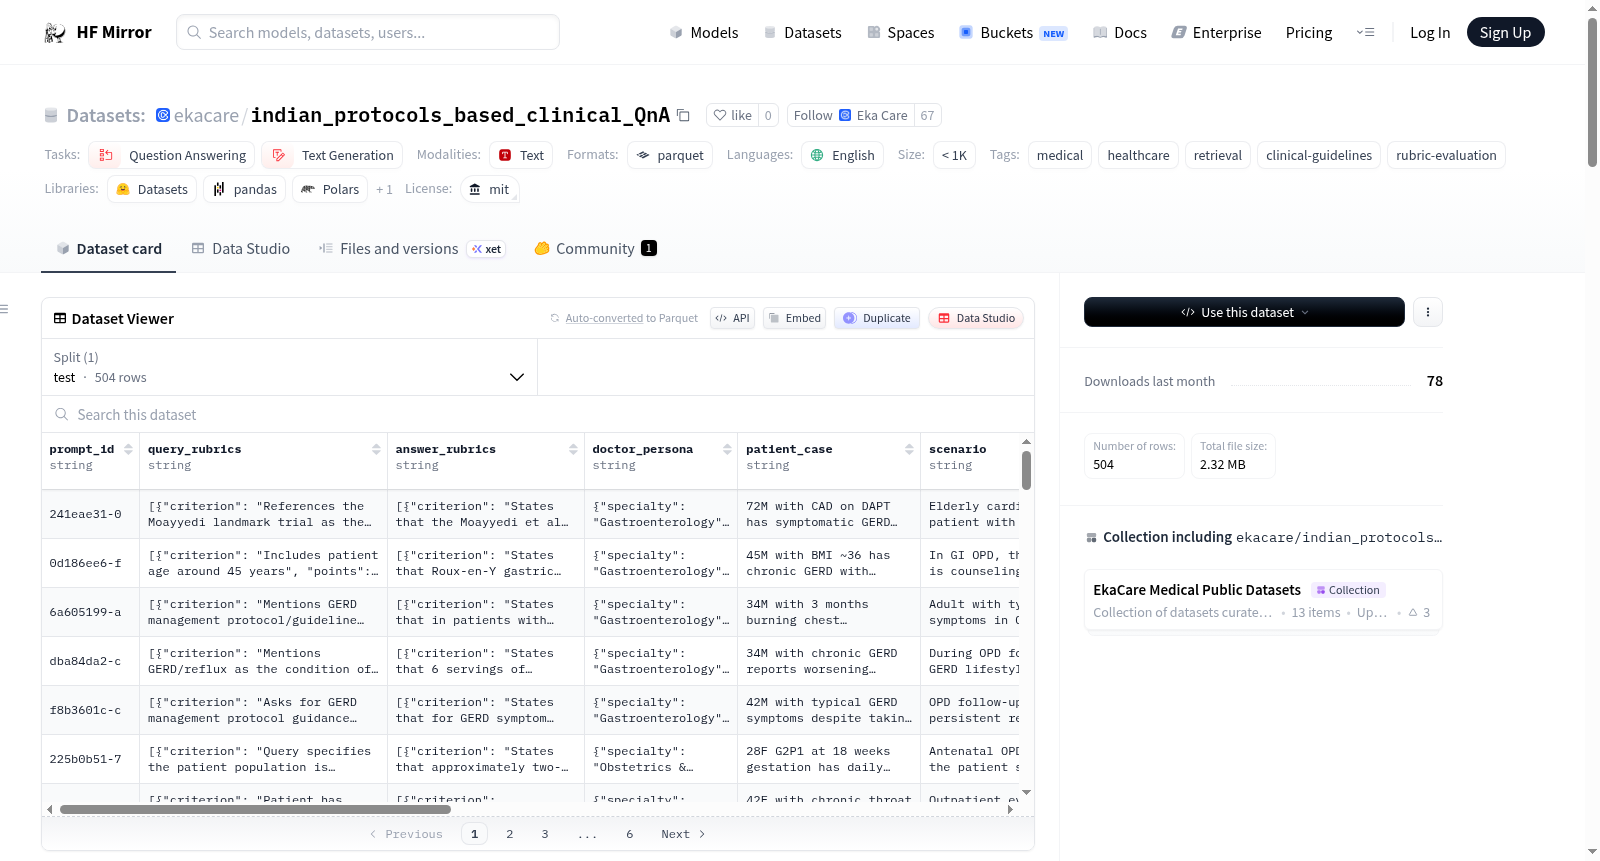
该数据集是一个基于印度和国际临床指南文档构建的评估数据集,用于测试临床助手在基于协议的问答中的表现。数据集包含504个对话提示,每个提示包括评估检索系统是否正确解释医生查询的查询评分标准,以及评估临床答案准确性、完整性和安全性的答案评分标准。数据集旨在突出特定失败模式,如指南基础、查询解释、完整性与简洁性、安全回归和隐式记忆盲点。数据集结构包括多个列,如prompt_id、query_rubrics、answer_rubrics等,详细描述了每个提示的属性。数据集支持通过KARMA评估框架或直接加载使用。
A rubric-graded evaluation dataset built from clinical guideline documents (Indian and international). Each sample is a realistic doctor-side query against a known protocol, paired with rubrics that grade (a) whether the system retrieved/identified the correct guideline content and (b) whether the final answer is clinically complete and safe. The dataset is designed to stress-test clinical assistants on protocol-grounded question answering and surface specific failure modes such as guideline grounding, query interpretation under realistic noise, completeness vs. brevity, safety regressions, and implicit-memory blind spots. It contains 504 conversation prompts derived from clinical scenarios across Indian and international medical guidelines, with each prompt including query and answer rubrics for evaluation. The dataset is structured with various columns detailing each prompts attributes, such as prompt_id, query_rubrics, answer_rubrics, and more. It supports usage with the KARMA Evaluation Framework and direct loading via the HuggingFace datasets library.