PleIAs/Telco-Common-Corpus
收藏资源简介:
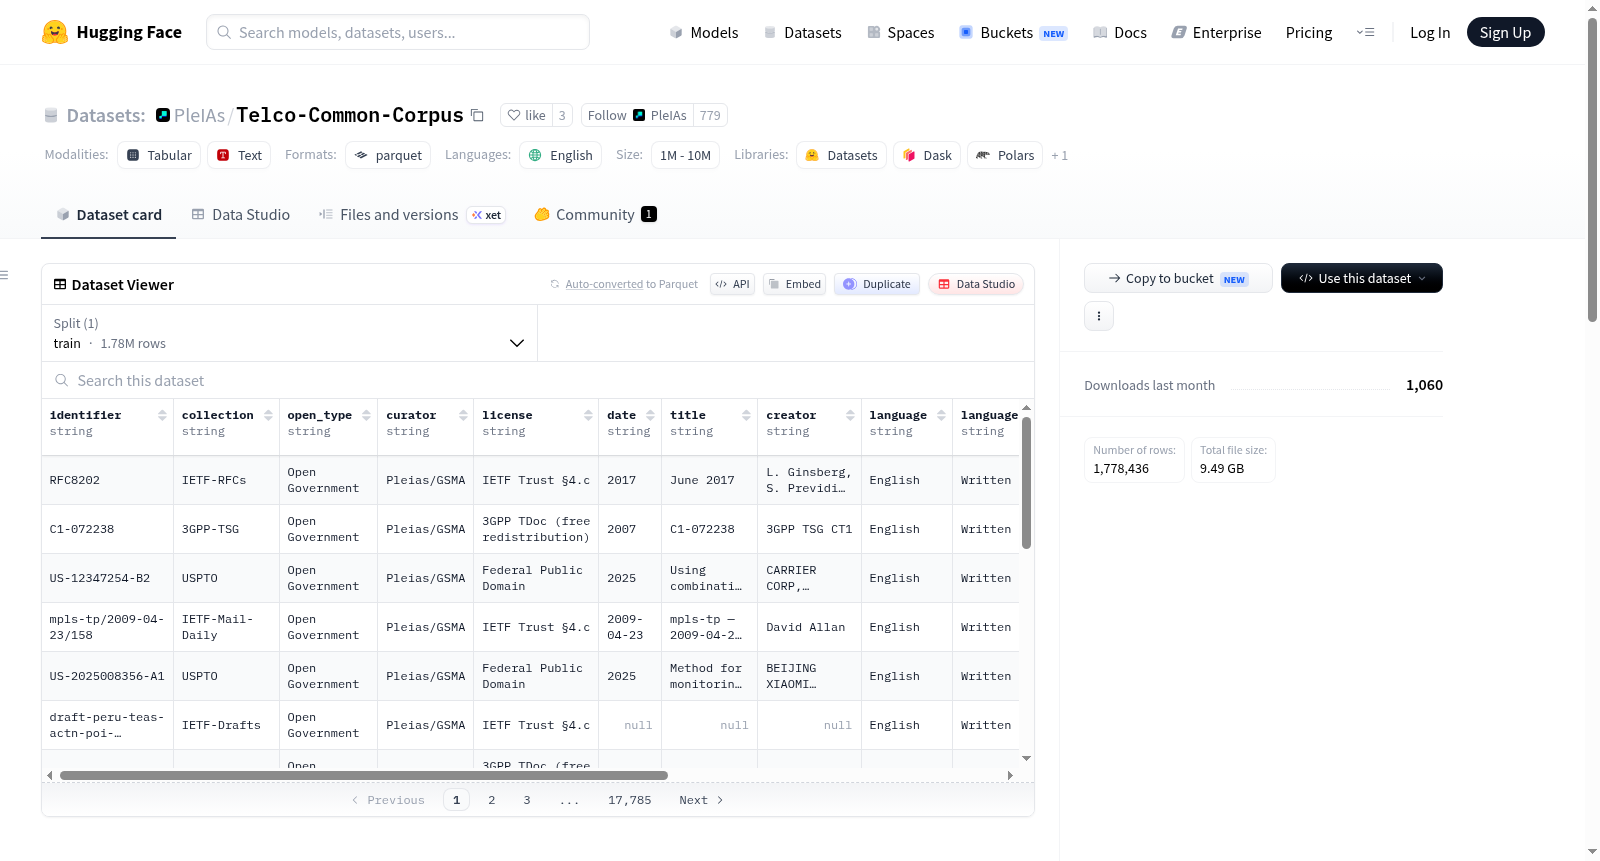
Telco Common Corpus (TCC) 是一个包含约100亿标记的完全开放、免费许可的电信知识集合,涵盖科学文献、专利、开放数据和开放网络项目,其许可和来源在文档级别进行了验证。该数据集源于GSMA为使AI服务于电信行业的努力,旨在解决当前模型在电信任务(如网络管理)上的不足。数据来源多样,包括3GPP预备文档、RFC规范、IEEE开放获取论文、美国及欧盟专利、Wikipedia和Wikidata的电信相关内容等,总计约100亿标记。处理过程使用Pleias内部管道(Stratum)和开源视觉语言模型(如dots.ocr)解析文档,保留表格等结构,并主要通过CommonLingua检测语言,数据集主要为英语。
Telco Common Corpus (TCC) is a ten billion tokens collection of fully open, free licensed telecommunications knowledge (scientific literature, patents, open data, and open-web projects) with licence and provenance verified at a document-level. It stems from GSMAs effort to make AI work for the telecom sector, addressing shortcomings in current models for telecom tasks. The dataset comprises diverse sources including 3GPP preparatory documents, RFC specifications, IEEE open access papers, US and EU patents, Wikipedia and Wikidata telecom content, totaling approximately ten billion tokens. Processing involves a Pleias internal pipeline (Stratum) using open weights VLMs like dots.ocr to parse documents while preserving structure, and the dataset is primarily English with language detection via CommonLingua.