
UIKA synthetic multi-view head dataset
收藏资源简介:
该数据集由蚂蚁集团等机构联合构建,是一个面向3D高斯头部重建任务的大规模合成多视角头部数据集。其核心特征包含丰富的身份多样性(数百种不同人种/年龄的头部模型)和表情变化(覆盖常见微表情及极端表情),数据来源为程序化生成的3D头部模型渲染图像。通过自动化管线生成多视角同步的RGB图像及对应UV坐标映射,解决了现有真实数据集中身份单一、视角覆盖不足的问题。该数据集主要用于训练高保真头部avatar重建模型,可支持单图/多图输入条件下的3D头部建模、表情重定向等虚拟人应用场景。
This dataset was jointly developed by Ant Group and other institutions, and is a large-scale synthetic multi-view head dataset tailored for 3D Gaussian head reconstruction tasks. Its core features include rich identity diversity (hundreds of head models covering diverse ethnicities and age groups) and diverse facial expression variations, spanning both common micro-expressions and extreme expressions. The data is sourced from rendered images of procedurally generated 3D head models. Using an automated pipeline, it generates synchronized multi-view RGB images and corresponding UV coordinate mappings, which addresses the key limitations of existing real-world datasets, namely limited identity diversity and insufficient view coverage. This dataset is primarily used for training high-fidelity head avatar reconstruction models, and supports various virtual human application scenarios such as 3D head modeling and expression retargeting under single-image or multi-image input conditions.
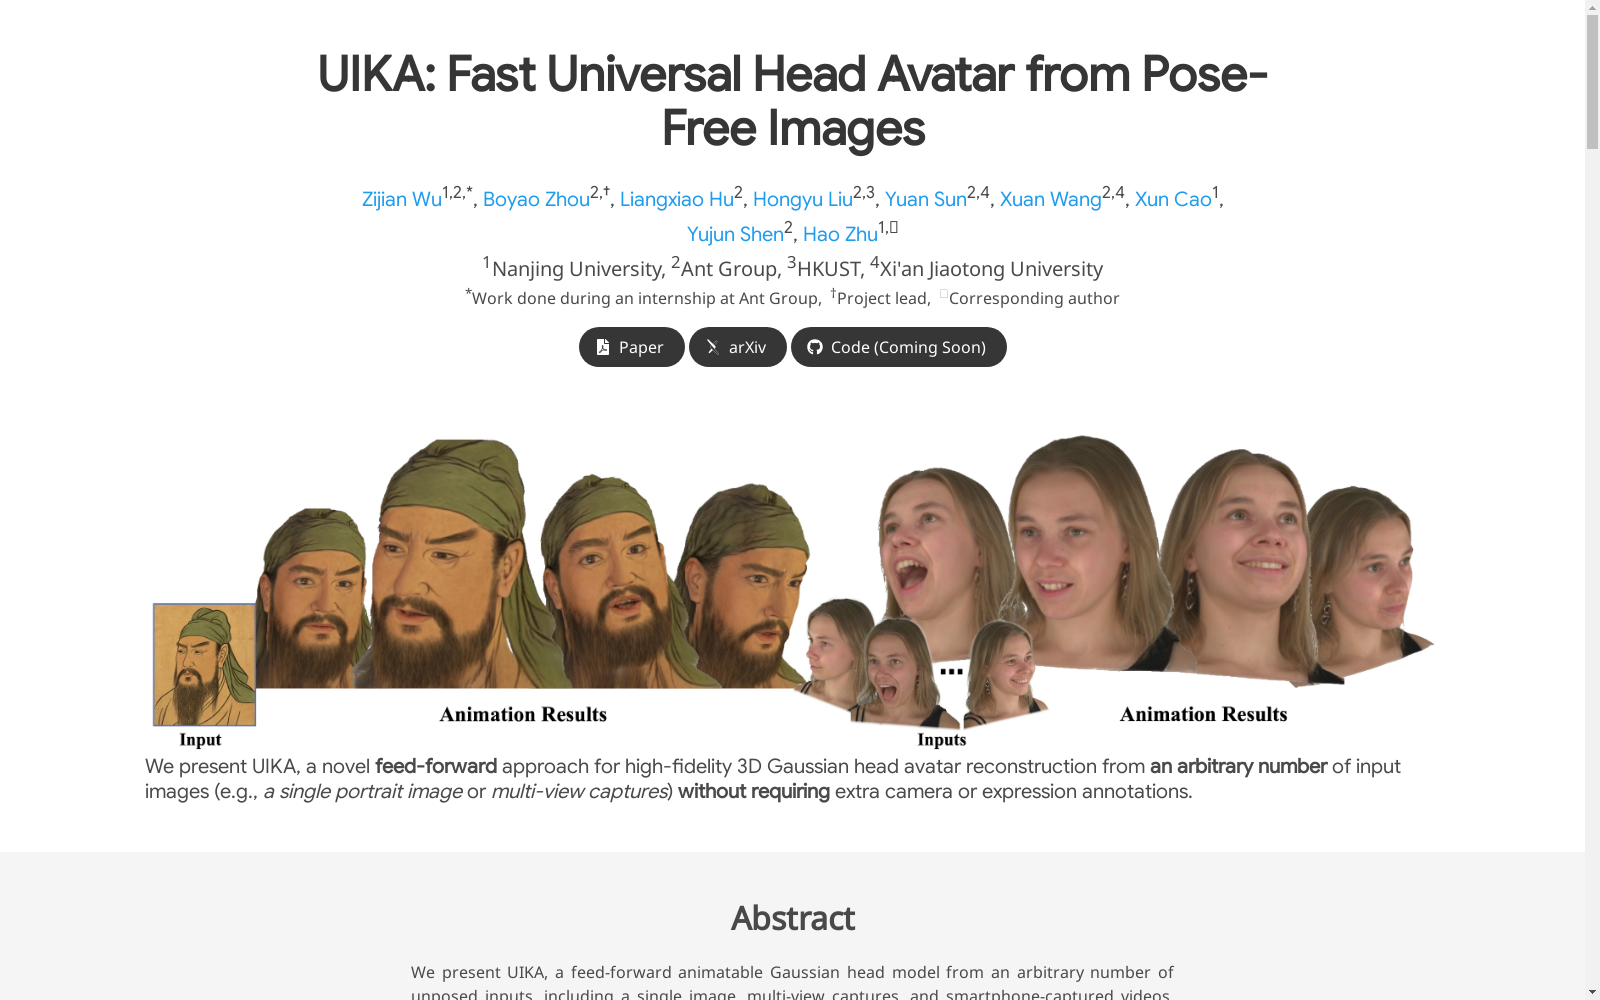
- 1UIKA: Fast Universal Head Avatar from Pose-Free Images南京大学; 蚂蚁集团; 香港科技大学; 西安交通大学 · 2026年


