CompactAI-O/Qwen-3-1.7B-Reasoning-x500
收藏资源简介:
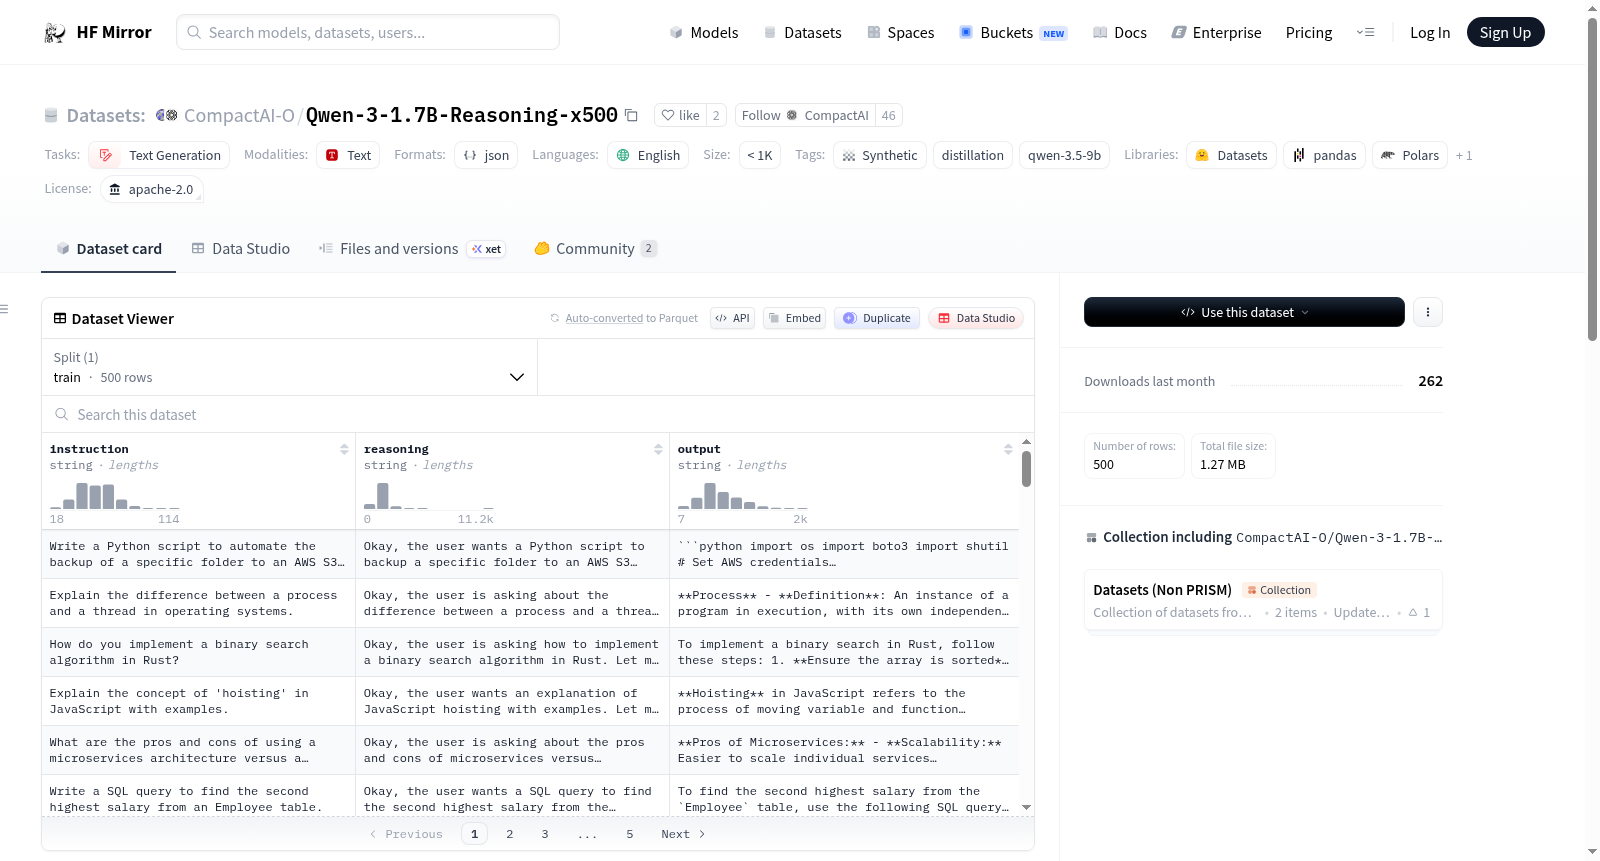
这是一个高质量合成数据集,包含由Qwen 3 1.7B生成的500个多样化样本。该数据集的目标是为小型语言模型(SLMs)提供清晰、直接和逻辑性的推理轨迹,以便将大型模型的能力蒸馏到小型模型中。数据集采用Alpaca格式,包含输入、推理和输出三个部分。生成方法是通过Ollama使用Qwen 3 1.7B,覆盖了25个不同领域的提示,重点是消除对话填充物并最大化信息密度,以教授小型模型推理和更好的英语句子结构。数据集的特点包括反拒绝焦点、多样化的领域覆盖以及针对SLMs的优化。
This is a high-quality synthetic dataset consisting of 500 diverse samples generated by Qwen 3 1.7B. The goal of this dataset is to provide clean, direct, and logical reasoning traces for distilling larger model capabilities into Small Language Models (SLMs). The data is provided in the Alpaca format, including input, reasoning, and output. It was generated using Qwen 3 1.7B via Ollama, covering 25 distinct domains with a focus on eliminating conversational filler and maximizing information density for teaching smaller models reasoning and better English sentence structure. The dataset features anti-refusal focus, diverse domain coverage, and optimization for SLMs.