omegalabsinc/omega-multimodal
收藏资源简介:
OMEGA Labs Bittensor Subnet数据集是一个用于加速人工通用智能(AGI)研究和开发的多模态数据集。该数据集通过Bittensor去中心化网络提供,旨在成为世界上最大的多模态数据集,涵盖人类知识和创造的广泛领域。数据集包含超过100万小时的视频和3000多万个2分钟的视频片段,覆盖50多种场景和15000多个动作短语。数据集利用最先进的模型将视频组件转换为统一的潜在空间,从而开发强大的AGI模型,并有可能改变多个行业。
The OMEGA Labs Bittensor Subnet Dataset is a groundbreaking resource for accelerating Artificial General Intelligence (AGI) research and development. This dataset, powered by the Bittensor decentralized network, aims to be the worlds largest multimodal dataset, capturing the vast landscape of human knowledge and creation. With over 1 million hours of footage and 30 million+ 2-minute video clips, the OMEGA Labs dataset will offer unparalleled scale and diversity, covering 50+ scenarios and 15,000+ action phrases. By leveraging state-of-the-art models to translate video components into a unified latent space, this dataset enables the development of powerful AGI models and has the potential to transform various industries.
OMEGA Labs Bittensor Subnet Dataset Summary
Overview
The OMEGA Labs Bittensor Subnet Dataset is designed to accelerate Artificial General Intelligence (AGI) research by providing a large-scale, multimodal dataset. This dataset includes over 1 million hours of footage and more than 30 million 2-minute video clips, covering over 50 scenarios and 15,000+ action phrases. It leverages advanced models to translate video components into a unified latent space, facilitating the development of AGI models.
Key Features
- Constant Stream of Fresh Data: The dataset is regularly updated with new entries, with an estimated addition of 5 million new videos daily.
- Rich Data: Data quality is ensured through a reward system based on diversity, richness, and relevance of the data.
- Latent Representations: Pre-computed ImageBind embeddings for video, audio, and captions are provided.
- Empowering Digital Agents: The dataset supports the development of intelligent agents capable of complex task navigation and user assistance.
- Flexible Metadata: Users can filter the dataset by various criteria, including topic relevance and cosine similarity.
Dataset Structure
The dataset includes the following columns:
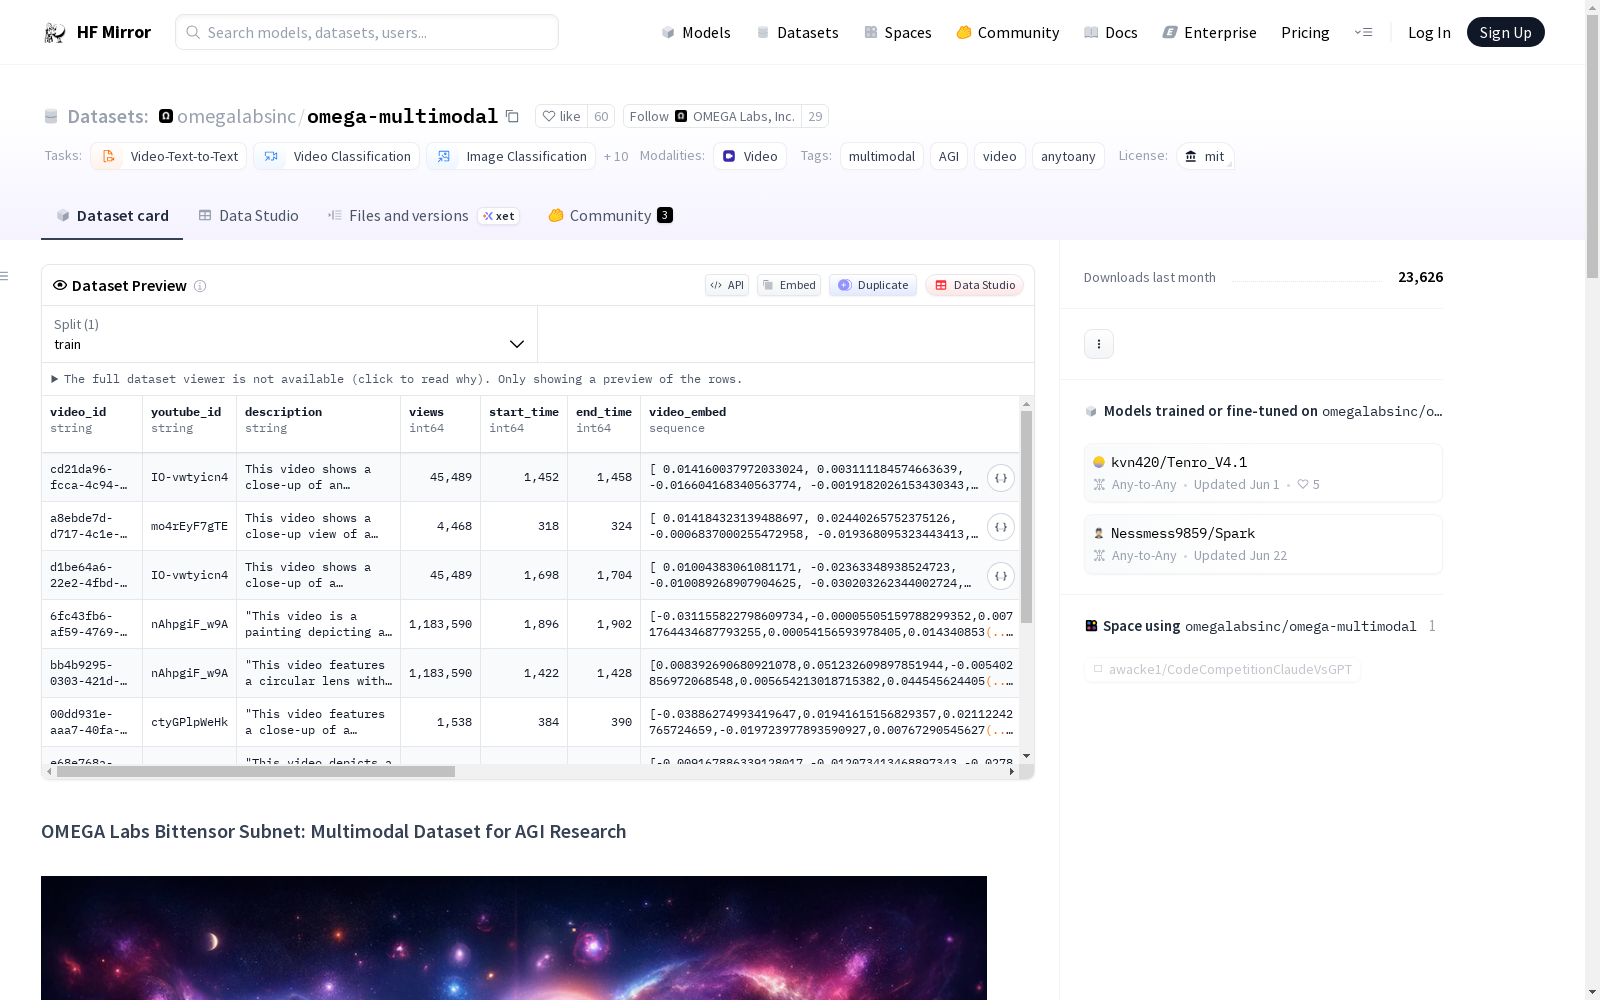
video_id: Unique identifier for each video clip.youtube_id: Original YouTube video ID.description: Description of the video content.views: Number of views on the original YouTube video.start_time: Start time of the clip within the original video.end_time: End time of the clip within the original video.video_embed: Latent representation of the video content.audio_embed: Latent representation of the audio content.description_embed: Latent representation of the video description.description_relevance_score: Relevance score of the video description.query_relevance_score: Relevance score of the video to the search query.query: Search query used to retrieve the video.submitted_at: Timestamp of when the video was added to the dataset.
Applications
The dataset is applicable for various AGI research and development tasks, including:
- Unified Representation Learning: Training models to learn across different modalities.
- Any-to-Any Models: Developing models that can translate between various modalities.
- Digital Agents: Creating intelligent agents for complex task management.
- Immersive Gaming: Enhancing gaming environments with realistic physics and interactions.
- Video Understanding: Advancing video processing tasks like transcription, motion analysis, and object detection.