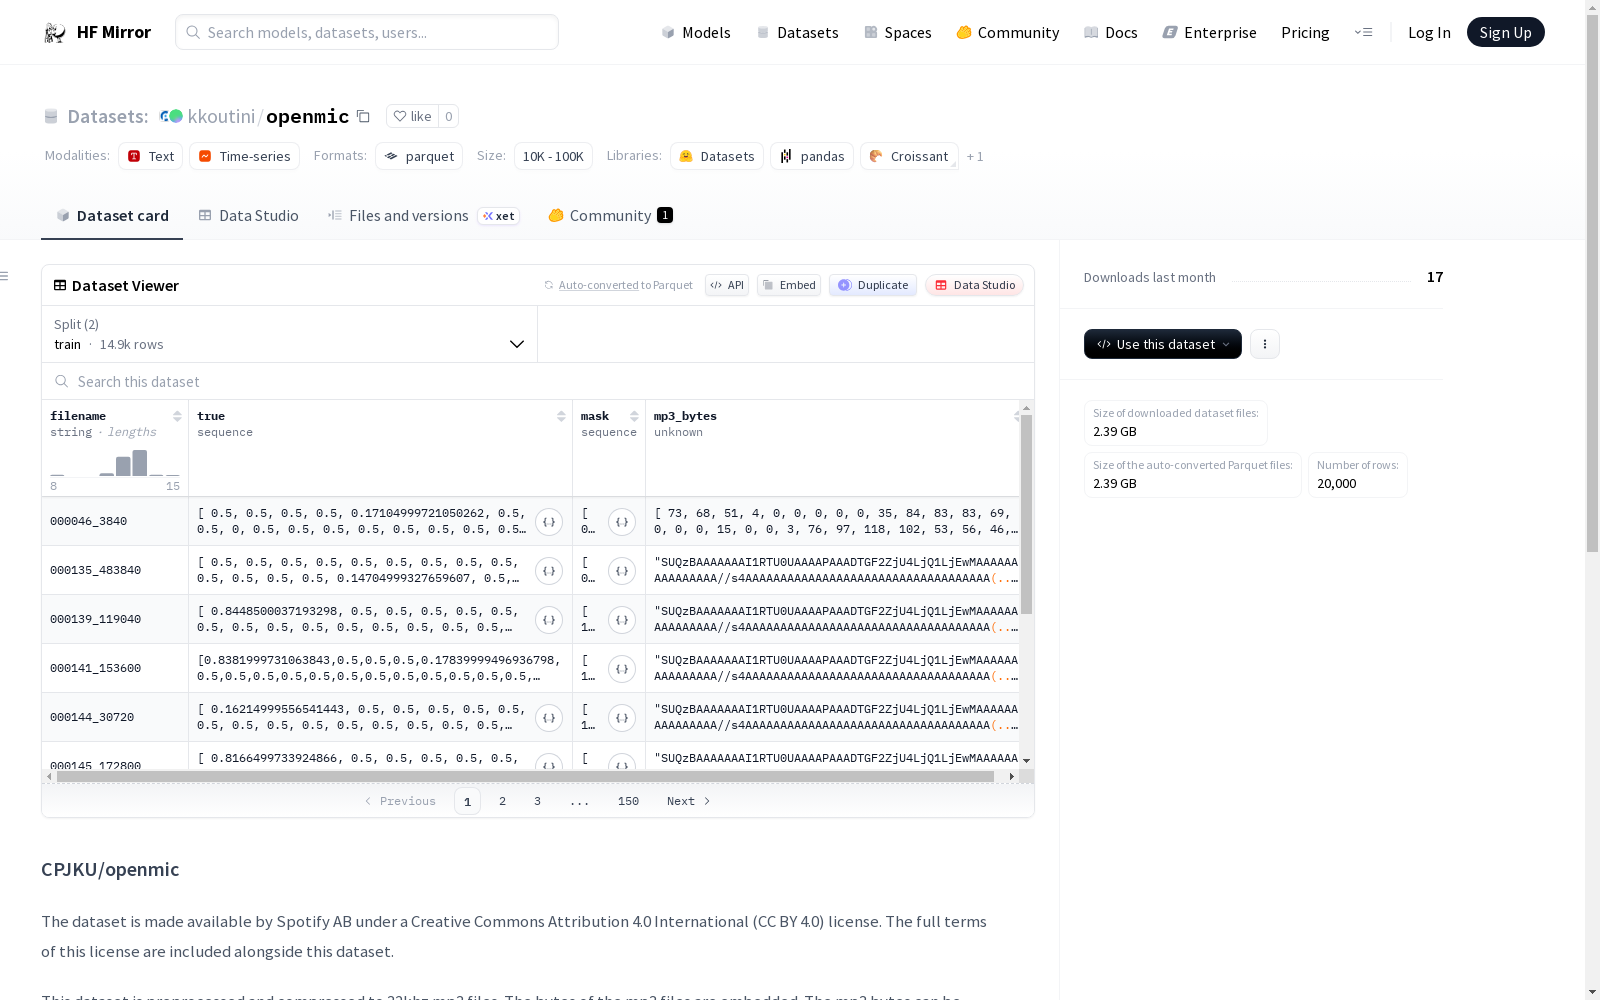
kkoutini/openmic
收藏资源简介:
--- dataset_info: features: - name: filename dtype: string - name: 'true' sequence: float32 length: 20 - name: mask sequence: int32 length: 20 - name: mp3_bytes dtype: binary splits: - name: train num_bytes: 1790991884 num_examples: 14915 - name: test num_bytes: 611455142 num_examples: 5085 download_size: 0 dataset_size: 2402447026 configs: - config_name: default data_files: - split: train path: data/shard_train_* - split: test path: data/shard_test_* --- # CPJKU/openmic The dataset is made available by Spotify AB under a Creative Commons Attribution 4.0 International (CC BY 4.0) license. The full terms of this license are included alongside this dataset. This dataset is preprocessed and compressed to 32khz mp3 files. The bytes of the mp3 files are embedded. The mp3 bytes can be decoded quickly using for [example](https://github.com/kkoutini/PaSST/blob/4519e4605989b8c2e62dccb5b928af9bf7bf8602/audioset/dataset.py#L55) or [minimp3](https://github.com/f0k/minimp3py). Take a look at the original dataset for more information. The original dataset contains the following: 10 second snippets of audio, in a directory format like 'audio/{0:3}/{0}.ogg'.format(sample_key) VGGish features as JSON objects, in a directory format like 'vggish/{0:3}/{0}.json'.format(sample_key) MD5 checksums for each OGG and JSON file Anonymized individual responses, in 'openmic-2018-individual-responses.csv' Aggregated labels, in 'openmic-2018-aggregated-labels.csv' Track metadata, with licenses for each audio recording, in 'openmic-2018-metadata.csv' A Python-friendly NPZ file of features and labels, 'openmic-2018.npz' Sample partitions for train and test, in 'partitions/*.txt' ## Homepage https://zenodo.org/records/1432913 ## Citation ``` Humphrey, Eric J., Durand, Simon, and McFee, Brian. "OpenMIC-2018: An Open Dataset for Multiple Instrument Recognition." in Proceedings of the 19th International Society for Music Information Retrieval Conference (ISMIR), 2018. ``` ## License CC BY 4.0
数据集信息: 特征: - 名称:filename,数据类型:字符串 - 名称:`true`,为长度20的float32型序列 - 名称:mask,为长度20的int32型序列 - 名称:mp3_bytes,数据类型:二进制 划分: - 名称:train(训练集),占用字节数:1790991884字节,样本数:14915 - 名称:test(测试集),占用字节数:611455142字节,样本数:5085 下载大小:0字节 数据集总大小:2402447026字节 配置: - 配置名称:default(默认配置),数据文件: - 训练集对应路径:data/shard_train_* - 测试集对应路径:data/shard_test_* # CPJKU/openmic 本数据集由Spotify AB按照知识共享署名4.0国际许可(Creative Commons Attribution 4.0 International,CC BY 4.0)发布,该许可的完整条款随本数据集一同提供。 本数据集已完成预处理并压缩为32kHz的MP3文件,MP3文件的二进制字节已嵌入数据集内。可通过例如[PaSST库dataset.py](https://github.com/kkoutini/PaSST/blob/4519e4605989b8c2e62dccb5b928af9bf7bf8602/audioset/dataset.py#L55)或[minimp3py](https://github.com/f0k/minimp3py)快速解码该MP3字节数据。 如需获取更多信息,请查阅原始数据集。原始数据集包含以下内容: 1. 10秒长度的音频片段,存储路径格式为`audio/{0:3}/{0}.ogg.format(sample_key)` 2. 以JSON对象形式存储的VGGish特征,存储路径格式为`vggish/{0:3}/{0}.json.format(sample_key)` 3. 每个OGG文件与JSON文件的MD5校验和 4. 匿名化的单条标注响应,存储于文件`openmic-2018-individual-responses.csv` 5. 聚合后的标注标签,存储于文件`openmic-2018-aggregated-labels.csv` 6. 轨道元数据(包含每条音频录制的许可信息),存储于文件`openmic-2018-metadata.csv` 7. 适用于Python的特征与标签NPZ文件`openmic-2018.npz` 8. 训练集与测试集的样本划分文件,存储于路径`partitions/*.txt` ## 项目主页 https://zenodo.org/records/1432913 ## 引用文献 汉弗莱斯(Eric J. Humphrey)、迪朗(Simon Durand)、麦克菲(Brian McFee). 《OpenMIC-2018:用于多乐器识别的开源数据集》[C]//第19届国际音乐信息检索学会会议(ISMIR 2018)论文集, 2018. ## 许可协议 CC BY 4.0(知识共享署名4.0国际许可)
数据集信息
特征
- filename: 字符串类型
- true: 浮点数序列,长度为20
- mask: 整数序列,长度为20
- mp3_bytes: 二进制类型
分割
- train: 字节数为1790991884,样本数为14915
- test: 字节数为611455142,样本数为5085
大小
- 下载大小: 0
- 数据集大小: 2402447026
配置
- config_name: default
- data_files:
- split: train, 路径: data/shard_train_*
- split: test, 路径: data/shard_test_*
- data_files: