PitchBench
收藏资源简介:
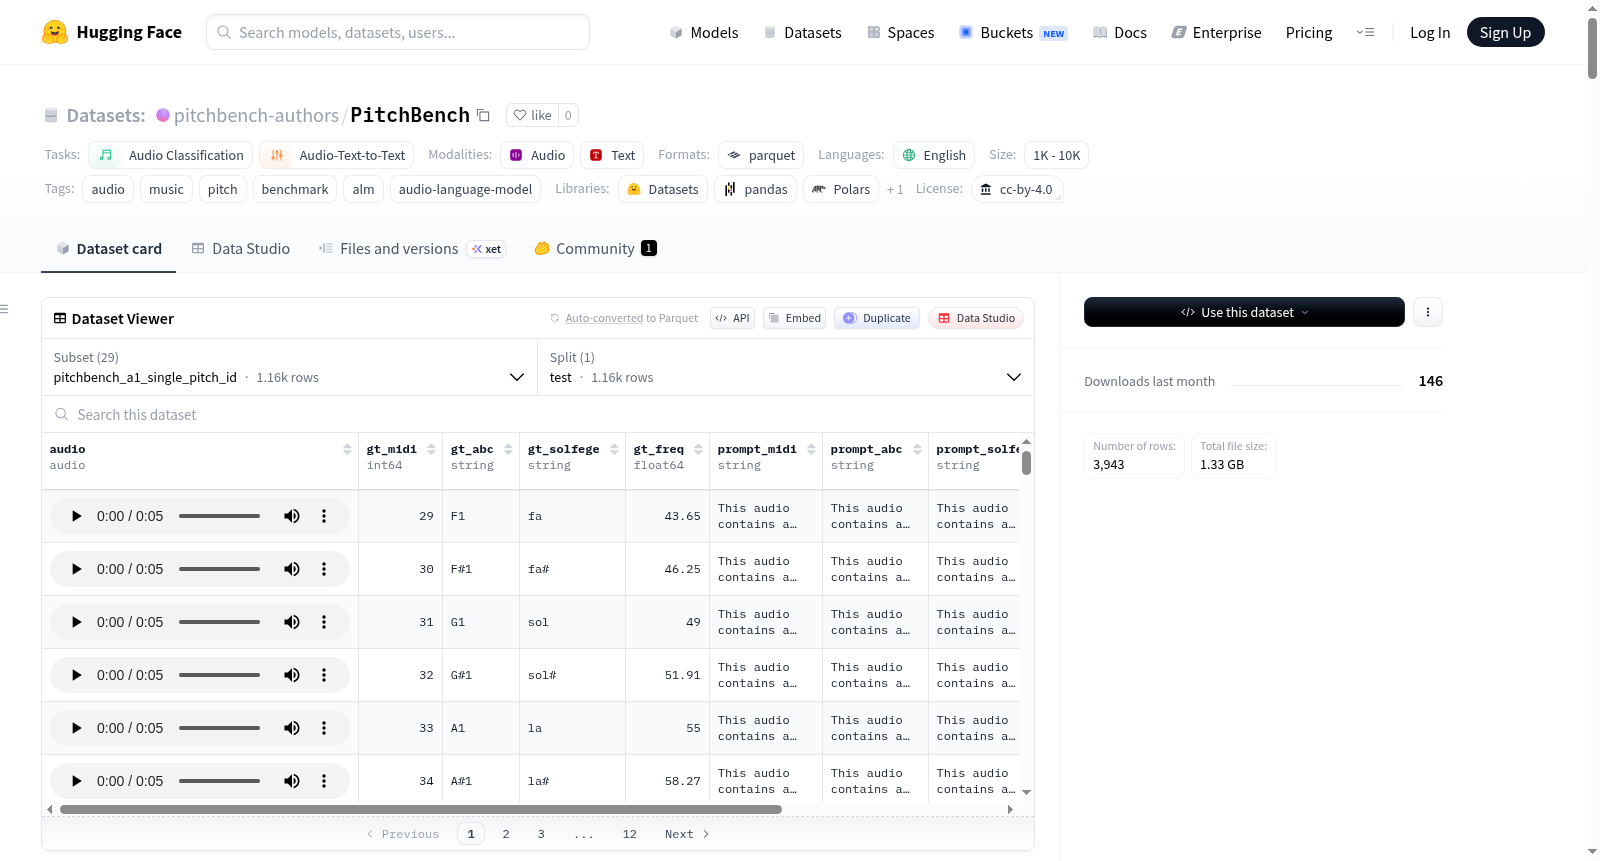
PitchBench是一个用于测试音频语言模型(ALMs)在音高感知方面能力的基准数据集。该数据集包含29个受控实验,共计5,932个音频刺激样本,每个样本由音频片段、问题和答案组成。实验涵盖单音高识别、响度和持续时间变化下的音高识别、时间定位、和弦与音程识别、序列音高任务等多个层次的任务。数据集旨在评估模型在不同声学条件下的音高感知能力,包括音频效果、背景噪声、谐波饱和等复杂场景。每个实验配置都有明确的独立变量和评分标准,涉及19种音色和广泛的音高范围。数据集适用于音频分类和音频到文本的任务,采用CC-BY-4.0许可协议发布。
PitchBench is a benchmark dataset designed to evaluate the pitch perception capabilities of Audio Language Models (ALMs). It comprises 29 controlled experiments with a total of 5,932 audio stimulus samples, each consisting of an audio clip, a question, and an answer. The experiments cover various levels of tasks, including single-pitch identification, pitch recognition under variations in loudness and duration, temporal localization, chord and interval identification, and sequential pitch tasks. The dataset aims to assess model performance in pitch perception across different acoustic conditions, including complex scenarios with audio effects, background noise, and harmonic saturation. Each experiment configuration has clearly defined independent variables and scoring criteria, involving 19 timbres and a wide pitch range. The dataset is suitable for audio classification and audio-to-text tasks and is released under the CC-BY-4.0 license.