An Image Dataset of Dunhuang Manuscripts for Fragments Conjunction
收藏资源简介:
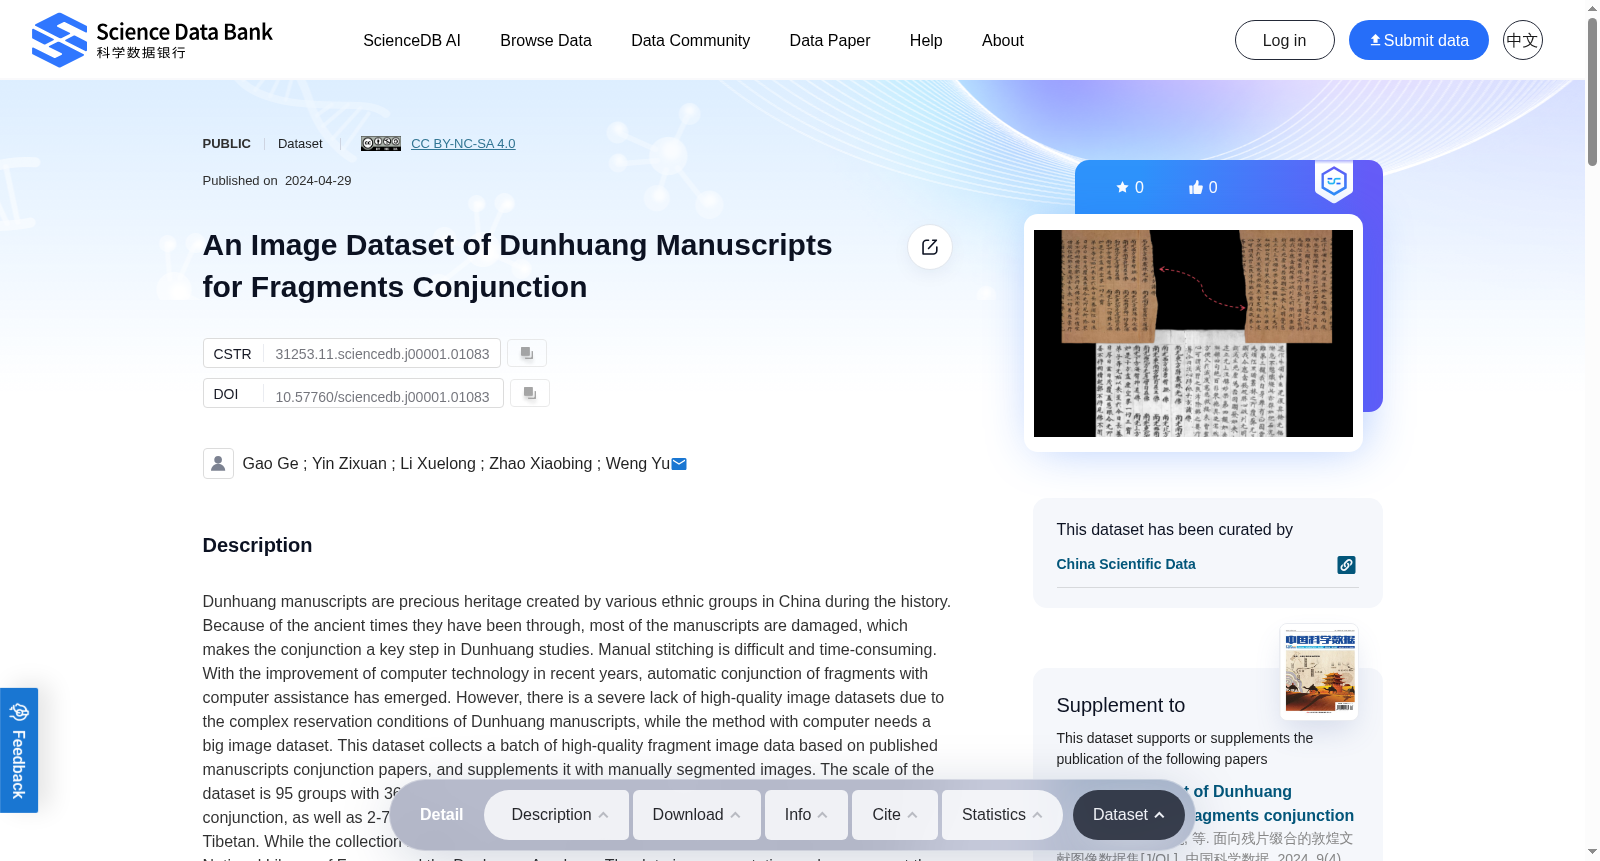
Dunhuang manuscripts are precious heritage created by various ethnic groups in China during the history. Because of the ancient times they have been through, most of the manuscripts are damaged, which makes the conjunction a key step in Dunhuang studies. Manual stitching is difficult and time-consuming. With the improvement of computer technology in recent years, automatic conjunction of fragments with computer assistance has emerged. However, there is a severe lack of high-quality image datasets due to the complex reservation conditions of Dunhuang manuscripts, while the method with computer needs a big image dataset. This dataset collects a batch of high-quality fragment image data based on published manuscripts conjunction papers, and supplements it with manually segmented images. The scale of the dataset is 95 groups with 366 images. Each group of data includes 1 completed image as the reference of conjunction, as well as 2-7 fragments. The content of images mainly involved Chinese, with some ancient Tibetan. While the collection institutions include the National Library of China, the British Library, the National Library of France, and the Dunhuang Academy. The data is representative and can support the training and validation of conjunction algorithms or models.
敦煌写本是中国历史上各民族共同创造的珍贵文化遗产。由于历经久远年代,绝大多数写本均已受损,因此缀合成为敦煌学研究的关键环节。人工缀合不仅难度颇高,且耗时耗力。近年来随着计算机技术的进步,借助计算机辅助的写本碎片自动缀合方法应运而生。然而,受敦煌写本复杂的保存状况所限,高质量图像数据集严重匮乏,而计算机辅助缀合方法却依赖大规模图像数据集。本数据集基于已发表的写本缀合研究论文,收集了一批高质量的碎片图像数据,并补充了经人工分割的图像样本。该数据集共计95组、366张图像。每组数据包含1张作为缀合参照的完整图像,以及2至7张碎片图像。图像内容以汉文为主,夹杂部分古藏文。本数据集的采集来源机构包括中国国家图书馆、大英图书馆、法国国家图书馆以及敦煌研究院。该数据集具备良好的代表性,可用于缀合算法或模型的训练与验证工作。