INSAIT-Institute/rit-arc-challenge
收藏资源简介:
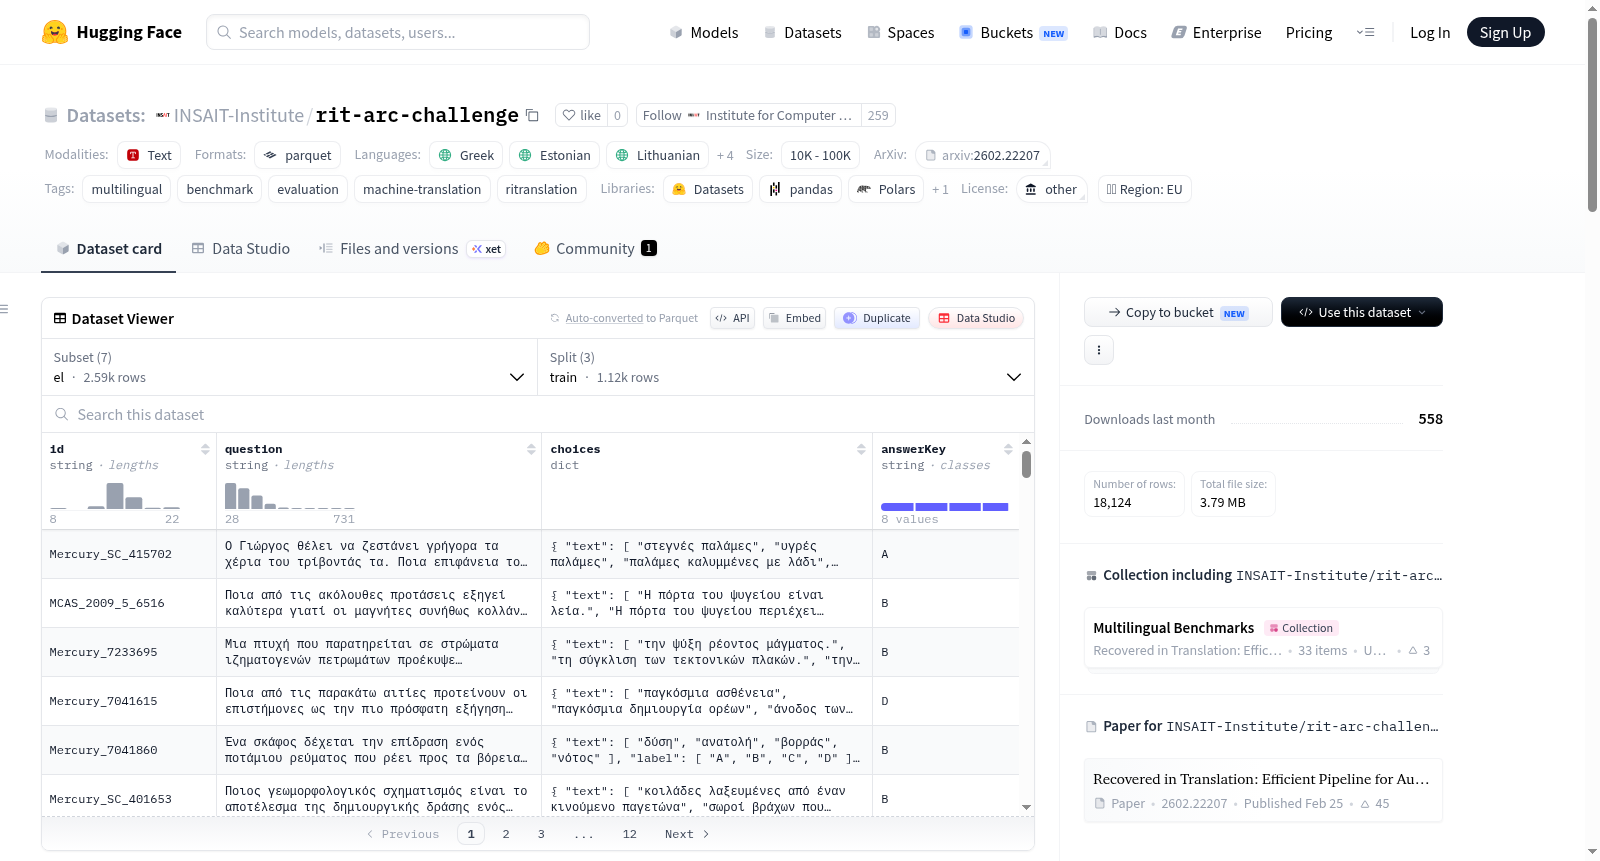
ARC-Challenge Multilingual是一个多语言基准测试数据集,源自“Recovered in Translation: Efficient Pipeline for Automated Translation of Benchmarks and Datasets”项目。该数据集重新组织了来自INSAIT-Institute/multilingual-benchmarks集合的每种语言版本,包含乌克兰语、爱沙尼亚语、土耳其语、罗马尼亚语、斯洛伐克语、希腊语和立陶宛语等语言配置。数据集包含小学科学问题,这些问题通常需要多步推理和背景知识,用于评估多语言语言模型的性能。每个语言配置都保留了原始数据集的拆分名称和模式,字段包括id、question、choices和answerKey。数据集旨在简化跨语言基准比较,同时将每种语言隔离为独立的配置。使用时应考虑机器翻译数据的局限性,如语言歧义和文化背景敏感性。
ARC-Challenge Multilingual is a multilingual benchmark dataset from the Recovered in Translation: Efficient Pipeline for Automated Translation of Benchmarks and Datasets project. It reorganizes per-language datasets from the INSAIT-Institute/multilingual-benchmarks collection into one repository with configs for Ukrainian, Estonian, Turkish, Romanian, Slovak, Greek, and Lithuanian. ARC-Challenge contains grade-school science questions that typically require multi-step reasoning and background knowledge. Each config preserves the split names and schema of the source dataset, with fields including id, question, choices, and answerKey. The dataset is intended for multilingual benchmark evaluation and analysis, facilitating cross-language model comparisons while keeping languages isolated as separate configs. Caveats include sensitivity to machine translation issues such as ambiguity and cultural context.