livt-instruct-dataset
收藏资源简介:
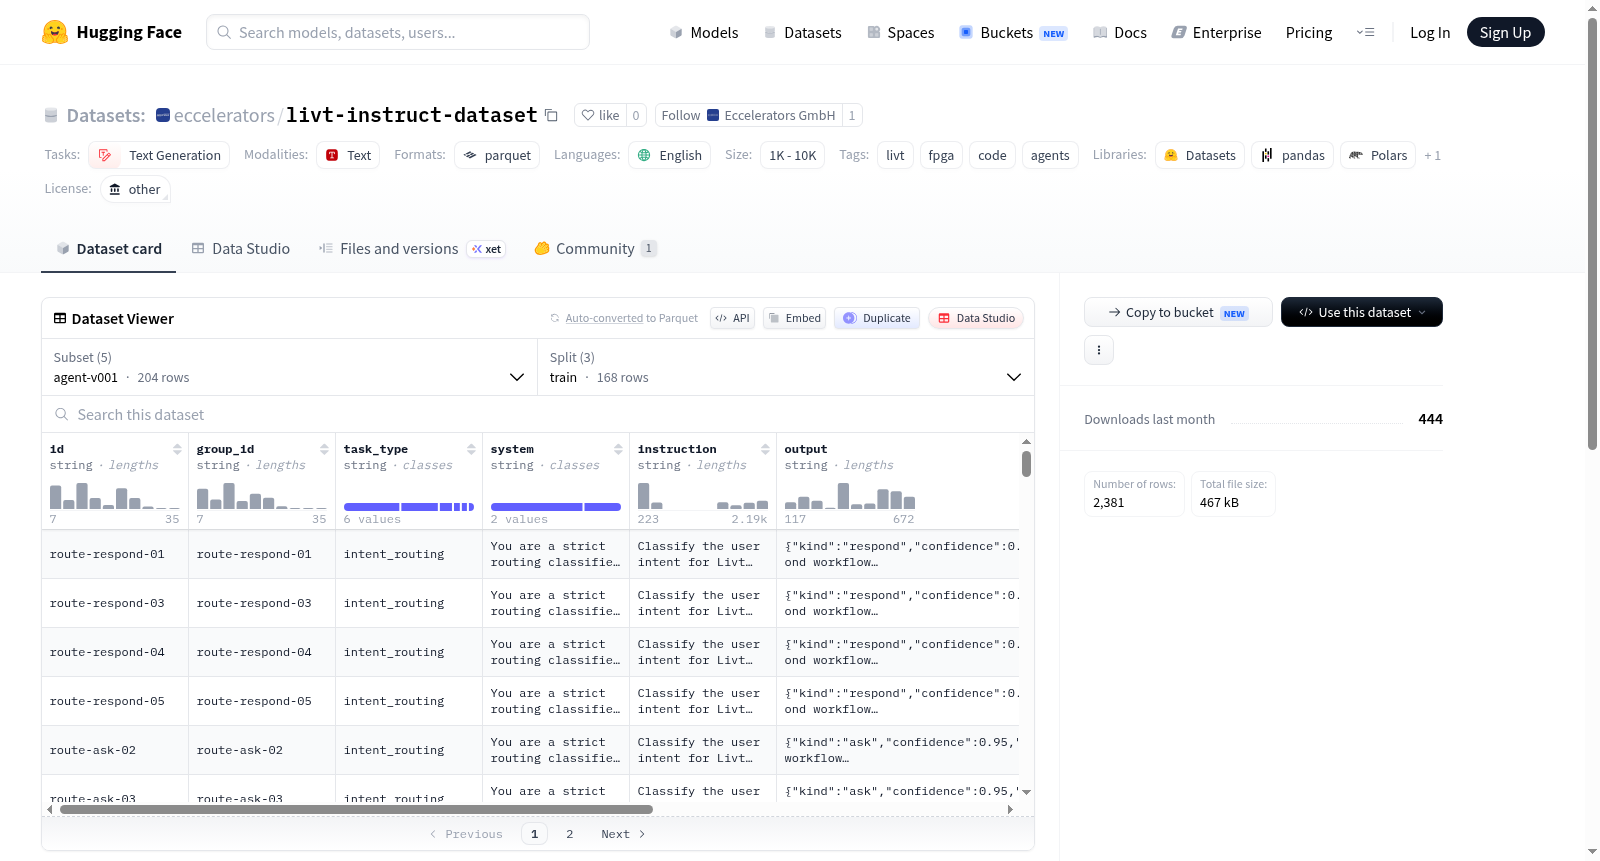
Livt Instruction Dataset 是一个用于文本生成任务的指令数据集,专注于 Livt 知识、vscode-livt 代理策略以及确定性混合训练配置的版本化管理。数据集包含多个配置版本:v001、agent-v001、mixed-v001、mixed-v001-agent10 和 mixed-v001-agent20,其中 mixed-v001 被推荐作为初始训练配置。每个版本均提供训练集、验证集和测试集划分,具体数据规模如下:v001 包含 363 个训练样本、49 个验证样本和 48 个测试样本;agent-v001 包含 168 个训练样本、23 个验证样本和 13 个测试样本;mixed-v001 包含 448 个训练样本、59 个验证样本和 65 个测试样本;mixed-v001-agent10 包含 429 个训练样本、56 个验证样本和 58 个测试样本;mixed-v001-agent20 包含 470 个训练样本、62 个验证样本和 70 个测试样本。数据集适用于代码生成、FPGA 相关任务以及智能体(agent)策略训练,语言为英语。
The Livt Instruction Dataset is an instruction dataset for text generation tasks, focusing on version management of Livt knowledge, vscode-livt agent strategies, and deterministic mixed training configurations. The dataset includes multiple configuration versions: v001, agent-v001, mixed-v001, mixed-v001-agent10, and mixed-v001-agent20, with mixed-v001 recommended as the initial training configuration. Each version provides splits for training, validation, and test sets, with specific data scales as follows: v001 contains 363 training samples, 49 validation samples, and 48 test samples; agent-v001 contains 168 training samples, 23 validation samples, and 13 test samples; mixed-v001 contains 448 training samples, 59 validation samples, and 65 test samples; mixed-v001-agent10 contains 429 training samples, 56 validation samples, and 58 test samples; mixed-v001-agent20 contains 470 training samples, 62 validation samples, and 70 test samples. The dataset is suitable for code generation, FPGA-related tasks, and agent strategy training, with the language being English.
数据集概述
- 数据集名称:Livt Instruction Dataset
- 语言:英语(en)
- 许可证:其他(other)
- 任务类别:文本生成(text-generation)
- 标签:livt、fpga、code、agents
数据集配置与数据划分
该数据集包含以下五个配置,每个配置均有训练(train)、验证(validation)和测试(test)三个数据划分,具体样本数量如下:
| 配置名称 | 训练集 | 验证集 | 测试集 |
|---|---|---|---|
| v001 | 363 | 49 | 48 |
| agent-v001 | 168 | 23 | 13 |
| mixed-v001 | 448 | 59 | 65 |
| mixed-v001-agent10 | 429 | 56 | 58 |
| mixed-v001-agent20 | 470 | 62 | 70 |
数据来源与推荐配置
- 独立版本化来源:
v001和agent-v001是独立版本化的数据源。 - 推荐初始训练配置:
mixed-v001是推荐的初始训练配置。
加载示例
python from datasets import load_dataset
dataset = load_dataset("eccelerators/livt-instruct-dataset", "mixed-v001")