SARA-QASPER
收藏资源简介:
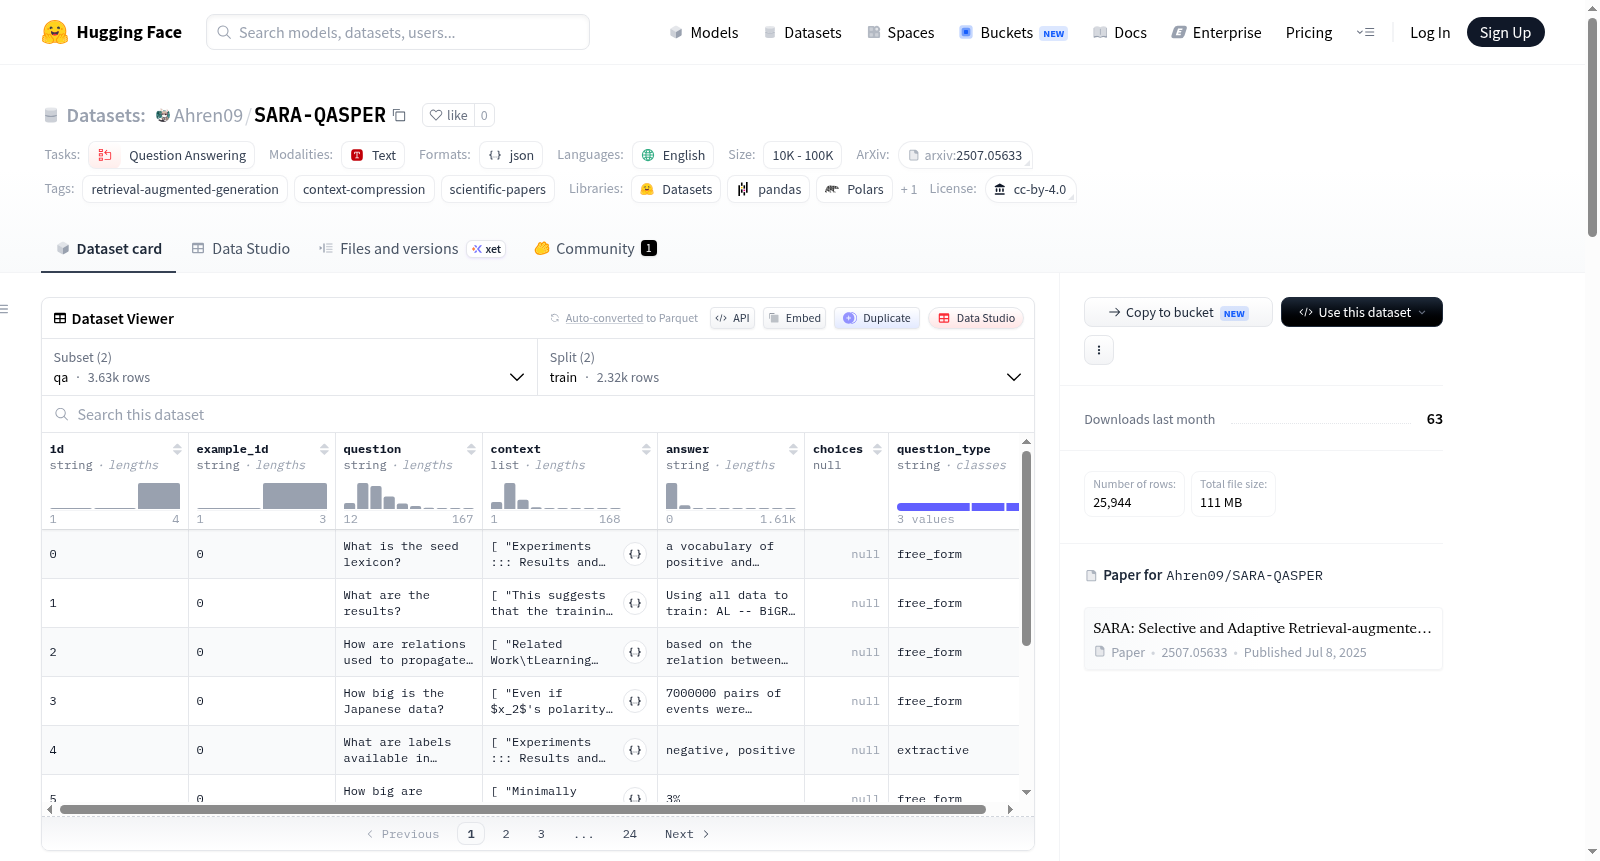
SARA QASPER (reformatted) 是一个基于 QASPER 数据集重新格式化的科学论文问答数据集,用于支持 SARA(Selective and Adaptive Retrieval-augmented Generation with Context Compression)模型的训练与评估。该数据集包含两个配置:第一个是默认的 qa 配置,针对每个可回答的 QASPER 问题,提供问题、上下文、答案和问题类型等字段,其中上下文由 BM25 算法从论文中排序的段落组成(格式为“章节名 <文本>”),答案是从原始 QASPER 注释中提取的简短黄金答案(如文本片段、数值、短语或 yes/no)。训练集包含 2,321 条记录(来自官方训练论文),测试集包含 1,312 条记录(来自官方测试论文)。第二个是 compression_alignment 配置,用于投影器对齐预热阶段,包含从 QASPER 论文正文中提取的文本片段,训练集 22,111 条,验证集 200 条。该数据集继承自 allenai/qasper(Dasigi et al., NAACL 2021),基于 CC BY 4.0 许可证发布。在 SARA 模型中,模型在训练时使用链式思维推理后跟标记答案的方式进行回答,评估时提取标记跨度与答案进行比较。
SARA QASPER (reformatted) is a scientific paper question-answering dataset reformatted from the QASPER dataset, designed to support the training and evaluation of SARA (Selective and Adaptive Retrieval-augmented Generation with Context Compression) models. It contains two configurations: the default qa configuration, which provides question, context, answer, and question type fields for each answerable QASPER question, where the context consists of paragraphs ranked by BM25 from the paper (formatted as section name <text>), and answers are short gold answers extracted from original QASPER annotations (e.g., text spans, numbers, phrases, or yes/no). The training set has 2,321 records (from official training papers) and the test set has 1,312 records (from official test papers). The second compression_alignment configuration is used for projector alignment warm-up, containing text spans extracted from QASPER paper bodies, with 22,111 training records and 200 validation records. This dataset is derived from allenai/qasper (Dasigi et al., NAACL 2021) and released under the CC BY 4.0 license. In the SARA model, during training, the model answers using chain-of-thought reasoning followed by labeled answers, and during evaluation, extracted span tokens are compared with answers.
SARA QASPER(重格式化)数据集概述
基本信息
- 数据集名称:SARA QASPER(重格式化)
- 许可证:CC BY 4.0
- 语言:英语
- 任务类别:问答(Question Answering)
- 标签:检索增强生成、上下文压缩、科学论文
数据集来源与背景
该数据集是对 QASPER(Dasigi 等人,NAACL 2021)的重格式化版本,用于 SARA:Selective and Adaptive Retrieval-augmented Generation with Context Compression(ACL 2026,arXiv:2507.05633)研究。原始 QASPER 数据集基于 CC BY 4.0 许可证发布,本衍生数据集在相同许可证下发布并注明出处。
数据集配置
1. qa 配置(默认)
每个记录对应一个可回答的 QASPER 问题,包含以下数据划分:
- 训练集:2,321 行(基于官方训练论文)
- 测试集:1,312 行(官方测试论文)
| 字段 | 类型 | 描述 |
|---|---|---|
id |
str | 行索引 |
example_id |
str | 论文索引,用于防泄漏的文档级训练/开发集划分 |
question |
str | QASPER 问题 |
context |
list[str] | BM25 排序的论文上下文,格式为 "章节名 <文本>" |
answer |
str | 简短黄金答案(片段、数值、短语或是/否),作为训练目标和评估参考 |
choices |
null | 未使用(保持与多选题数据集模式兼容) |
question_type |
str | 取值为 extractive、free_form、yes_no、unanswerable 之一 |
模型训练方式:模型以思维链方式输出推理过程,最终简短答案包裹在标签中:... 推理 ... <answer>简短答案</answer>;评估时提取标签内片段并与 answer 字段进行评分。
2. compression_alignment 配置
包含来自 QASPER 论文正文的文本片段,用于 SARA 投影器对齐预热阶段(投影器在问答微调前学习从语义压缩向量重构文档)。
- 训练集:22,111 行
- 验证集:200 行
- 每条记录格式为
{"text": "<文档文本片段>"}
数据处理细节
context字段由每篇论文的标题、摘要和章节构建,并按问题进行了 BM25 排序- 移除了
BIBREF引用标记 - 早期版本包含的 LLM 重写
answer_reformatted字段已移除,当前以简短黄金答案answer作为唯一参考标准
文件校验和(SHA256)
| 文件 | 校验和 |
|---|---|
| QASPER_train.jsonl | 0ec3d1bbab2f85341a9432b263ca90669f5cfd45bb2163170cedddf8ff60742c |
| QASPER_test.jsonl | a26afe8a11e350e5a860c83b75ee4938b2b89f19dc4883cea063dd90642bc1e1 |
| QASPER_compression_alignment_train.jsonl | 1d6386a84408127a20f01db92f8b9a73ec9499d884d0cab3c2c9f07c4494aa12 |
| QASPER_compression_alignment_dev.jsonl | 9de81c3cbf42aa4b4001a57762c37f981eb2ae0c5b468c3bfebffe65438f8a0f |
引用信息
该数据集关联两篇论文:
- SARA(ACL 2026):Jin 等人提出的选择性自适应检索增强生成与上下文压缩方法
- QASPER(NAACL 2021):Dasigi 等人提出的研究论文问答数据集