SINAI/ALIA-es-legal-administrative-cqa
收藏资源简介:
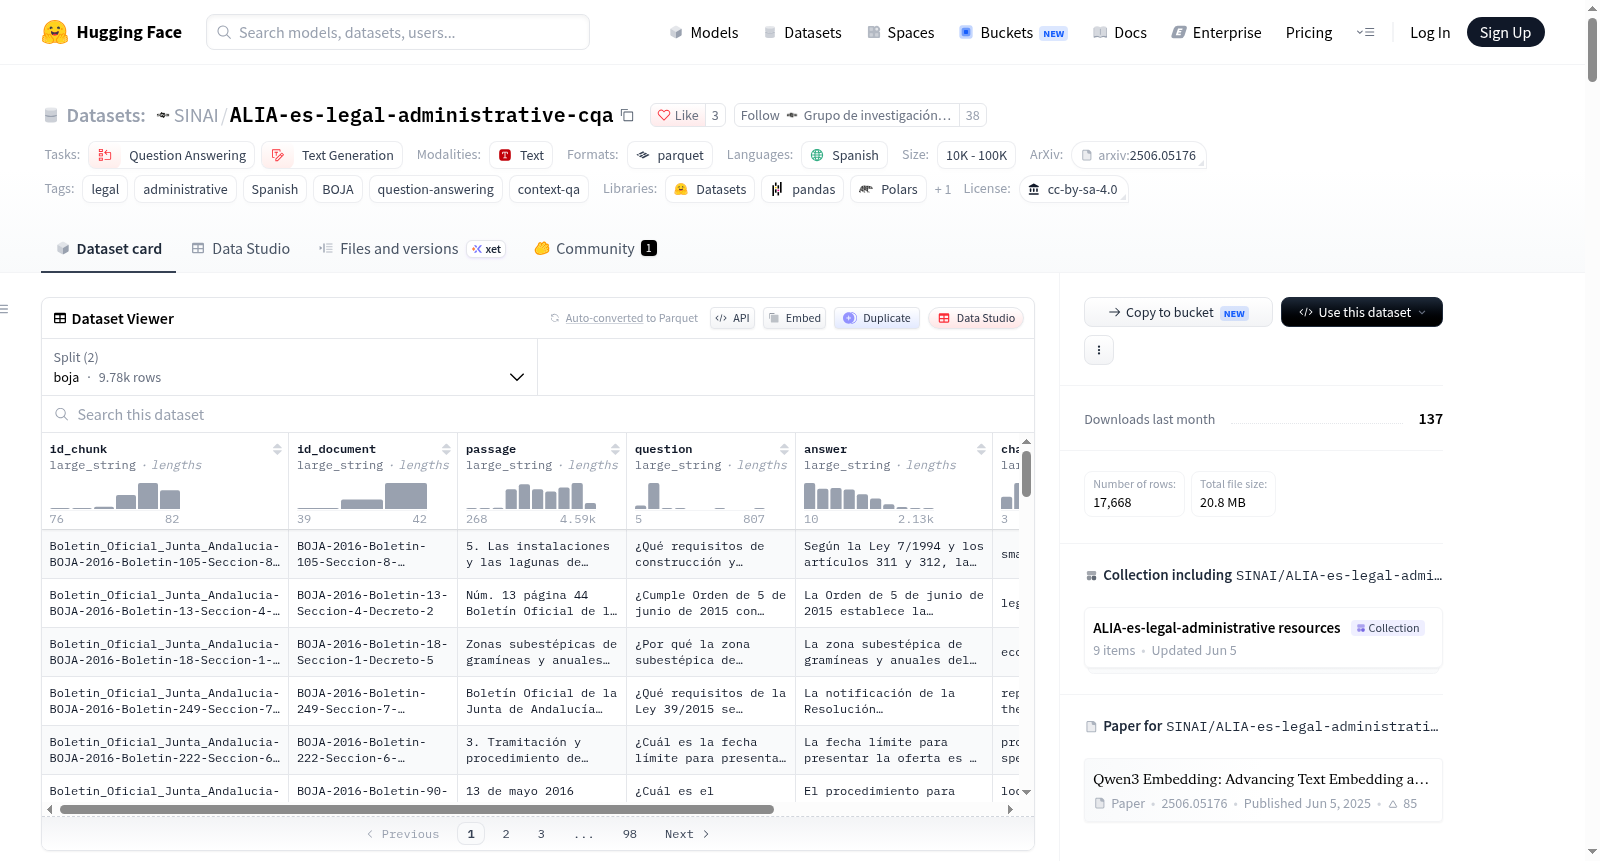
--- license: cc-by-sa-4.0 task_categories: - question-answering - text-generation language: - es tags: - legal - administrative - Spanish - BOJA - question-answering - context-qa size_categories: - 1K<n<10K configs: - config_name: default data_files: - split: boja path: "boja.parquet" - split: parlamint_es_an path: "parlamint_es_an.parquet" --- # Dataset Introduction The **ALIA Spanish Legal and Administrative for Context Question Answering Corpus** is a specialized question-answering resource derived from the [SINAI/ALIA-es-legal-administrative](https://huggingface.co/datasets/SINAI/ALIA-es-legal-administrative) corpus. This dataset transforms legal and administrative documents into structured question-answer pairs, enabling the development and evaluation of AI systems capable of understanding and responding to queries about Spanish legal-administrative content. With **17,668 structured instances** extracted from official Spanish documentation, this dataset supports research in legal question answering, information retrieval, and the development of specialized language models for the Spanish legal-administrative domain. ## Dataset Details ### Dataset Description The **ALIA Spanish Legal and Administrative Context Question Answering Dataset** is an open-access resource that provides structured question-answer pairs based on official Spanish legal-administrative documents. Its purpose is to enable the development and evaluation of question-answering systems specialized in Spanish legal and administrative language, facilitating both research in natural language processing and the creation of practical tools for citizens, legal professionals, and public administration practitioners. This dataset has been designed to cover diverse information needs from multiple user perspectives, including legal professionals (judges, lawyers), government officials, business owners, urban planners, educators, and citizens. Each instance consists of a passage extracted from an official document, along with synthetically generated questions, answers, character personas, and difficulty levels that reflect realistic information needs. The dataset, with **17,668 question-answer pairs** derived from **6,740 unique documents** from the Boletín Oficial de la Junta de Andalucía (BOJA) and the Parlamento de Andalucía (ParlaMint-ES-AN), represents a valuable resource for evaluating AI systems in the Spanish legal-administrative domain. The synthetic generation methodology, based on techniques from the Qwen3 Embeddings paper, ensures consistency and scalability in creating high-quality evaluating data. ### Dataset Sources - **Base Corpus:** [ALIA Spanish Legal and Administrative Corpus](https://huggingface.co/datasets/SINAI/ALIA-es-legal-administrative) - **Methodology Reference:** [Qwen3 Embeddings Paper](https://arxiv.org/abs/2506.05176) - **Synthetic Generation Model:** [GPT-OSS-20B](https://huggingface.co/openai/gpt-oss-20b) ### Uses The primary purpose of this dataset is to serve as a foundation for evaluating question-answering systems specialized in the Spanish legal-administrative domain, with applications in: - Research in natural language processing applied to the legal-administrative domain. - Building AI assistants for citizens and professionals to understand Spanish regulations. - Benchmarking synthetic data generation methodologies for specialized domains. - Evaluating legal-administrative information retrieval systems. ## Dataset Structure ### Data Instances Each instance in the corpus has the following structure: ```json { "id_chunk": "Boletin_Oficial_Junta_Andalucia-BOJA-2016-Boletin-105-Seccion-8-Decreto-55-410485", "id_document": "BOJA-2016-Boletin-105-Seccion-8-Decreto-55", "passage": "5. Las instalaciones y las lagunas de secado contarán con barrera vegetal para mitigar el impacto visual desde los núcleos de población, carreteras y ferrocarril. Artículo 311. Condiciones Particulares de Edificación de las instalaciones anejas a la explotación de recursos mineros...", "question": "¿Qué requisitos de construcción y distancia deben cumplirse para instalaciones mineras de pequeña escala según la Ley 7/1994?", "answer": "Según la Ley 7/1994 y los artículos 311 y 312, las instalaciones mineras de pequeña escala deben cumplir los siguientes requisitos de construcción y distancia: 1) Separación de 250 metros de cualquier otra edificación...", "character": "small-scale miner", "difficulty": "university" } ``` ### Data Fields - **id_chunk** (string): Unique identifier for the specific chunk/passage within the source document. - **id_document** (string): Identifier of the source document from which the passage is extracted. - **passage** (string): The context text from the legal-administrative document that contains information relevant to the question (extracted from the original ALIA-legal-administrative corpus). - **question** (string): A synthetically generated question about the information contained in the passage. - **answer** (string): A synthetically generated comprehensive answer to the question based on the passage content. - **character** (string): A synthetically generated persona or user type for whom the question is relevant (e.g., "policy advisor", "district court judge", "local journalist"). - **difficulty** (string): A synthetically generated complexity level of the question-answer pair (e.g., "university", "high_school", "phd"). ### Data Splits The complete dataset contains **17,668 question-answer pairs** from official Spanish legal-administrative sources with the following statistics: | Metric | Value | |--------|-------| | Total QA Pairs | 17,668 | | Unique Documents | 6,740 | | Sources | Boletín Oficial de la Junta de Andalucía (BOJA), ParlaMint-ES-AN | | Average Passage Length | 2,978 characters | | Average Question Length | 108 characters | | Average Answer Length | 592 characters | The dataset is organized into **two splits**: #### Split: `boja` - **9,776 QA pairs** from Boletín Oficial de la Junta de Andalucía. - **6,474 unique documents** - Focus: Official legislation, regulations, and administrative acts. - Average passage length: 2,932 characters. - Average answer length: 613 characters. #### Split: `parlamint_es_an` - **7,892 QA pairs** from Parliament of Andalusia proceedings. - **266 unique documents**. - Focus: Parliamentary debates, speeches, and legislative discussions. - Average passage length: 3,034 characters. - Average answer length: 565 characters. #### Source Distribution | Source | Split | Count | Percentage | |--------|-------|-------|------------| | Boletin_Oficial_Junta_Andalucia | boja | 9,776 | 55.3% | | ParlaMint-ES-AN | parlamint_es_an | 7,892 | 44.7% | | **TOTAL** | - | **17,668** | **100%** | #### Character/Persona Distribution (Top 10) | Character | Count | |-----------|-------| | Policy Advisor | 320 | | Government Official | 220 | | Human Resources Manager | 204 | | Policy Analyst | 199 | | Constitutional Law Expert | 163 | | District Court Judge | 145 | | Health Policy Analyst | 138 | | Local Journalist | 135 | | Public Administration Expert | 127 | | City Council Member | 123 | #### Difficulty Distribution | Difficulty Level | Count | Percentage | |-----------------|-------|------------| | University | 16,550 | 93.7% | | High School | 994 | 5.6% | | PhD | 102 | 0.6% | | Other levels | 22 | 0.1% | ### Example Usage To load the dataset: ```python from datasets import load_dataset # Load the complete dataset dataset = load_dataset("SINAI/ALIA-es-legal-administrative-cqa") # Load specific split boja_dataset = load_dataset("SINAI/ALIA-es-legal-administrative-cqa", split="boja") parlamint_dataset = load_dataset("SINAI/ALIA-es-legal-administrative-cqa", split="parlamint_es_an") # Load with streaming (recommended for iterative processing) dataset = load_dataset("SINAI/ALIA-es-legal-administrative-cqa", streaming=True) ``` Example of data access: ```python # Access an example from BOJA split example = dataset['boja'][0] print(f"Question: {example['question']}") print(f"Passage: {example['passage'][:200]}...") print(f"Answer: {example['answer'][:200]}...") print(f"Character: {example['character']}") print(f"Difficulty: {example['difficulty']}") # Access an example from ParlaMint-ES-AN split parlamint_example = dataset['parlamint_es_an'][0] print(f"Question: {parlamint_example['question']}") print(f"Document ID: {parlamint_example['id_document']}") # Filter by difficulty level university_questions = [ex for ex in dataset['boja'] if ex['difficulty'] == 'university'] # Filter by character type judge_questions = [ex for ex in dataset['boja'] if 'judge' in ex['character'].lower()] # Compare both sources print(f"BOJA instances: {len(dataset['boja'])}") print(f"ParlaMint instances: {len(dataset['parlamint_es_an'])}") ``` ## Dataset Creation ### Curation Rationale This dataset was created to address the critical need for high-quality, scalable evaluating data for Spanish legal-administrative question-answering systems. Traditional approaches to creating QA datasets require extensive manual annotation by domain experts, which is time-consuming and expensive, particularly in specialized domains like legal text. By leveraging synthetic data generation techniques inspired by the Qwen3 Embeddings paper methodology, this dataset provides: - **Scalability**: Efficient generation of large-scale QA pairs without extensive manual annotation. - **Consistency**: Systematic coverage of diverse legal topics and user perspectives. - **Cost-Effectiveness**: Reduced annotation costs while maintaining quality. - **Domain Specialization**: Focus on Spanish legal-administrative language and concepts. - **Evaluation Resources**: Structured data for benchmarking legal QA systems. - **Dual Perspectives**: Coverage of both formal legislation (BOJA) and parliamentary discourse (ParlaMint-ES-AN). The inclusion of both BOJA documentation and ParlaMint-ES-AN proceedings ensures comprehensive coverage of Andalusian regional legislation, administrative procedures, and legislative debates, representing a significant portion of the regulatory framework and political discourse that affects citizens and businesses in Andalusia. ### Source Data The passages in this dataset are extracted directly from the [ALIA Spanish Legal and Administrative Corpus](https://huggingface.co/datasets/SINAI/ALIA-es-legal-administrative), specifically from two main sources: #### Official Bulletins - **Boletin_Oficial_Junta_Andalucia (BOJA)**: Andalusian regional legislation, covering areas such as urban planning, education, health, environment, labor, agriculture, industry, and public administration. - **Current version**: 9,776 QA pairs from BOJA documents. - 6,474 unique documents. - All passages extracted from the BOJA portion of the ALIA-legal-administrative corpus. #### Parliamentary Proceedings - **ParlaMint-ES-AN**: Parliamentary proceedings from the Parliament of Andalusia (1982-2025), including debates, speeches, interventions, and legislative discussions. - **Current version**: 7,892 QA pairs from ParlaMint-ES-AN documents - 266 unique documents (parliamentary sessions). - Passages extracted from the ParlaMint-ES-AN portion of the ALIA-legal-administrative corpus. All source passages come from official and publicly accessible documents available through: - BOJA: [https://www.juntadeandalucia.es/eboja](https://www.juntadeandalucia.es/eboja) - Parliament of Andalusia: [https://www.parlamentodeandalucia.es/](https://www.parlamentodeandalucia.es/) ### Data Collection and Processing The dataset was created through a systematic synthetic generation pipeline: 1. **Passage Extraction**: Text passages were extracted from the ALIA-legal-administrative corpus, maintaining document context and structure. 2. **Synthetic Generation**: Using GPT-OSS-20B following the methodology from the Qwen3 Embeddings paper, the following elements were generated for each passage: - Question: Realistic information queries relevant to the passage content. - Answer: Comprehensive responses grounded in the passage. - Character: User personas representing different stakeholder types. - Difficulty: Complexity level assessment. 3. **Quality Assurance**: Generated instances were filtered for: - Minimum and maximum length thresholds. - Coherence between question, passage, and answer. - Diversity of question types and personas. 4. **Split Organization**: Instances were organized into two splits (boja and parlamint_es_an) based on source document type. ### Annotations All annotations in this dataset are **synthetically generated** rather than manually created. This includes: #### Synthetic Annotations **1. Question (Synthetic)** - Generated by GPT-OSS-20B to represent realistic information needs. - Designed to span various complexity levels and question types. - Grounded in the content of the source passage. - Average length: 108 characters. **2. Answer (Synthetic)** - Generated by GPT-OSS-20B based on passage content. - Aims for comprehensiveness and legal accuracy. - Maintains consistency in style and quality across the dataset. - Average length: 592 characters. **3. Character/Persona (Synthetic)** - Automatically assigned to represent diverse user types. - Categories include: - **Legal professionals**: district court judge, lawyer, attorney, constitutional law expert. - **Government officials**: policy advisor, government official, city planner, policy analyst. - **Business stakeholders**: entrepreneur, business owner, company director, real estate developer. - **Technical professionals**: urban planner, architect, engineer, construction company owner. - **Citizens and community**: local journalist, city council member, mayor, resident. - **Health and education**: health policy analyst, university admissions officer, teacher. - Enables development of persona-specific QA systems. - Total unique personas: 320+ different character types. **4. Difficulty Level (Synthetic)** - Automatically classified based on legal concept complexity. - Distribution: - **University (93.7%)**: Requires higher education-level comprehension. - **High School (5.6%)**: Accessible to secondary education-level understanding. - **PhD (0.6%)**: Requires advanced specialized legal knowledge. - **Other levels (0.1%)**: Additional granular classifications. **Important Note**: All questions, answers, character assignments, and difficulty levels are synthetically generated. Users should be aware that these are not human-annotated and may require additional validation for critical applications. ### Personal and Sensitive Information The dataset maintains the same privacy standards as the source [ALIA Spanish Legal and Administrative Corpus](https://huggingface.co/datasets/SINAI/ALIA-es-legal-administrative): - **Source Passages**: Extracted from publicly accessible official BOJA and ParlaMint-ES-AN publications. - **Data Protection**: Personal data in source documents has been handled according to Spanish and EU data protection regulations (GDPR/RGPD). - **Official Context**: References to individuals typically appear only in official contexts (legislators, public officials in official capacities). - **Parliamentary Records**: ParlaMint-ES-AN contains names of parliamentarians and public officials as part of the official parliamentary record. - **Synthetic Generation**: The question-answer generation process does not introduce additional personal information beyond what exists in the source passages. - **User Responsibility**: Users are advised to apply appropriate safeguards depending on the specific use of the dataset. ### Citation ```bibtex @misc{ALIA-es-legal-administrative-cqa, title={ALIA Spanish Legal and Administrative for Context Question Answering Corpus}, author={SINAI Research Group}, year={2026}, publisher={HuggingFace}, howpublished={\url{https://huggingface.co/datasets/SINAI/ALIA-es-legal-administrative-cqa}} } ``` --- ## Funding This work is funded by the Ministerio para la Transformación Digital y de la Función Pública - Funded by EU – NextGenerationEU within the framework of the project [ALIA](https://alia.gob.es). ### Acknowledgments This dataset has been generated thanks to [SCAYLE](https://www.scayle.es/) (Centro de Supercomputación de Castilla y León) which provided the needed computational resources on its CALENDULA supercomputing cluster. --- **Contact:** [ALIA Project](https://www.alia.gob.es/) - [SINAI Research Group](https://sinai.ujaen.es) - [Universidad de Jaén](https://www.ujaen.es/) **More Information:** [SINAI Research Group](https://sinai.ujaen.es) | [ALIA-UJA Project](https://github.com/SINAI/ALIA-UJA)
The ALIA Spanish Legal and Administrative for Context Question Answering Corpus is a specialized question-answering resource derived from the SINAI/ALIA-es-legal-administrative corpus. This dataset transforms legal and administrative documents into structured question-answer pairs, enabling the development and evaluation of AI systems capable of understanding and responding to queries about Spanish legal-administrative content. With 17,668 structured instances extracted from official Spanish documentation, this dataset supports research in legal question answering, information retrieval, and the development of specialized language models for the Spanish legal-administrative domain. The dataset is designed to cover diverse information needs from multiple user perspectives, including legal professionals (judges, lawyers), government officials, business owners, urban planners, educators, and citizens. Each instance consists of a passage extracted from an official document, along with synthetically generated questions, answers, character personas, and difficulty levels that reflect realistic information needs. The dataset is based on two main sources: the Boletín Oficial de la Junta de Andalucía (BOJA) and the Parlamento de Andalucía (ParlaMint-ES-AN), containing 9,776 QA pairs from BOJA and 7,892 QA pairs from ParlaMint-ES-AN, totaling 6,740 unique documents. The synthetic generation methodology, based on techniques from the Qwen3 Embeddings paper, ensures consistency and scalability in creating high-quality evaluating data.