VDC
收藏资源简介:
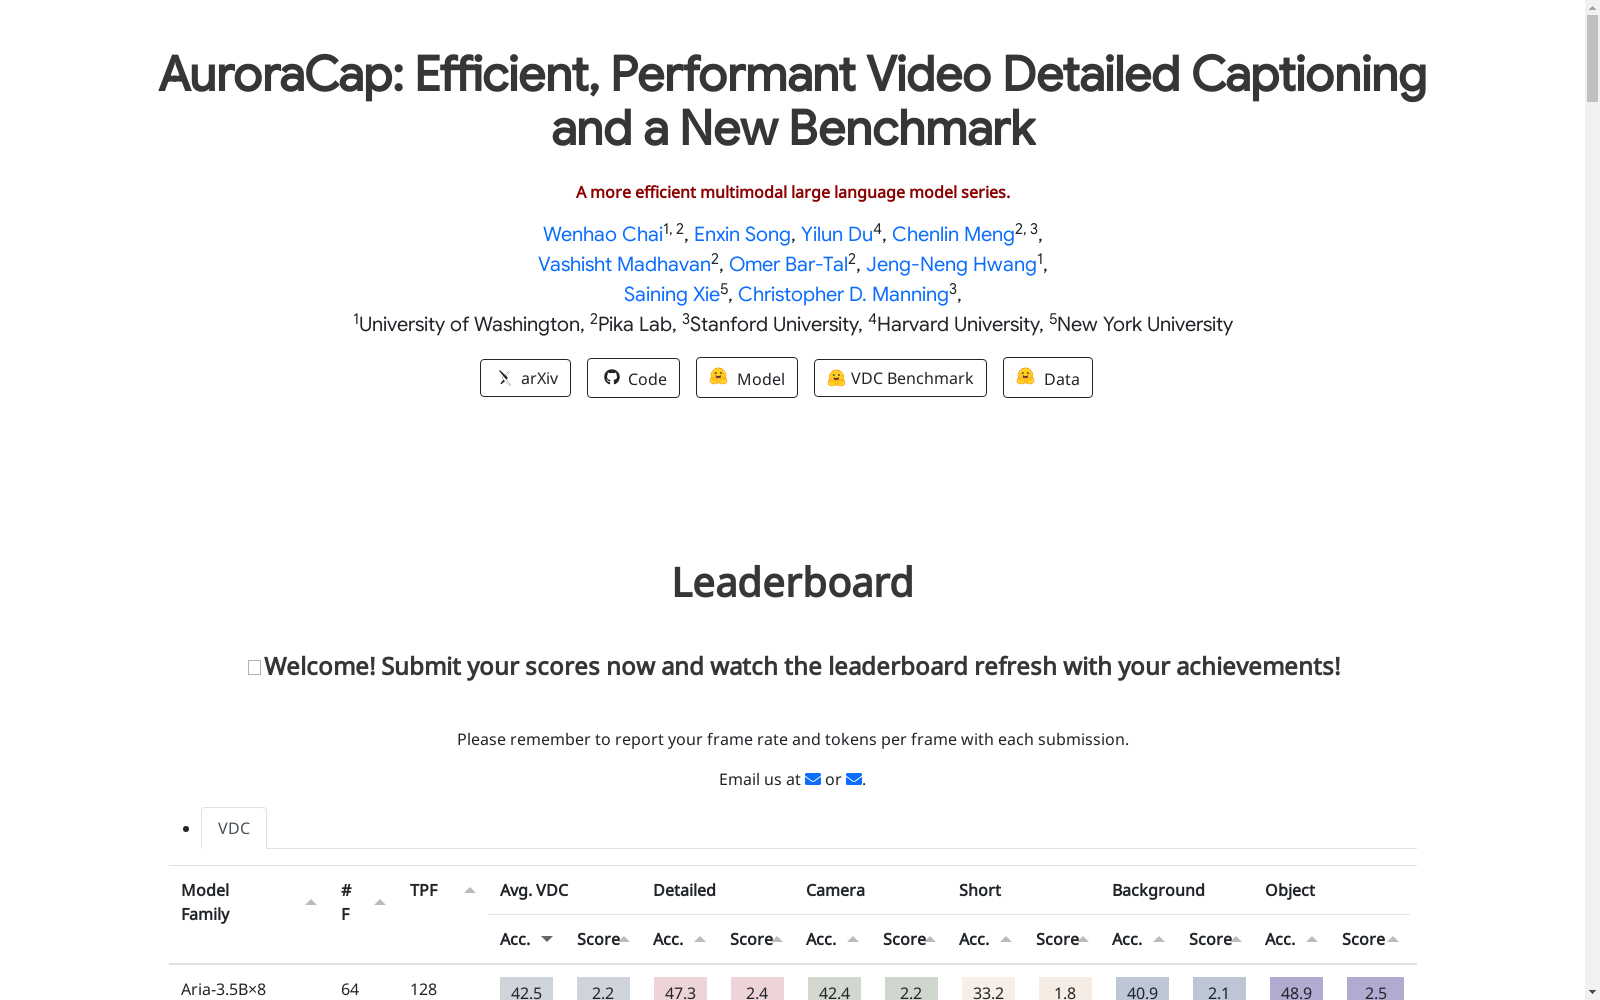
VDC数据集是由华盛顿大学等机构创建的视频详细字幕数据集,包含1027个高质量的视频-字幕对,涵盖广泛的主题。数据集通过GPT-4o进行重新标注,采用密集帧提取策略,确保字幕的详细性和时间一致性。创建过程中,通过手动质量检查确保字幕的高质量。该数据集主要应用于视频理解和生成领域,旨在解决现有数据集字幕简短、缺乏详细描述的问题。
The VDC Dataset is a video detailed caption dataset developed by the University of Washington and other institutions. It comprises 1027 high-quality video-caption pairs covering a wide range of topics. The dataset was relabeled using GPT-4o, and a dense frame extraction strategy was adopted to ensure the captions' detail and temporal consistency. During its creation, manual quality checks were performed to guarantee the high quality of the captions. This dataset is primarily utilized in the domains of video understanding and generation, with the objective of addressing the shortcomings of existing datasets, namely overly brief captions and a lack of detailed descriptions.