whowhen_pro
收藏资源简介:
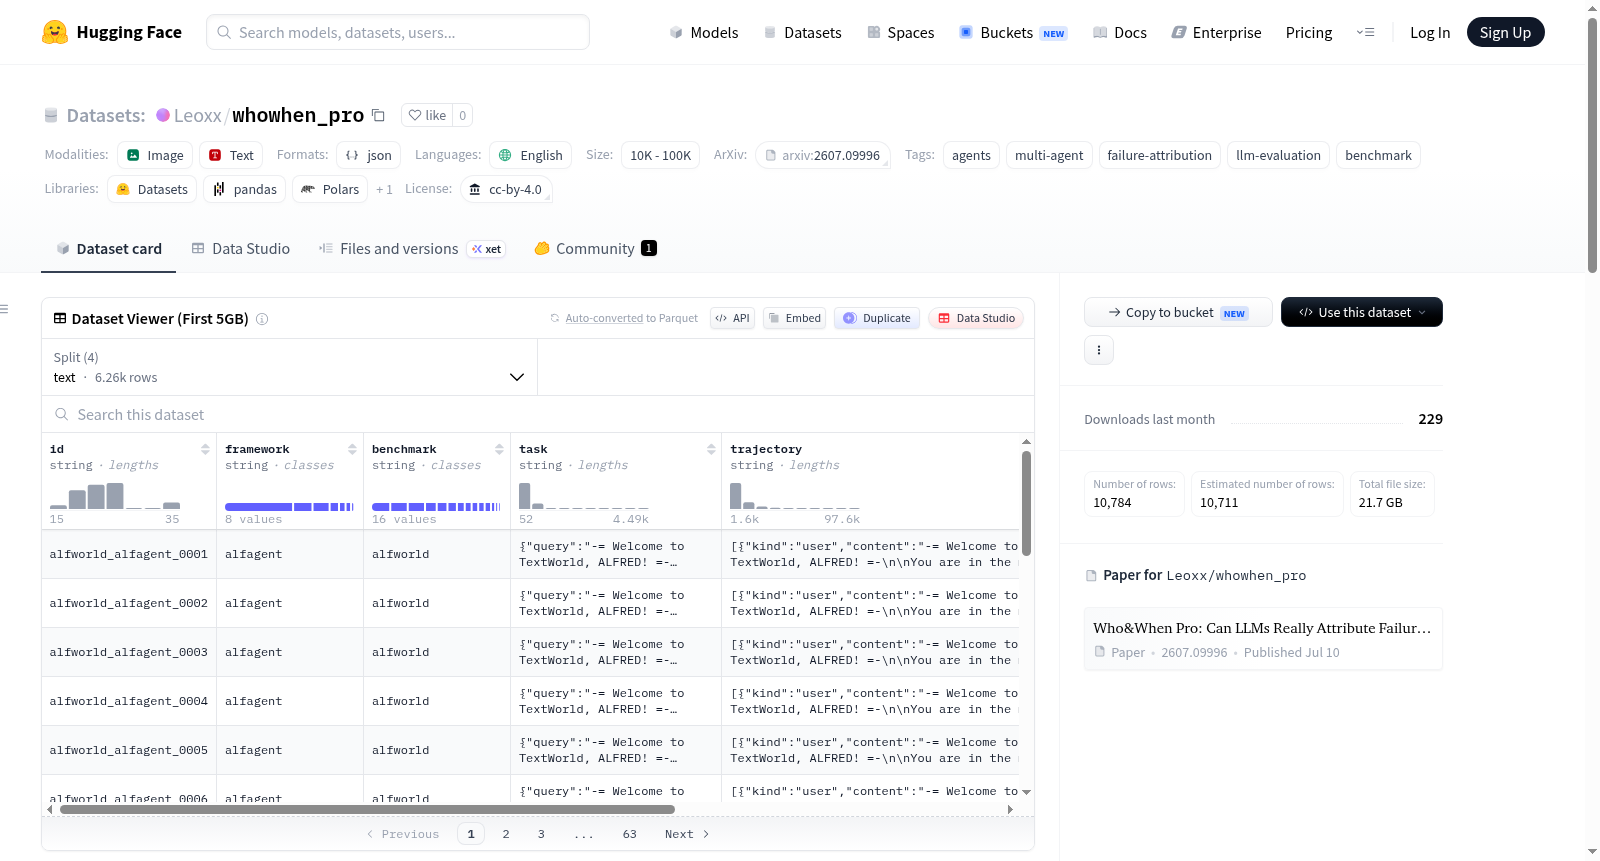
Who&When Pro 是一个用于评估大型语言模型(LLM)智能体系统失败归因能力的基准测试数据集。每个样本包含一个智能体轨迹(单智能体或多智能体),并在已知步骤中注入一个真实的错误。标签记录了错误的责任方、发生时间以及错误类型。评估时,模型需要根据轨迹恢复所有三个信息。数据集规模在10,000到100,000个样本之间,语言为英语。数据分为四个子集:text(文本工具使用轨迹)、image(图表/搜索相关轨迹)、image_gui(GUI智能体轨迹,包含完整截图观察)、video(视频智能体轨迹)。每个样本的行结构包括:id(唯一标识)、framework(使用的智能体框架)、benchmark(来源基准)、task(原始任务,含查询、参考答案、输入)、trajectory(完整智能体执行过程)、ground_truth(标签:智能体、步骤和错误模式)、extras(框架特定元数据)。其中task、trajectory、ground_truth和extras为JSON字符串,需解析后使用。image和image_gui轨迹的图片嵌入在行中;video轨迹引用video_assets/目录下的帧文件。错误分类包含6大类共17种模式:感知(视觉误识别、空间定位)、推理(幻觉、推理错误、数值错误、任务误解)、规划(无效规划、目标漂移)、行动(工具参数错误、输出格式错误、过早终止、重复循环)、验证(上下文丢失、不充分验证)、协调(委派错误、通信失败、过度依赖其他智能体)。该数据集配套有评估工具(位于GitHub),包含所有框架的渲染器和评分流水线。引用信息来自一篇arXiv论文。
Who&When Pro is a benchmark dataset for evaluating the failure attribution capabilities of large language model (LLM) agent systems. Each sample contains an agent trajectory (single-agent or multi-agent) with a real error injected at a known step. The label records the responsible party, time of occurrence, and error type. During evaluation, the model needs to recover all three pieces of information from the trajectory. The dataset size ranges from 10,000 to 100,000 samples, and the language is English. The data is divided into four subsets: text (text-based tool usage trajectories), image (chart/search-related trajectories), image_gui (GUI agent trajectories with full screenshot observations), and video (video agent trajectories). Each samples row structure includes: id (unique identifier), framework (agent framework used), benchmark (source benchmark), task (original task with query, reference answer, input), trajectory (complete agent execution process), ground_truth (labels: agent, step, and error pattern), and extras (framework-specific metadata). Among them, task, trajectory, ground_truth, and extras are JSON strings that need to be parsed before use. Images in image and image_gui trajectories are embedded in the rows; video trajectories reference frame files in the video_assets/ directory. Error classification includes 6 major categories with 17 patterns: Perception (visual misrecognition, spatial positioning), Reasoning (hallucination, reasoning error, numerical error, task misunderstanding), Planning (invalid planning, goal drift), Action (tool parameter error, output format error, premature termination, repetitive loop), Verification (context loss, insufficient verification), Coordination (delegation error, communication failure, over-reliance on other agents). The dataset is accompanied by evaluation tools (on GitHub) including renderers and scoring pipelines for all frameworks. Citation information comes from an arXiv paper.
Who&When Pro 数据集概述
基本信息
- 数据集名称: Who&When Pro
- 许可证: CC-BY-4.0
- 语言: 英语 (en)
- 数据集规模: 10K < n < 100K
- 数据集类型: LLM智能体系统失败归因基准测试
数据集简介
Who&When Pro 是一个用于 LLM 智能体系统的失败归因基准测试数据集。每条轨迹记录包含单个或多个智能体的执行路径,其中在已知步骤中注入了一个真实的错误。标签记录了谁犯的错误、何时发生的、以及错误类型。被评估模型需要根据给定轨迹恢复这三个信息。
数据组成
数据划分 (Splits)
- text: 工具使用类智能体轨迹
- image: 图表/搜索类智能体轨迹
- video: 视频智能体轨迹
- image_gui: GUI智能体轨迹,包含完整的截图观测,涵盖框架包括
coact(OSWorld, 多智能体)、openai_cua(OSWorld)、agentoccam和gemini(WebVoyager)
行结构 (Row Schema)
每条记录包含以下列:
| 列名 | 含义 |
|---|---|
id |
唯一轨迹标识 |
framework |
轨迹所属的智能体框架 |
benchmark |
来源基准测试 |
task |
原始任务:查询、参考答案、输入 |
trajectory |
完整的智能体执行过程 |
ground_truth |
标签:智能体、步骤、错误模式 |
extras |
框架特定元数据 |
错误分类体系
包含 6 大类共 17 种错误模式:
- 感知类 (Perception): 视觉误识别、空间定位错误
- 推理类 (Reasoning): 幻觉、推理错误、数值错误、任务理解错误
- 规划类 (Planning): 规划无效、目标漂移
- 行动类 (Action): 工具参数错误、输出格式错误、过早终止、重复循环
- 验证类 (Verification): 上下文丢失、验证不足
- 协调类 (Coordination): 委派错误、沟通失败、过度依赖其他智能体
评估与使用
- 数据集的评估工具包及评分流程位于 GitHub 仓库:whowhenpro/whowhen_pro
- 相关学术引用信息详见论文《Who&When Pro: Can LLMs Really Attribute Failures in AI Agents?》(arXiv preprint arXiv:2607.09996)