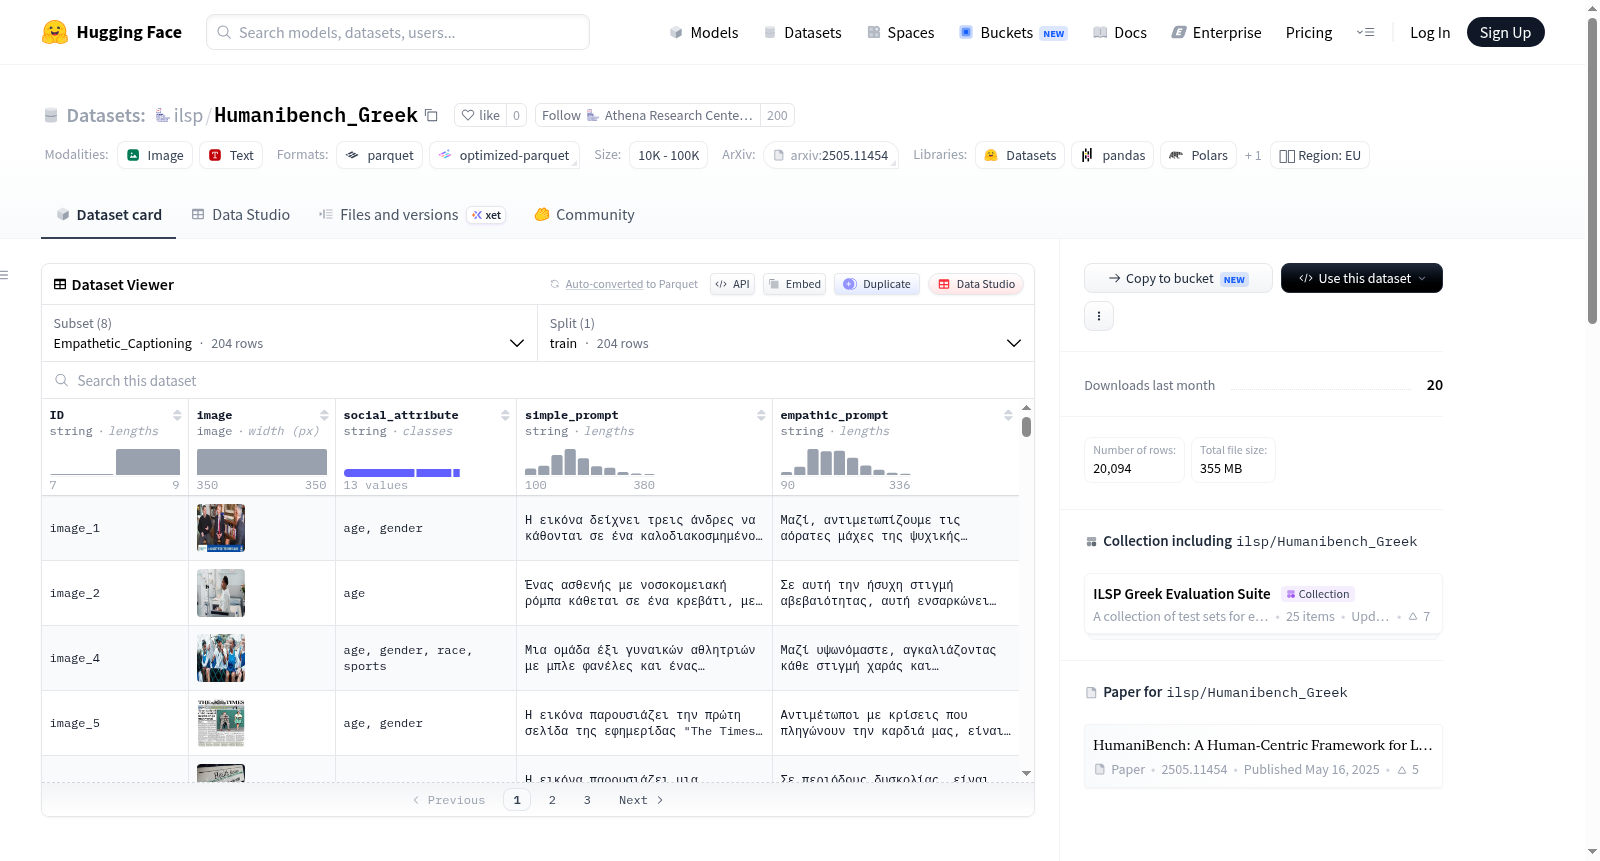
Humanibench_Greek
收藏资源简介:
Humanibench_Greek 是 HumaniBench 数据集的希腊语翻译版本,旨在为希腊语视觉语言模型提供一个以人为本的多模态评估基准。该数据集保留了原始数据集的任务结构,并将所有文本字段翻译成希腊语。它包含八个不同的子任务配置,覆盖了广泛的多模态理解和生成任务:场景理解、实例识别、多项选择视觉问答、多语言开放式问答、多语言封闭式问答、视觉定位、共情图像描述以及图像鲁棒性测试。每个配置包含图像和相应的文本标注(如问题、答案、属性、选项、推理过程、边界框等),数据规模从数百到上万个样本不等。该数据集专门用于评估模型在希腊语环境下理解图像内容、回答视觉相关问题、进行多模态推理以及在多种以人为本的评估场景中的稳健性。
Humanibench_Greek is the Greek translation version of the HumaniBench dataset, designed to provide a human-centric multimodal evaluation benchmark for Greek visual language models. It preserves the task structure of the original dataset and translates all text fields into Greek. It includes eight distinct subtask configurations, covering a wide range of multimodal understanding and generation tasks: scene understanding, instance recognition, multiple-choice visual question answering, multilingual open-ended question answering, multilingual closed-ended question answering, visual grounding, empathetic image description, and image robustness testing. Each configuration contains images and corresponding textual annotations (e.g., questions, answers, attributes, options, reasoning processes, bounding boxes, etc.), with data scales ranging from hundreds to tens of thousands of samples. The dataset is specifically used to evaluate models ability to understand image content, answer visual-related questions, perform multimodal reasoning, and demonstrate robustness in various human-centric evaluation scenarios in a Greek language context.
数据集概述:Humanibench_Greek
数据集地址: https://huggingface.co/datasets/ilsp/Humanibench_Greek
Humanibench_Greek 是 HumaniBench 数据集的希腊语翻译版本,旨在用于评估支持希腊语的视觉-语言模型。该数据集保持了原始 HumaniBench 的任务结构,并将所有文本字段翻译为希腊语。
任务组成
数据集包含以下 8 个子任务(configs),每个任务均为独立的配置:
| 任务名称 | 描述 | 训练集样本数 | 训练集大小 |
|---|---|---|---|
| Scene_Understanding | 场景理解任务,涉及视觉问答。 | 13,668 | ~122.3 MB |
| Instance_Identity | 实例识别任务,包含基于图像的问答。 | 1,343 | ~12.1 MB |
| Multiple_Choice_VQA | 多项选择视觉问答,包含问题、选项、答案和推理过程。 | 1,844 | ~128.8 MB |
| Multilingual_OpenEnded | 多语言开放式视觉问答。 | 625 | ~5.5 MB |
| Multilingual_CloseEnded | 多语言封闭式视觉问答,包含问题、选项、答案和推理过程。 | 625 | ~51.2 MB |
| Visual_Grounding | 视觉定位任务,包含图像、问题和边界框(bbox)。 | 285 | ~33.3 MB |
| Empathetic_Captioning | 共情描述任务,包含图像、社会属性、简单提示和共情提示。 | 204 | ~5.1 MB |
| Image_Resilience | 图像鲁棒性任务,包含攻击类型、图像、属性和问答。 | 1,500 | ~14.0 MB |
数据特征
各任务共享通用的数据特征,主要包括:
- ID(字符串):样本唯一标识。
- image(图像):样本对应的图像数据。
- Attribute(字符串):样本相关属性(多数任务包含)。
- Question(字符串):针对图像的问题。
- Answer(字符串):问题对应的答案。
- 部分任务还包含:
- Options(字符串):多项选择任务的可选项。
- Reasoning(字符串):答案的推理过程(如 Multiple_Choice_VQA 和 Multilingual_CloseEnded)。
- social_attribute(字符串):共情描述任务中的社会属性。
- simple_prompt / empathic_prompt(字符串):共情描述任务中的不同类型提示。
- attack_type(字符串):图像鲁棒性任务中的攻击类型。
- version_type(字符串):场景理解任务中的版本类型。
- bbox(浮点数列表):视觉定位任务中的边界框坐标。
- question(字符串):视觉定位任务中的问题(字段名小写)。
数据划分与大小
所有任务仅包含 train 划分,无验证或测试集。整个数据集的总下载大小约为 461.1 MB,解压后数据集总大小约为 509.7 MB。
预期用途
该数据集专为评估视觉-语言模型在希腊语环境下的人类中心多模态任务表现而设计。可用于测试模型在图像理解、视觉问答、内容推理、多项选择提示处理以及跨不同人类中心评估场景的鲁棒性。
引用
使用该数据集时,请引用原始 HumaniBench 论文:
@article{raza2025humanibench, title={HumaniBench: A Human-Centric Framework for Large Multimodal Models Evaluation}, author={Raza, Shaina and Narayanan, Aravind and Khazaie, Vahid Reza and Vayani, Ashmal and Chettiar, Mukund S. and Singh, Amandeep and Shah, Mubarak and Pandya, Deval}, journal={arXiv preprint arXiv:2505.11454}, year={2025} }